What Is GPT-6 Astra?
GPT-6 Astra is a multimodal reasoning model built by OpenAI. It accepts text and images, returns text, and can use tools to search the web, inspect files, execute code, operate a computer, apply patches, and connect to external systems through MCP. OpenAI describes it as a model for difficult work in coding, research, professional document creation, and computer use.
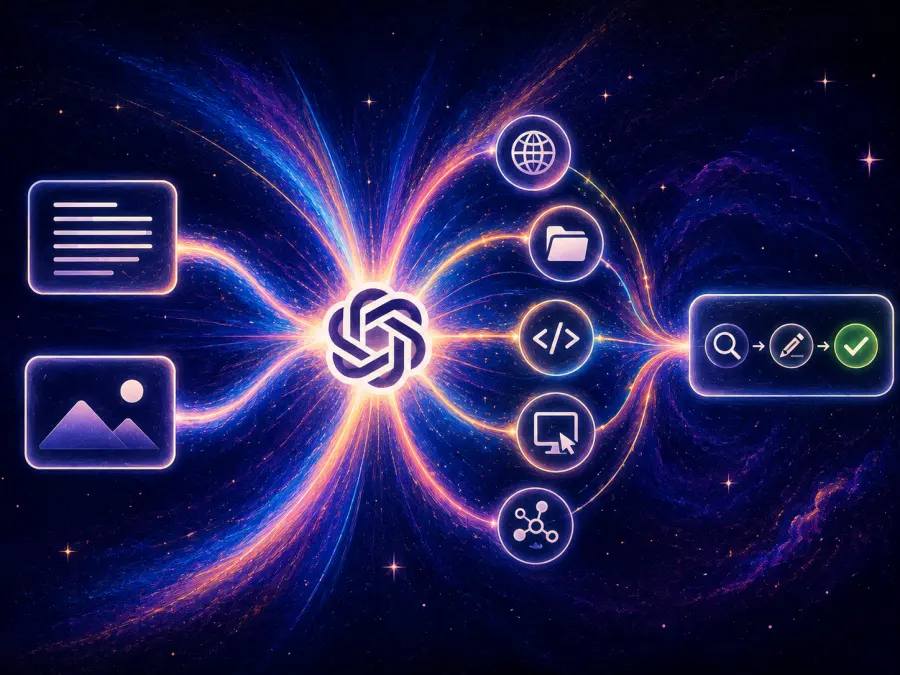
The tool layer is the important part. A chatbot might explain how to update a customer record; an Astra agent can inspect the application, make the change, and check the result—if it has the required tools and permissions.
| Specification |
GPT-6 Astra |
| Developer |
OpenAI |
| Release date |
September 3, 2026 |
| API model ID |
gpt-6-astra |
| Knowledge cutoff |
April 30, 2026 |
| Context window |
1,050,000 tokens |
| Maximum output |
128,000 tokens |
| Input |
Text and images |
| Output |
Text |
| Reasoning effort |
low, medium, high, xhigh, max |
| Function calling |
Supported |
| Structured output |
Supported |
| Fine-tuning |
Not supported |
These specifications come from the official OpenAI API model page. The page also makes an implementation detail easy to miss: Astra's built-in tools are supported through the Responses API. Basic text calls can use Chat Completions, but developers building tool-using agents should design around Responses rather than assume every tool works through the older interface.
From the Astra Research Model to GPT-6 Astra
Before launch, “Astra” referred to an internal research system associated with difficult mathematical work. Its final name, price, release date, and public availability were unknown. That description is now obsolete: Astra shipped as GPT-6 Astra with a public model ID, documentation, rate limits, tools, and pricing. The research history explains the early attention, but the commercial model is broader, covering computer use, software engineering, science, and business deliverables.
GPT-6 Astra Features and Upgrades
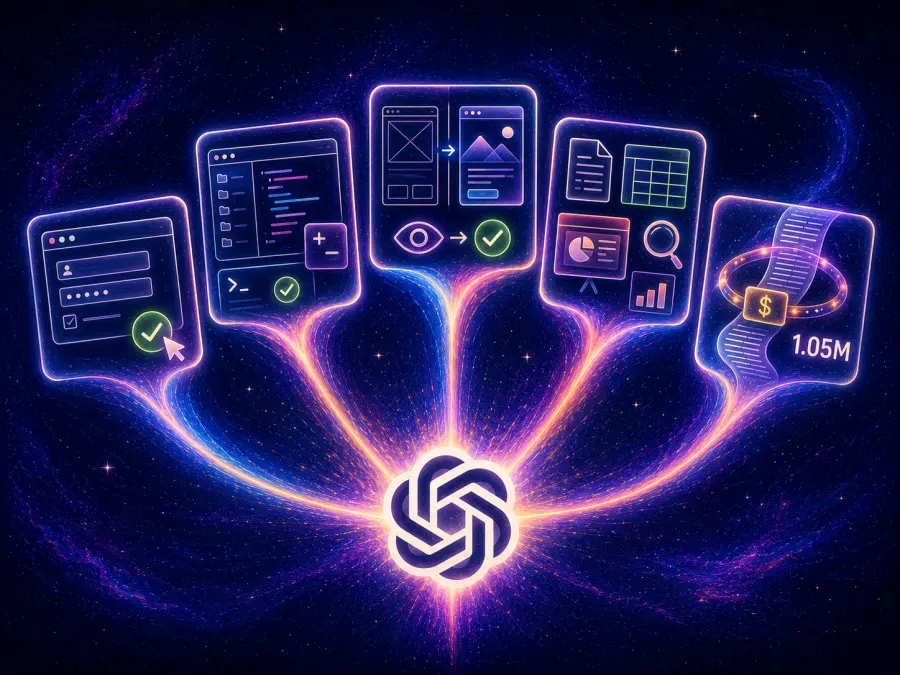
Computer use that can finish a workflow
Astra can work across browser and desktop interfaces: filling forms, updating CRM records, researching online, checking frontends, and troubleshooting software. OpenAI reports an OSWorld 2.0 score of 72.6% versus 65.7% for GPT-5.6 Sol, with about 47% less time in its simulation. Production agents still need restricted permissions, logs, approval gates, and recovery controls.
Coding beyond autocomplete
GPT-6 Astra can inspect repositories, edit multiple files, use a shell, apply patches, run tests, and iterate after errors. It scored 57.9% on Terminal-Bench 4.0 versus 37.3% for GPT-5.6 Sol and 55.8% for Claude Fable 5.1. On DeepSWE v1.1, the three scored 74.1%, 72.7%, and 67.4%. That suggests a terminal-work upgrade, not a win on every repository or harness.
Frontend coding with visual verification
Astra can accept screenshots, generate frontend code, open the result, and check whether it behaves as requested. A model that never inspects its rendered page can still ship valid React with broken spacing or interactions. Product leader Claire Vo demonstrated Astra on browser QA, a one-shot product feature, a Mac app, hardware, and Blender. Her timestamped Astra walkthrough is useful hands-on evidence, but it is one person's experience rather than a controlled benchmark.
Professional documents and research deliverables
Astra can produce documents, spreadsheets, presentations, analyses, plots, and template-based outputs. A research agent could collect sources, calculate results, build a chart, and draft the report with fewer handoffs. The tradeoff: polished formatting can make a weak assumption look authoritative, so sources and calculations still need review.
A 1.05M context window—with a price threshold
The 1,050,000-token window can hold large repositories or document sets, with up to 128,000 output tokens. Still, retrieval and filtering reduce noise and cost. On OpenAI's API, inputs above 272,000 tokens make the entire request cost 2× for input and cache and 1.5× for output—not just the tokens above the threshold.
GPT-6 Astra Pricing and Availability
OpenAI's standard text-token prices are:
| Token type |
Official price per 1M tokens |
| Input |
$10.00 |
| Cached input |
$1.00 |
| Cache writes |
$12.50 |
| Output |
$50.00 |
Batch and Flex processing cost 50% of the standard rate. Fast mode costs twice the applicable rate. Search, computer use, and other tool-specific services may add separate charges, so the text-token table is not always the full cost of an agent run.
A request using 100,000 uncached input tokens and producing 10,000 output tokens costs about $1.50 at official standard rates before tool fees: $1.00 for input and $0.50 for output. Caching, paid tools, retries, or the 272K threshold can change the bill.
GPT-6 Astra is not yet callable on GPT Proto as of September 4, 2026. Once support opens in the next few days, the planned core text rates are 10% below OpenAI's list price: $9 per million input tokens and $45 per million output tokens. Check the GPT-6 Astra model page for current availability, supported endpoints, and any separate cache or tool charges before a production rollout.
At launch, OpenAI began with a limited group of organizations and said access would expand over the following days to the API and ChatGPT Plus, Pro, Business, and Enterprise plans. If Astra does not yet appear in a particular account, that may be rollout timing rather than an incorrect model name.
GPT-6 Astra Benchmarks: What the Numbers Actually Show
The launch numbers are strong, especially in computer use, automation, terminal work, and mathematics. A compact selection is more useful than repeating every chart:
| Benchmark |
GPT-6 Astra |
GPT-5.6 Sol |
Claude Fable 5.1 |
| AutomationBench |
41.4% |
18.1% |
31.4% |
| Terminal-Bench 4.0 |
57.9% |
37.3% |
55.8% |
| DeepSWE v1.1 |
74.1% |
72.7% |
67.4% |
| FrontierMath Tier 4 v2 |
97.6% |
83.0% |
87.8% |
| Humanity's Last Exam with tools |
57.2% |
— |
65.0% |
| OSWorld 2.0 |
72.6% |
65.7% |
— |
Source: OpenAI's GPT-6 Astra launch report.
The table is not a clean sweep. Astra leads the selected automation, terminal, software engineering, mathematics, and computer-use tests, but Fable 5.1 scores higher on Humanity's Last Exam with tools. Harnesses also differ in tools, prompts, effort settings, and budgets.
Independent testing provides a correction. Artificial Analysis scores Astra and GPT-5.6 Sol equally at 61 on its Intelligence Index, five points behind Fable 5.1. Astra used about 10% fewer output tokens than Sol, yet cost about 75% more per task. On its Coding Agent Index, Astra scored 67 versus 70 for Fable 5.1, while using roughly one-third of Sol's tokens in the compared Codex harness.
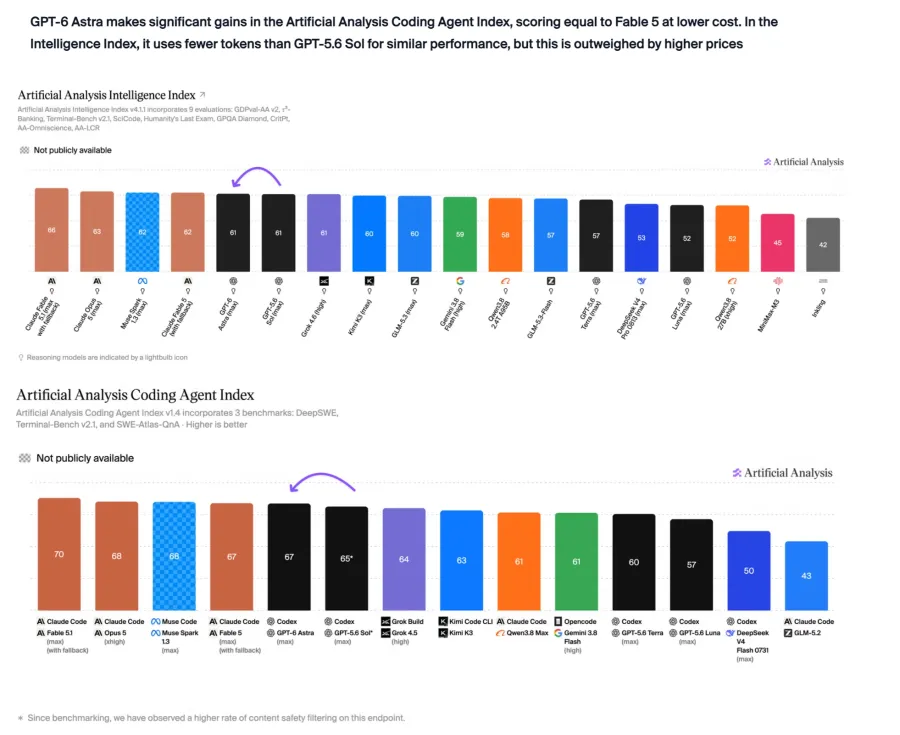
Artificial Analysis also observed a hallucination-rate drop from 92% to 51% on AA-Omniscience. That applies to one evaluation, not all work. Its broader results were mixed: long-horizon analytical quality improved, while presentation quality and several other evaluations regressed.
Is GPT-6 Astra AGI?
No public evidence proves that GPT-6 Astra is artificial general intelligence.
OpenAI president Greg Brockman suggested that Astra could mark the AGI era, ending a briefing with “Welcome to the AGI era.” That is an executive's interpretation, not a scientific certification.
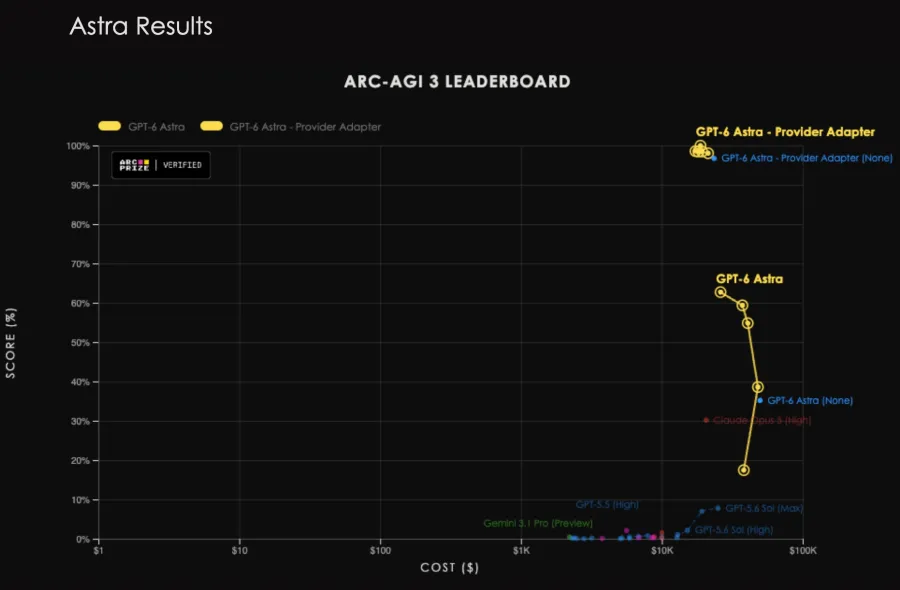
The most important evidence in the debate is ARC-AGI-3. OpenAI's headline result is 99.9%, but ARC Prize's detailed report shows two different testing conditions:
| ARC-AGI-3 setup |
Best reported Astra result |
Approximate run cost |
| Standard harness |
62.7% at max effort |
$26,098 |
| Provider Adapter harness |
99.9% at high effort |
$18,817 |
The Standard harness uses a shared interface and visible notes. The Provider Adapter preserves OpenAI's opaque reasoning state between requests and uses compaction. Both scores are legitimate, but one measures a common interface while the other includes provider-specific context management.
ARC Prize also says humans can solve 100% of the environments and explicitly states that saturating ARC-AGI-3 is not proof of AGI. The benchmark is closed-ended and deterministic; the real world is not.
My read: Astra is evidence of rapid progress in exploration, state tracking, and tool use. Calling it AGI is still a judgment.
GPT-6 Astra vs GPT-5.6 Sol, Claude Fable 5.1, GLM-5.3 Flash, and DeepSeek V4 Pro
There is no universal winner because the models sit at very different price and capability points.
| Model |
Main advantage |
Main tradeoff |
Best fit |
| GPT-6 Astra |
Computer use, automation, long tool workflows |
Expensive output and long-context surcharge |
High-value agents and end-to-end professional work |
| GPT-5.6 Sol |
Similar independent intelligence at a lower token price |
Trails Astra on several automation and computer-use tests |
Existing OpenAI workflows and cost-controlled reasoning |
| Claude Fable 5.1 |
Leads the independent Intelligence and Coding Agent indices |
High output price; does not lose every task to Astra |
Difficult reasoning and coding where its harness fits |
| GLM-5.3 Flash |
Very low price with multimodal input and long context |
Lower overall independent intelligence score |
High-volume visual coding and agent subtasks |
| DeepSeek V4 Pro |
Affordable long-context reasoning and coding |
Text-only; less evidence for browser and desktop work |
Budget-sensitive coding, math, and long text workflows |
GPT-6 Astra vs GPT-5.6 Sol
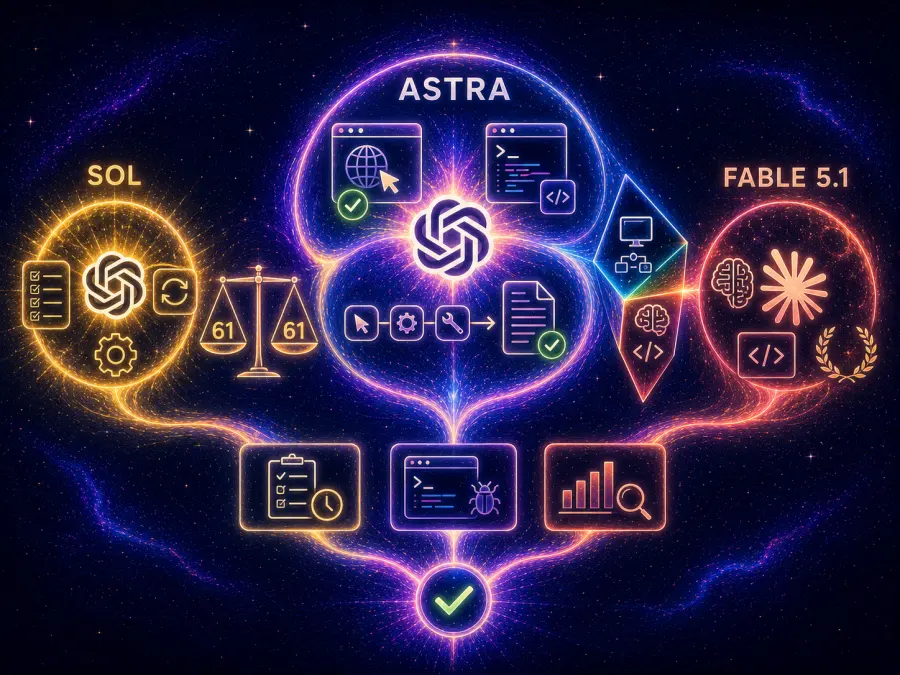
Astra is the clearer upgrade for browser work, terminal-heavy agents, and finished deliverables. But Artificial Analysis gives it the same Intelligence Index score—61—as GPT-5.6 Sol. Keep Sol for routine work and test Astra on costly failures; compare completed-task cost rather than price per token.
GPT-6 Astra vs Claude Fable 5.1
Astra has stronger launch evidence for computer use and automation, while Claude Fable 5.1 leads Astra on the Artificial Analysis Intelligence Index, 66 to 61, and the Coding Agent Index, 70 to 67. Fable also beats Astra on OpenAI's reported Humanity's Last Exam with tools result.
Choose Astra for interfaces and multi-tool workflows. Choose Fable when difficult reasoning or your coding harness favors it. Test both on your own acceptance criteria.
GPT-6 Astra vs GLM-5.3 Flash and DeepSeek V4 Pro
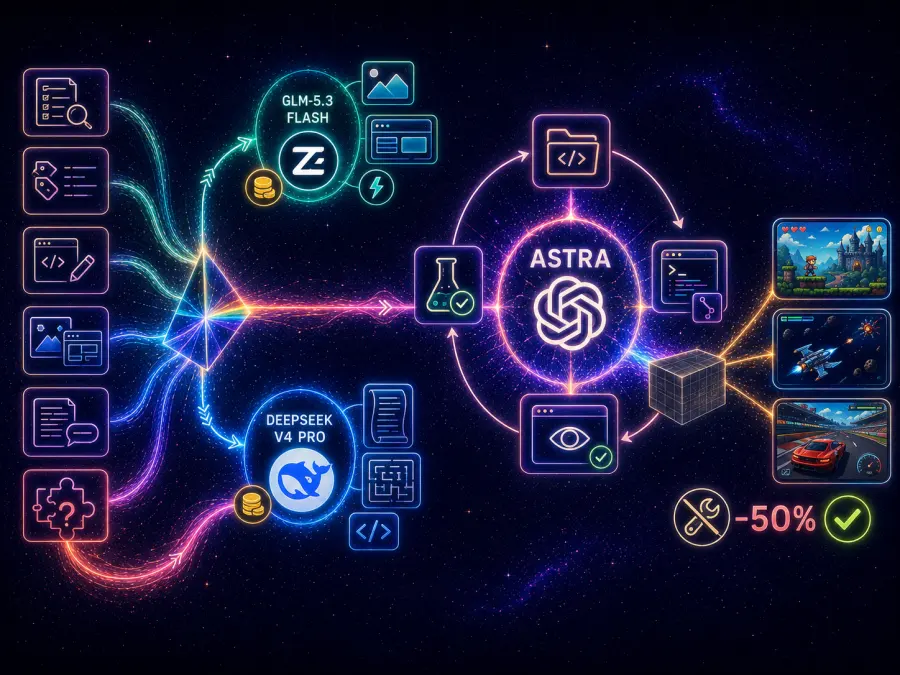
GLM-5.3 Flash and DeepSeek V4 Pro are cost alternatives, not exact Astra substitutes. GLM-5.3 Flash is attractive for frequent multimodal and frontend calls. DeepSeek V4 Pro is a better match for inexpensive text reasoning, coding, and long outputs.
A practical agent can route extraction, classification, and simple code changes to a cheaper model, then escalate ambiguous or multi-application work to Astra.
GPT-6 Astra for Coding and Frontend Development
GPT-6 Astra is most interesting for coding when the job includes execution and verification. Asking it to generate a function in isolation leaves much of the model's value unused. Give it a repository, tools, tests, a browser, and a clear definition of done.
Game studio Playco offers a concrete example. Using Astra inside its Playbot environment, the team produced three themed game prototypes from one grey-box foundation. Most worked on the first take, and Playco reported 50% fewer manual fixes than with the previous model. The system could edit scenes, play the game, validate changes, and find bugs rather than only generate source code. The Playco case study includes visual examples suitable for screenshots.
This is a partner case study, not an independent trial. Its useful lesson is the loop connecting vision, spatial reasoning, code, UI, and runtime testing.
For frontend work, use acceptance criteria that can be checked:
Match the reference layout at desktop and mobile widths.
Open every interactive state and check for overflow.
Run the existing test and lint commands.
Compare the rendered result with the supplied screenshot.
Report any requirement that could not be verified.
That creates better evidence than “make the page look modern” because the agent must show what it tested.
Is GPT-6 Astra the Best Model for Agents?
GPT-6 Astra may be one of the best models for agents that operate browsers, terminals, files, and business applications. Use it when failure is costly or the agent must inspect and correct its work. Do not default to it for classification, extraction, summaries, or repetitive calls that GLM-5.3 Flash or DeepSeek V4 Pro can handle cheaply. Fable 5.1 can also be stronger on some reasoning and coding tasks. Astra is a leading computer-use model, not a universal agent winner.
What Can You Do With GPT-6 Astra at Work?
The useful question is not “What jobs can Astra replace?” It is “Which chain of screens, files, calculations, and review steps can it complete?”
| Role |
Practical Astra workflow |
Human checkpoint |
| Developer |
Inspect a repository, implement a feature, run tests, and verify the UI |
Review the diff, security impact, and deployment plan |
| Product manager |
Research a market, draft requirements, and build a testable prototype |
Validate assumptions and prioritize scope |
| Analyst |
Combine files, run calculations, create charts, and draft a report |
Check source quality and calculations |
| Legal or operations team |
Review a document set and flag exceptions against a policy |
Make the final professional judgment |
| Sales operations |
Research accounts and prepare CRM updates |
Approve record changes and outbound actions |
| Designer |
Turn a brief or screenshot into a working frontend prototype |
Check brand consistency, accessibility, and usability |
The strongest applications have a verifiable outcome, require several steps, and are expensive to coordinate manually. “Summarize this email” rarely needs Astra. In an OpenAI customer case, Legora reviewed 41 documents in minutes and found four of four planted errors. Box reported an internal score of 77 for Astra versus 74 for Sol. These company-specific results should motivate a pilot, not replace one.
How to Use the GPT-6 Astra API on GPT Proto
Availability note (September 4, 2026): GPT-6 Astra is not yet callable on GPT Proto. Support is expected in the next few days. Save the example below for launch.
Once GPT Proto support goes live, a basic Astra text request through its OpenAI-compatible endpoint will need an API key, the GPT Proto base URL, and the model string gpt-6-astra.
curl --request POST "https://gptproto.com/v1/chat/completions" \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "model": "gpt-6-astra",
    "messages": [
      {
        "role": "system",
        "content": "You are a careful software reviewer. Separate confirmed issues from suggestions."
      },
      {
        "role": "user",
        "content": "Review this migration plan and return the three highest-risk steps with verification checks."
      }
    ]
  }'
This command will work only after Astra is enabled on GPT Proto. Set GPTPROTO_API_KEY before running it. A production computer-use agent also needs tools, restricted credentials, state management, retries, logging, and approval rules.
Visit the GPT-6 Astra API pagefor the current rate and supported request formats. If you want to compare several providers without maintaining separate balances, the broader OpenAI model collection and GPT Proto model catalog use the same account and key.
GPT-6 Astra Limitations and When Not to Use It
Astra's main limitation is economic. At $50 per million output tokens officially, long reasoning traces and agent loops can become expensive, especially above the 272K-input threshold. Latency can also rise at xhigh or max effort. Fine-tuning, audio input, and video input are unsupported. Computer use adds operational risk, so the surrounding system must control what Astra may read, change, purchase, send, or delete. Use it when failed work or manual coordination costs more than the model—not simply because it is new.
Final Verdict
GPT-6 Astra is best understood as an execution model: it combines reasoning, tools, computer use, code, and files to move difficult work closer to completion. The AGI label remains premature, and routine requests belong on cheaper models.
If your workflow stalls between “the model answered” and “the work is done,” test the same task on Astra and its alternatives. Compare accepted outputs, retries, correction time, and total cost—not just tokens or a launch-day leaderboard.
Check GPT-6 Astra availability on GPT Proto. Once access opens, compare it with your current model and keep the one that finishes your workflow with the least total friction.