Qwen3.8-Flash-Next vs GLM-5.3 Flash at a Glance
| Category |
Qwen3.8-Flash-Next |
GLM-5.3 Flash |
Current edge |
| Product status |
Experimental architecture preview |
Production API and open weights |
GLM |
| Independent Intelligence Index |
56 |
57 |
GLM, narrowly |
| Output speed on tracked first-party routes |
87.4 tokens/s |
45.2 tokens/s |
Qwen |
| Time to first token |
2.57 seconds |
1.54 seconds |
GLM |
| Native context |
262,144 tokens |
1,048,576 tokens |
GLM |
| Model size |
125B language model + 51B n-gram embeddings + 4B MTP |
320B total |
— |
| Activated parameters |
6B |
18B |
Qwen for compute per token |
| Multimodal input |
Vision encoder; serving support varies |
Text, image, video, and files |
GLM for managed use |
| Weight license |
Qwen Community License 1.0 |
MIT |
GLM |
| Production API |
Qwen points managed users to Qwen3.8-Flash |
Available as glm-5.3-flash |
GLM |
| Best fit |
Local experiments and high-throughput serving research |
Production coding and multimodal agents |
Depends on workload |
The independent numbers come from Artificial Analysis, which evaluates both models under one methodology. GLM leads its Intelligence Index 57 to 56. Qwen generates output nearly twice as fast on the tracked first-party routes, while GLM begins returning tokens sooner and provides four times the native context.
This is not a clean sweep for either model. It is a trade between Qwen's serving efficiency and GLM's more complete production package.
Flash-Next Is Not the Production Qwen3.8-Flash API
This naming detail changes the entire comparison.
The Qwen3.8-Flash-Next model card calls the release an “experimental preview” of the architecture that will underpin Qwen4. It supplies the weights and configuration for researchers and self-hosters. Its native context is 262,144 tokens, extendable to one million tokens with YaRN.
The same model card tells managed-inference users to use Qwen3.8-Flash instead. That formal version is based on Flash-Next but adds production features such as a one-million-token context by default and official built-in tools. A benchmark or price published for Qwen3.8-Flash therefore should not be silently relabeled as a Flash-Next result.
GLM-5.3 Flash has a simpler identity. The downloadable checkpoint and official API use the same model name, glm-5.3-flash. Developers can self-host it or call a managed route without first translating between an experimental checkpoint and a production sibling.
In plain language: this is partly a model comparison and partly a deployment comparison. Qwen is showing developers where its architecture is going. Z.ai is selling a model developers can put behind an API today.
Architecture: Why 6B Active Parameters Does Not Make Qwen a Small Model
Qwen3.8-Flash-Next activates only six billion parameters per token, compared with 18 billion for GLM-5.3 Flash. That helps explain its throughput advantage, but it does not mean the Qwen checkpoint occupies the memory of a conventional 6B model.
According to Qwen's model card, Flash-Next contains a 125B-parameter language model, a 51B-parameter n-gram embedding table, and a 4B-parameter multi-token prediction component. Its 48 layers repeat three Gated DeltaNet blocks followed by one Qwen Sparse Attention block. Only a subset of experts runs for each token, but the inactive experts and n-gram table still need to live in memory, storage, or an offloading system.
The n-gram table is the unusual part. It stores representations for common short token patterns so the main network does not spend the same compute rebuilding them. Qwen designed it to be easier to offload than normal MoE weights. The trade-off is that serving efficiency now depends heavily on RAM capacity, SSD bandwidth, quantization, memory mapping, and inference-engine support.
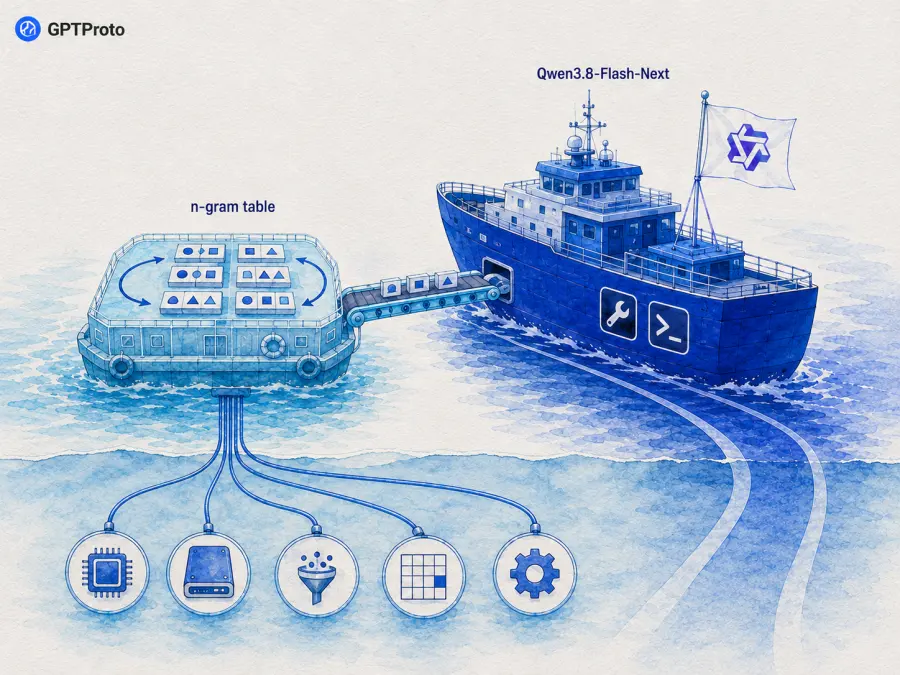
Early community reports illustrate the difference. Some four-bit configurations occupied around 100GB. A pageable quantized setup reduced resident memory to roughly 65GB, while other users ran the model on 96GB hardware by placing part of the n-gram table on SSD. Those are promising results, but they require substantially more work than loading a normal 6B checkpoint.
GLM-5.3 Flash is larger: 320B total parameters with about 18B active per token. Z.ai combines linear attention, sparse attention, and Manifold-Constrained Hyper-Connections across 45 layers. The model was trained on a 30-trillion-token multimodal corpus and natively accepts text, images, video, and files.
The practical conclusion is simple. Qwen spends less compute per generated token, but its full memory footprint is not small. GLM requires more substantial self-hosting infrastructure, yet API users do not have to operate that infrastructure at all.
Benchmarks: GLM Leads, but Not by Enough to End the Debate
Vendor benchmark tables are useful for understanding what each lab optimized. They are poor evidence for declaring a universal winner when the evaluation frameworks, prompts, tools, context settings, and scoring rules differ.
Artificial Analysis provides the cleaner comparison:
| Independent metric |
Qwen3.8-Flash-Next |
GLM-5.3 Flash |
Interpretation |
| Intelligence Index |
56 |
57 |
Effectively close |
| Output speed |
87.4 tokens/s |
45.2 tokens/s |
Qwen returns generated tokens faster |
| Time to first token |
2.57 seconds |
1.54 seconds |
GLM starts sooner |
| Blended price per 1M tokens |
$0.09 |
$0.10 |
Near tie under the 7:2:1 blend |
| Native context |
256K |
1M |
GLM holds more context without extrapolation |
A one-point Intelligence Index lead is evidence that GLM is competitive, not evidence that Qwen loses every task. It also matters that Qwen used more output tokens in the evaluation: Artificial Analysis reports about 200M for Qwen versus 150M for GLM. A model can have a low advertised token rate and still cost more per completed workflow if it reasons for longer.
The official coding and agent results point in the same general direction but need more caution:
| Vendor-reported benchmark |
Qwen3.8-Flash-Next |
GLM-5.3 Flash |
Comparison warning |
| DeepSWE 1.1 |
58.7 |
63.4 |
Evaluation setup must be checked |
| NL2Repo |
48.1 |
56.3 |
Reported by different vendors |
| Toolathlon Verified |
73.5 |
78.4 |
GLM reports Pass@1 averaged across three runs |
| Agents' Last Exam |
24.3 Pass@1 |
26.3 |
Do not compare Qwen's separate 51.2 score with Pass@1 |
One comparison that should not appear in a serious article is Qwen's HLE score of 35.9 against GLM's HLE with Tools score of 55.3. They have similar labels but different conditions. The 19.4-point gap looks dramatic only because the table hides the tool setting.
My reading of the evidence: GLM has a small quality advantage today. Qwen has a clear throughput advantage on the measured route. Neither difference removes the need to test the models on the actual repository, tool schema, and acceptance criteria that will determine whether an agent succeeds.
Qwen3.8-Flash-Next vs GLM-5.3 Flash for Coding
For repository-level coding, GLM-5.3 Flash is the safer default. It leads the vendor-reported DeepSWE and NL2Repo results, offers native one-million-token context, and is already exposed through a formal API with function calling and structured output.
That combination matters more than a few benchmark points. A coding agent must repeatedly read files, preserve constraints, call tools, recover from errors, and keep working after the first patch fails. A model that generates tokens quickly but requires an immature serving integration can lose its advantage once the complete agent loop is counted.
Qwen3.8-Flash-Next still has an appealing coding role: scout or subagent. Its higher generation throughput makes it a plausible choice for repository exploration, proposing several approaches, drafting isolated functions, or running parallel low-risk tasks. Teams that already manage local inference may accept the additional setup in exchange for control over quantization and hardware placement.
The decision is therefore not “GLM codes and Qwen does not.” Both can code. Choose GLM when task completion and managed integration come first. Choose Qwen when fast local exploration and infrastructure control justify the engineering work.
Which Model Is Better for Frontend Coding?
There is not yet a large independent frontend benchmark that cleanly compares these exact releases. One useful community experiment does show why simple coding scores miss part of the story.
A LocalLLaMA user gave quantized versions of both models the same reference image and asked each to reproduce it as a video game or technical demo, iterating for up to about 90 minutes. The user reported that GLM's result was closer to the reference scale and more detailed from the beginning. Qwen took a more unusual route and wrote a software renderer from scratch, while GLM used Canvas 2D.
After one requested console-error fix, GLM extended its result into a playable pixel-art walking simulator. The run consumed about 238K tokens and roughly two hours in total. That is impressive persistence, but it also shows the cost of long-horizon frontend generation: a successful demo can consume far more output than a token-rate table implies.
The experiment does not prove that GLM will beat Qwen on every React dashboard, Three.js scene, or Vue component. The models also chose different technical approaches, which makes the outputs difficult to score on one axis. Still, the result offers a practical early signal:
Choose GLM when visual fidelity, screenshot matching, and iterative completion matter most.
Test Qwen when an unconventional implementation or locally generated alternatives may be valuable.
For now, GLM-5.3 Flash wins the frontend category provisionally. The word “provisionally” matters.
Qwen3.8-Flash-Next vs GLM-5.3 Flash for Agents
GLM has the stronger production-agent case. Its official API supports function calling, context caching, structured output, streaming responses, and streamed tool arguments. Its native one-million-token window provides more space for repositories, tool results, system instructions, and a long interaction history without relying on context extrapolation.
Its benchmark profile also supports that positioning. Z.ai reports 78.4 on Toolathlon Verified and 26.3 on Agents' Last Exam. Those remain vendor-reported results, but they align with the independent one-point Intelligence Index lead and the community report of sustained frontend iteration.
Qwen's advantage is throughput. A local agent that calls the model frequently for short planning, search, classification, or draft-generation steps could benefit from faster decoding. Flash-Next is also useful for teams studying how sparse attention and n-gram embeddings behave during long agent runs.
The limitation is product layering. The built-in tools and default one-million-token context promoted for Qwen3.8-Flash belong to the production sibling, not automatically to every self-hosted Flash-Next deployment. With the open checkpoint, function calling, JSON reliability, context scaling, and serving stability depend partly on the inference stack and templates the developer chooses.
For long-running production agents, select GLM. For an experimental local subagent, Qwen deserves a test.
Speed, Context, and Local Deployment
The word “Flash” does not guarantee the same kind of speed.
On the first-party routes tracked by Artificial Analysis, Qwen3.8-Flash-Next generated 87.4 tokens per second, compared with 45.2 for GLM-5.3 Flash. GLM nevertheless had the lower time to first token: 1.54 seconds versus 2.57 seconds. Qwen was faster once it started; GLM started sooner.
Hosting can reverse or amplify these results. Artificial Analysis has measured GLM routes ranging from roughly 45 to more than 290 output tokens per second. The model weights are only one component. Hardware, batching, quantization, speculative decoding, load, and serving software all affect the number a user finally sees.
A separate community NVFP4 test reported the following local figures:
| Local test |
Qwen3.8-Flash-Next |
GLM-5.3 Flash |
| Single stream |
47.6 tokens/s |
21.9–33.3 tokens/s |
| TTFT |
0.16 seconds |
0.43 seconds |
| Four concurrent streams, aggregate |
119.1 tokens/s |
50.6 tokens/s |
These figures came from one hardware and quantization setup. They support Qwen's efficiency story, but they should not be presented as universal API performance.
Context is less ambiguous. Qwen natively supports 262,144 tokens and can extend to one million with YaRN. GLM natively supports 1,048,576 tokens and up to 131,072 output tokens. For a repository plus tool history that genuinely exceeds 256K, GLM offers the cleaner boundary. For a normal coding prompt, an unused one-million-token window provides no automatic quality gain.
Pricing: Which Model Is More Cost-Effective?
Pricing needs three labels: experimental checkpoint, tracked hosted route, and production sibling. Collapsing them creates a misleading table.
| Model or route |
Input per 1M tokens |
Output per 1M tokens |
Important qualification |
| Qwen3.8-Flash-Next, route tracked by Artificial Analysis |
$0.15 |
$0.47 |
Observed hosted route, not a durable Flash-Next list price |
| GLM-5.3 Flash, official standard price |
$0.15 |
$0.50 |
Excludes temporary launch promotion |
| GLM-5.3 Flash on GPT Proto |
$0.135 |
$0.45 |
10% below the official standard price |
Z.ai is also running a temporary launch promotion of $0.075 per million input tokens and $0.25 per million output tokens through September 9, 2026. Anyone buying direct during that window should use the promotional figures. For a comparison intended to remain useful after launch week, the standard price is the better baseline.
Consider a coding-agent workload that processes 10M input tokens and generates 2M output tokens, excluding cache charges:
Qwen tracked route: 10 × $0.15 + 2 × $0.47 = $2.44
GLM official standard rate: 10 × $0.15 + 2 × $0.50 = $2.50
GLM through GPT Proto: 10 × $0.135 + 2 × $0.45 = $2.25
Under those hosted rates, GPT Proto's GLM route costs $0.19 less than the tracked Qwen route for the same token volume. The saving is real but modest. A single retry or an extra 100K reasoning tokens can matter more.
Self-hosting changes the accounting rather than eliminating it. Qwen's six-billion-parameter activation should reduce compute per token, but the team still pays for GPUs, RAM, SSD capacity, power, engineering time, monitoring, and idle capacity. GLM's larger checkpoint raises that infrastructure floor further. At low or uneven traffic, an API will often cost less than operating either model. At sustained high utilization, local Qwen can become attractive—provided its license covers the product.
For hosted use in this comparison, GLM through GPT Proto is the cost-effective choice. For self-hosting, no honest winner can be named without the hardware, utilization, quantization, and staffing assumptions.
License and Production Risk
Both models publish downloadable weights. Only one uses a standard permissive software license.
GLM-5.3 Flash is released under MIT. Developers can use, modify, distribute, and commercially host it while retaining the required copyright and license notice.
Qwen3.8-Flash-Next uses the Qwen Community License 1.0. The license permits many commercial uses, but it adds conditions that matter to API and agent businesses. Products exceeding 100 million monthly active users or $20 million in monthly revenue must prominently display the model name. More importantly, a licensee conducting a Model-as-a-Service or AI Work Assistant business must obtain a separate license from Qwen before using the software commercially, except for internal use that does not expose the model, its outputs, or its capabilities to third parties.
That does not make Qwen unusable. It does mean “open weights” should not be translated into “unrestricted commercial hosting.” A team building an internal analysis tool faces a different license question from a team selling an API or public coding assistant.
| Commercial question |
Qwen3.8-Flash-Next |
GLM-5.3 Flash |
| Downloadable weights |
Yes |
Yes |
| Standard permissive license |
No |
Yes, MIT |
| MaaS/API resale |
Separate Qwen license required |
Permitted under MIT conditions |
| AI Work Assistant business |
Separate Qwen license required |
Permitted under MIT conditions |
| Large-product display requirement |
Applies above stated thresholds |
No equivalent product threshold |
For a public API, commercial agent platform, or coding assistant, GLM has the clearer deployment path.
Which Model Should You Choose?
| Use case |
Recommended model |
Why |
| Production coding API |
GLM-5.3 Flash |
Formal API, native 1M context, MIT license |
| Long-running tool agent |
GLM-5.3 Flash |
Larger native context and mature API features |
| Screenshot-to-code workflow |
GLM-5.3 Flash, provisionally |
Better visual fidelity in one early community test |
| High-throughput local generation |
Qwen3.8-Flash-Next |
Higher measured decoding speed and 6B active parameters |
| Architecture research |
Qwen3.8-Flash-Next |
Preview of Qwen's next architecture |
| Local scout or subagent |
Qwen3.8-Flash-Next |
Fast generation can suit parallel exploratory work |
| MaaS or public AI assistant |
GLM-5.3 Flash |
Qwen's checkpoint license requires separate permission |
| Lower hosted rate in this comparison |
GLM on GPT Proto |
$0.135/M input and $0.45/M output |
GLM-5.3 Flash is the better default for most developers choosing an API today. Qwen3.8-Flash-Next is the more interesting experiment, but it is not the more complete production product.
How to Try GLM-5.3 Flash Through GPT Proto
GPT Proto exposes GLM-5.3 Flash through an OpenAI-compatible chat-completions endpoint. Create an account, add balance, generate an API key, and send the following request:
curl --request POST "https://gptproto.com/v1/chat/completions" \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "model": "glm-5.3-flash",
    "messages": [
      {
        "role": "user",
        "content": "Review this JavaScript function, identify the bug, and return a corrected version."
      }
    ]
  }'
Keep the model ID in configuration rather than hard-coding it throughout the application. That makes it easier to run acceptance tests, compare another model later, or route difficult requests differently.
GPT Proto currently provides the GLM-5.3 Flash route discussed in this article. This comparison does not imply that GPT Proto hosts Qwen3.8-Flash-Next.
Start testing GLM-5.3 Flash at $0.135/M input and $0.45/M output.
Final Verdict
GLM-5.3 Flash wins this comparison for production use. Its independent Intelligence Index lead is only one point, so raw intelligence is not the decisive advantage. The stronger case is operational: a formal API, native one-million-token context, broad multimodal input, mature agent features, and an MIT license.
Qwen3.8-Flash-Next wins on measured output speed and architectural novelty. It is a compelling option for researchers, self-hosters, and teams prepared to tune an early inference stack. Its six-billion activated parameters are meaningful, but the 51B n-gram table prevents it from behaving like a small 6B checkpoint in memory.
If I were selecting a model for a production coding or agent API today, I would start with GLM and test Qwen as a local experimental alternative. If I were studying next-generation sparse architectures or building a high-throughput local scout, I would reverse that order.