Several pages published immediately after DeepSeek V4 Flash Vision Exp launched are already quoting the wrong price. That is how quickly this release is moving.
DeepSeek V4 Flash Vision Exp is an experimental version of V4 Flash that can accept images alongside text. It can inspect screenshots, read text in images, analyze charts, and pass the result to tools. DeepSeek released it on August 21, 2026 under the model ID deepseek-v4-flash-vision-exp. 
The important distinction is what it is not. This is not a new image generator, and it is not a blanket upgrade for every V4 Flash workload. DeepSeek positions it as a vision-enabled experimental branch with roughly the same text capabilities as V4 Flash. If your application never sends an image, the standard text model remains the simpler choice.
DeepSeek V4 Flash Vision Exp is now available through GPTProto. Developers can send text and image input through the model’s GPTProto route using the same account, API key, and shared balance used for other supported models. The live model page currently lists standard pricing of $0.44 per million input tokens and $1.32 per million output tokens, with time-based off-peak rates also available.
The model remains experimental. Before routing production traffic to it, test the exact image format, request limits, latency, and fallback behavior shown in GPTProto’s live Quick Start.
What Changed From DeepSeek V4 Flash?
The upgrade is narrow but useful: V4 Flash can now receive visual context. A request may contain text plus one or more JPEG, PNG, GIF, or WebP images. DeepSeek exposes that capability through its OpenAI-compatible Chat Completions and Responses APIs as well as its Anthropic-compatible Messages API.
Images can arrive in three ways:
A Base64 data URL embedded in the request.
A publicly accessible HTTP or HTTPS URL.
A file_id created through the Files API.
The third option matters when an agent needs to inspect the same screenshot more than once. Upload it once, reuse the identifier, and avoid sending the entire file with every request. DeepSeek says Files API uploads are free, but inference is not: the image is still converted into input tokens and billed with the accompanying text.
Here is the practical split between the three current V4 routes:
| Model |
Image input |
Official context / max output |
Peak cache-miss input / output |
Practical fit |
| DeepSeek V4 Flash Vision Exp |
Yes |
1M / 384K |
$0.44 / $1.32 per 1M tokens |
Screenshot, chart, document-image, and GUI-agent experiments |
| DeepSeek V4 Flash |
No |
1M / 384K |
$0.44 / $1.32 per 1M tokens |
High-volume text, extraction, chat, and routine agent subtasks |
| DeepSeek V4 Pro |
No |
1M / 384K |
$1.32 / $3.96 per 1M tokens |
Harder coding, reasoning, and longer agent tasks |
Those are the current official peak rates, not a promise that pricing will remain unchanged. DeepSeek explicitly reserves the right to adjust them.
My practical read is simple. Choose Vision Exp because you need image input, not because Vision sounds like a higher tier. Choose V4 Flash when the work is text-only and cost-sensitive. Move difficult text tasks to V4 Pro when the added reasoning quality is worth roughly three times the official token price.
DeepSeek V4 Flash Vision Exp Features—and Its Real Limits
The short feature list looks generous: mixed text and images, tool calls, JSON output, selectable thinking mode, three API formats, and the same 1M-token context shown for the other V4 models. The limits are what determine whether those features survive contact with a production workload.
| Input method |
Limit |
Best use |
Base64 or inline file_data |
Entire request body: 48 MiB |
Local images and single-use requests |
| External URL |
URL: 8,192 characters; image: 32 MiB; download: 60 seconds |
Public images that are already hosted |
Files API file_id |
Image: 64 MiB |
Reused images or requests that would exceed the inline body limit |
Image placement depends on the API format. In Chat Completions and Anthropic-compatible Messages requests, image content belongs in a user message. The Responses API can also receive images in developer messages and in supported tool-call outputs. Images placed in system or assistant messages return a 400 error. Sending an image to the text-only V4 Flash or V4 Pro routes also returns an error because those models do not accept native image input.
Vision Exp supports low, high, original, and auto detail settings for image_url inputs, but the model still applies its documented resizing process. Images below roughly 384×384 total-pixel scale are enlarged. Larger images are reduced while preserving aspect ratio until their total pixel count is roughly equivalent to 800×800.
That resizing produces a ceiling of 384 input tokens per image. It makes the cost predictable. The trade-off is resolution: tiny labels, dense spreadsheets, fine diagram annotations, and small UI text may not survive the reduction. A 5,000×5,000 source does not buy more image tokens than a 2,000×2,000 source.
One more boundary is easy to miss. Vision Exp does not support FIM completion, while V4 Flash and V4 Pro support it in non-thinking mode. Developers building inline code-completion tools should not treat the vision route as a drop-in replacement.
DeepSeek V4 Flash Vision Exp Pricing
I checked DeepSeek's live pricing table on August 24, 2026. The rates are:
| Token type |
Off-peak |
Peak |
| Cache-hit input |
$0.007 per 1M |
$0.014 per 1M |
| Cache-miss input |
$0.22 per 1M |
$0.44 per 1M |
| Output |
$0.66 per 1M |
$1.32 per 1M |
Peak hours run from 01:00–04:00 and 06:00–10:00 UTC, Monday through Friday. Every other period, including weekends, uses the half-price off-peak rate.
Some recently indexed explainers still quote $0.14 per million input tokens and $0.28 per million output tokens. Do not build a budget around those figures. They no longer match the official table.
At the documented 384-token image ceiling, the image-only input calculation is:
Off-peak: 384 × $0.22 / 1,000,000 = $0.00008448 per image
Peak:     384 × $0.44 / 1,000,000 = $0.00016896 per image
That works out to approximately $0.08448–$0.16896 for 1,000 images before text and output. It is cheap, but the headline can be misleading. A 1,000-token answer costs $0.00132 at the peak output rate—nearly eight times the maximum input charge for one image. Concise responses and controlled max_tokens may matter more than squeezing a few tokens out of the picture.
The 384 figure is also a maximum, not a flat per-image charge. Actual token use depends on the dimensions after DeepSeek's resizing step.
DeepSeek V4 Flash Vision Exp vs Opus 4.8
DeepSeek says Vision Exp brings multimodal-agent performance close to Opus 4.8. Its own benchmark chart supports a narrower statement: the models trade wins across four selected multimodal-agent evaluations.
| Multimodal-agent benchmark |
Vision Exp |
Opus 4.8 |
Higher score |
| ApexBench, Pass@1 |
36.5 |
39.4 |
Opus 4.8 |
| Agents' Last Exam |
27.3 |
25.7 |
Vision Exp |
| Chartography |
64.3 |
65.0 |
Opus 4.8 |
| ZeroBench, Pass@5 |
35.0 |
34.0 |
Vision Exp |
Two wins each. That is competitive, but it is not proof that Vision Exp matches Opus 4.8 across OCR accuracy, visual hallucination rates, small-text reading, UI navigation, or long-running agents.
The text-agent results add more context. DeepSeek's chart contains seven text-based evaluations. Vision Exp leads Opus 4.8 only on DeepSWE, 59.3 to 58.0. It trails on Terminal Bench 2.1, NL2Repo, Cybergym, Toolathlon-Verified, DSBench-Hard, and AutomationBench.
These figures also come from DeepSeek, not an independent evaluator. The company ran its models in Minimal Mode with maximum output length, top_p=0.95, and temperature=1.0. As of August 24, I could not find Vision Exp in Artificial Analysis or LMArena results. My conclusion is therefore provisional: the launch data justifies testing the model, not declaring an overall winner.
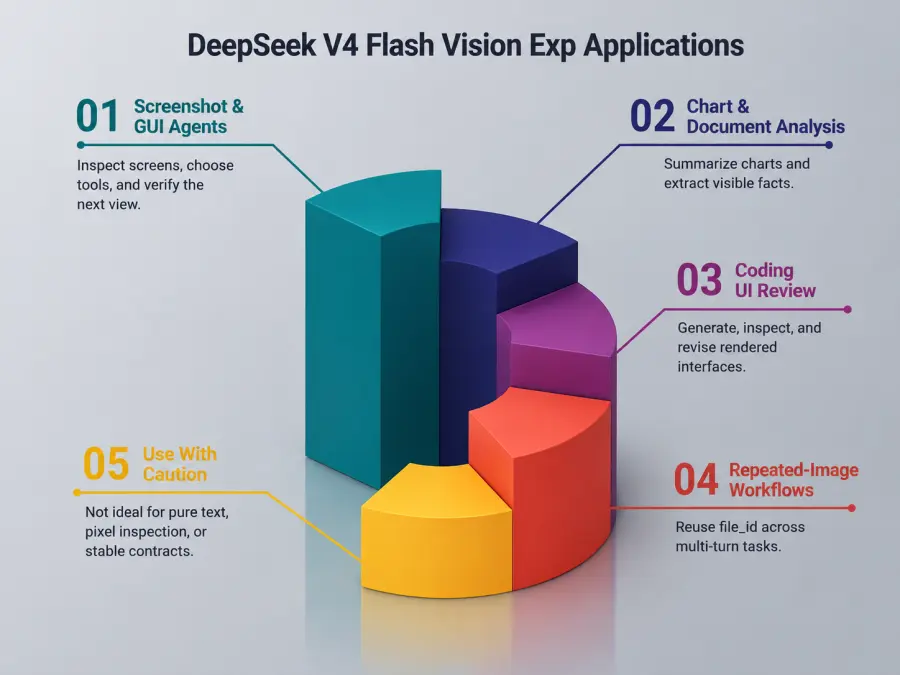
DeepSeek V4 Flash Vision Exp Applications
Screenshot and GUI agents
A browser or desktop agent can inspect a screen, decide which tool to call, and review the next screenshot. The low image-token ceiling keeps repeated observations inexpensive. The cost is visual precision, so test small labels, error text, and dense menus before trusting autonomous clicks.
Chart and document-image analysis
The model can summarize charts, extract visible facts, and combine them with text instructions. It should work best on clean, legible pages. Scanned fine print and large spreadsheets are riskier because images are resized before inference.
Coding agents that review interfaces
A coding agent can generate a page, inspect the rendered result, then revise the code. That closes a gap left by text-only V4 Flash. Still, a screenshot is not a DOM tree: the model may notice a misplaced button without identifying the exact CSS rule that caused it.
Repeated-image workflows
The Files API suits product catalogs, document review, or any flow that refers to one image across several turns. Reusing a file_id saves request bandwidth. It does not remove image-token charges when the model processes that file again.
When not to use it
Vision Exp is a weak default for pure text, pixel-level inspection, or systems that require a stable model contract. The -exp suffix matters. Keep regression tests, log model behavior, and maintain a fallback route if a visual workflow affects money, permissions, or customer data.
How to Use DeepSeek V4 Flash Vision Exp via API
DeepSeek V4 Flash Vision Exp is available through GPT Proto’s OpenAI-compatible endpoint. The following Python example sends a public chart image together with a text instruction:
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["GPTPROTO_API_KEY"],
    base_url="https://gptproto.com/v1",
)

response = client.chat.completions.create(
    model="deepseek-v4-flash-vision-exp",
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "text",
                    "text": "Read this chart and list the three most important findings."
                },
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://api-docs.deepseek.com/img/v4_260821_benchmark_en.png"
                    }
                }
            ]
        }
    ],
)

print(response.choices[0].message.content)
The example uses DeepSeek's public benchmark image, so it can be run without preparing an image first. For a local file, encode it as a Base64 data URL; for a large or repeatedly used file, upload it first and send its file_id. DeepSeek's Vision API guide documents all three formats.
Using Vision Exp Through GPT Proto
GPT Proto now exposes DeepSeek V4 Flash Vision Exp as a multimodal route with text and image input and text output. The current standard rate is $0.44 per million input tokens and $1.32 per million output tokens. Image tokens are added to the text-input bill, with DeepSeek documenting a ceiling of 384 input tokens per image.
The practical advantage is account consolidation: the same GPT Proto key and shared balance can also call text-only DeepSeek V4 Flash and DeepSeek V4 Pro. That makes it easier to route visual tasks to Vision Exp while keeping routine text work on the stable Flash model.
Is DeepSeek V4 Flash Vision Exp Worth Using?
Yes—for testing image-aware agents where input cost and repeated screenshots matter. No—as an automatic upgrade for a text-only application.
The confirmed strengths are broad API compatibility, predictable image-token usage, a 1M-token context, and vendor-reported results that are at least competitive with Opus 4.8 on four multimodal-agent tests. The costs are an experimental contract, aggressive image resizing, no independent benchmark result yet, and mixed performance against Opus rather than a clean win.
If your workload is text-only, start with DeepSeek V4 Flash and escalate difficult coding or reasoning requests to DeepSeek V4 Pro. If screenshots, charts, interface renders, or document images contain information the agent needs, test the DeepSeek V4 Flash Vision Exp API directly through GPT Proto.
Do not promote the experimental route to production based only on four vendor-reported benchmarks. Test it against your own small text, dense dashboards, visual bugs, and multi-step tool workflows first.