DeepSeek Flash vs GLM 5.3 Flash: Quick Verdict
| Workload |
Better choice |
Why |
| Interactive coding assistant |
DeepSeek Flash |
Lower latency and almost twice the measured output speed |
| Terminal and command-line agents |
GLM 5.3 Flash |
Small lead on independent Terminal-Bench 4.0 |
| Workflow automation |
DeepSeek Flash |
Higher independent AutomationBench-AA score |
| Lowest standard API price |
GLM 5.3 Flash |
Lower new-input and output prices |
| Cache-heavy off-peak agents |
DeepSeek Flash |
Cached input falls to $0.003 per million tokens |
| Screenshot-to-code |
Test both |
Both accept images; no decisive independent visual-coding comparison yet |
| Very long generated output |
DeepSeek Flash |
Up to 384K output, compared with 128K for GLM |
| Local deployment |
GLM 5.3 Flash |
Smaller total model, although still demanding to host |
My default recommendation is straightforward: start with DeepSeek Flash for a responsive coding assistant. Start with GLM 5.3 Flash for batch processing and cost-sensitive terminal work. If the application already supports model routing, keep both.
Which Models Are We Actually Comparing?
The naming is unusually easy to get wrong.
DeepSeek Flash Now Means DeepSeek V4.1 Flash
deepseek-flash is the current API model string. DeepSeek V4.1 Flash is the model version served behind it.
The older names deepseek-v4-flash and deepseek-v4-flash-vision-exp refer to retired models. DeepSeek still accepts those aliases, but requests are now handled by V4.1 Flash and billed at the current Flash rate.
This matters when reading older comparisons. A page published before September 10, 2026 may describe the original 284B-parameter, text-oriented V4 Flash. The current model has a 552B backbone, native image input and a different architecture.
For new GPT Proto integrations, use the current deepseek-flash API page and record the resolved model version in your evaluation logs.
GLM 5.3 Flash Is Not a Faster Setting for GLM 5.3
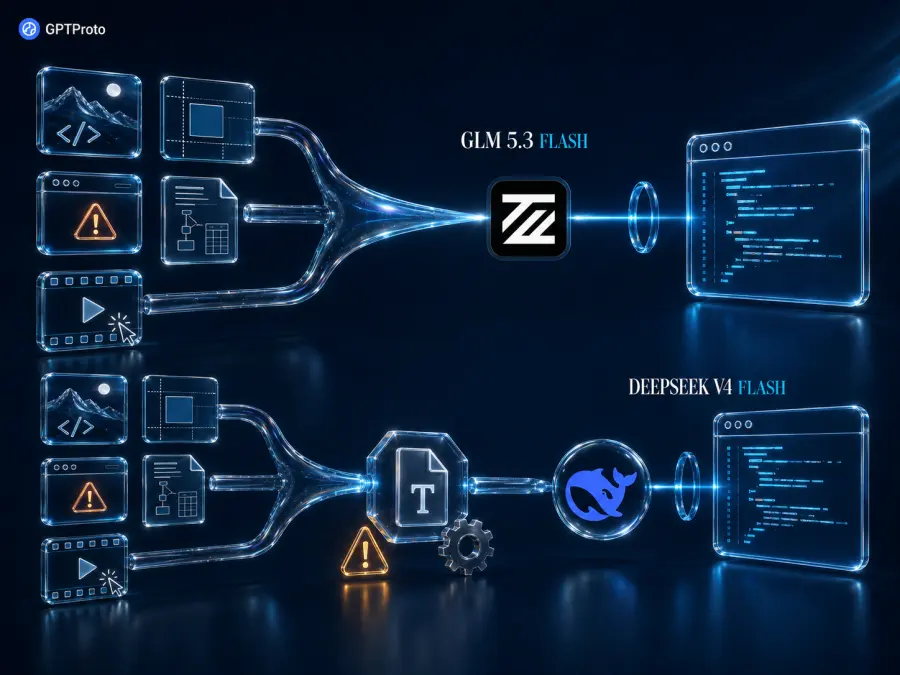
GLM 5.3 and GLM 5.3 Flash are separate models.
Standard GLM 5.3 is a text-focused model built from the GLM-5.2 line. GLM 5.3 Flash starts from a newly trained multimodal base. It combines sparse and linear attention, contains 320B total parameters and activates approximately 18B per token.
It can receive text, images, videos and files. Standard GLM 5.3 remains text-only.
This distinction is important for frontend development. The GLM 5.3 Flash API can inspect a screenshot or interface recording; the similarly named GLM 5.3 endpoint cannot.
DeepSeek V4.1 Flash vs GLM 5.3 Flash at a Glance
| Specification |
DeepSeek V4.1 Flash |
GLM 5.3 Flash |
| API model string |
deepseek-flash |
glm-5.3-flash |
| Developer |
DeepSeek |
Z.ai |
| Release |
September 2026 |
August 2026 |
| Input |
Text and images |
Text, images, videos and files |
| Output |
Text and tool calls |
Text and tool calls |
| Context window |
1M tokens |
1M tokens |
| Maximum output |
384K tokens |
128K tokens |
| Total parameters |
552B |
320B |
| Active parameters |
8B during prefill; 16B during decode |
Approximately 18B |
| Reasoning |
Thinking or non-thinking |
Reasoning always enabled |
| Tool calling |
Yes |
Yes |
| Open weights |
MIT License |
MIT License |
| Local deployment |
Supported, with substantial hardware |
Supported, with substantial hardware |
Model size alone does not predict API speed. GLM has fewer total parameters, but current hosted measurements show DeepSeek generating output faster.
The context figures also need perspective. A one-million-token limit is a ceiling, not an instruction to send an entire repository on every call. Irrelevant source files increase latency, token cost and the chance that the model focuses on the wrong dependency.
Independent Performance Comparison
The cleanest public comparison comes from Artificial Analysis because both models are measured within the same evaluation framework.
| Independent metric |
DeepSeek V4.1 Flash |
GLM 5.3 Flash |
| Intelligence Index |
40 |
42 |
| AutomationBench-AA |
69% |
60% |
| Terminal-Bench 4.0 |
27% |
33% |
| SciCode |
52% |
52% |
| Humanity’s Last Exam |
39% |
40% |
| Long-context retrieval |
84% |
80% |
| Average cost per task |
$0.27 |
$0.25 |
| Output tokens per task |
89K |
69K |
Source: Artificial Analysis head-to-head comparison.
GLM’s two-point Intelligence Index lead is real, but it is not a clean sweep. GLM performs better in the terminal evaluation, while DeepSeek leads by nine percentage points on AutomationBench-AA and by four points in the long-context retrieval test. SciCode is tied.
The token-use figures are equally important. DeepSeek generated approximately 89,000 output tokens per evaluated task, compared with 69,000 for GLM. DeepSeek may return tokens faster, but it can also return more of them.
In plain terms: GLM is slightly more efficient across the complete benchmark set. DeepSeek is faster and wins some of the workloads that matter most to automated systems.
What the Vendor Benchmarks Add
DeepSeek and Z.ai also publish coding and agent results. These provide useful supporting evidence, but they should not be presented as a controlled head-to-head test.
DeepSeek reports 74.2 on DeepSWE v1.1 and 90.6 on Terminal-Bench 2.1 for V4.1 Flash. Z.ai reports 63.4 and 84.3 respectively for GLM 5.3 Flash.
The tempting conclusion is that DeepSeek wins both. I would not make that claim.
The companies used their own model settings, context strategies, agent configurations and evaluation infrastructure. Even when the benchmark name is identical, the surrounding setup may not be. Vendor scores show what each team was able to achieve with its own model. The independent table above is the fairer comparison.
DeepSeek Flash vs GLM 5.3 Flash for Coding
Both models can write functions, explain unfamiliar code, generate tests, refactor modules and diagnose errors. The difference becomes clearer when coding turns into a longer sequence of actions.
Repository-Level Coding and Debugging
GLM’s independent Terminal-Bench lead makes it the better first candidate for tasks involving shell commands, dependency installation, test execution and repeated repository changes.
DeepSeek has two different advantages.
First, it responds faster. That matters when a developer is waiting for an explanation, approving each patch or repeatedly adjusting the same implementation.
Second, DeepSeek supports a 384K maximum output and optional non-thinking operation. Most coding requests should never approach that output limit, but the additional headroom can help with large migration plans, code audits and generated artifacts.
My practical split is:
Use GLM 5.3 Flash for autonomous terminal work and lower-cost batch reviews.
Use DeepSeek Flash for interactive debugging, rapid code iteration and latency-sensitive editor workflows.
Keep the existing model when it already passes your regression tests. A two-point benchmark difference is not worth an untested production migration.
Frontend Coding and Screenshot-to-Code
Both models are now multimodal. That invalidates one of the main conclusions in older DeepSeek V4 Flash comparisons.
DeepSeek Flash can inspect screenshots, diagrams and charts. GLM 5.3 Flash accepts images, videos and files, giving it a broader input surface for interface workflows.
A frontend agent could use either model to:
Reconstruct a page from a screenshot
Compare a rendered interface with a design reference
Diagnose spacing and alignment problems
Read browser error screenshots
Review several interface states
Combine source code with visual evidence
Community discussions sometimes describe GLM as better at design-oriented tasks and DeepSeek as more responsive. Treat that as a testing lead, not a settled fact. The same discussions include developers reporting the opposite result, and provider latency varies considerably. One OpenCode discussion captures that disagreement clearly.
There is not yet enough controlled evidence to declare a visual-coding winner. A better evaluation uses the same three tasks on both models:
Recreate one responsive component from a screenshot.
Repair a page with a visible mobile-layout failure.
Compare the new render with the reference and list the remaining differences.
Judge the rendered result, not the confidence of the answer.
Which Model Is Better for AI Agents?
The word “agent” covers several different systems. A chat assistant that calls one search tool has little in common with a coding process that edits files, runs tests and retries for 30 minutes.
Tool Calling and Workflow Automation
Both models support tool calls, structured output and streaming. Both can receive long conversation histories and continue after tool results are returned.
DeepSeek’s 69% AutomationBench-AA result gives it the stronger independent signal for general workflow automation. It also offers thinking and non-thinking modes, so routine tool selection does not always need the same reasoning budget as a difficult planning task.
GLM performs better on Terminal-Bench 4.0 and has lower standard output pricing. That combination is attractive for background systems that execute many commands or produce substantial output.
The agent framework still controls the workflow. The model proposes a tool call; your application validates the arguments, runs the tool, returns the result and decides whether another step is allowed. Switching to a better model does not replace permissions, timeouts, retries or sandboxing.
Interactive Agents vs Background Agents
For an agent that works alongside a person, latency is part of quality. Waiting nearly 20 seconds for the first answer token feels different from waiting about 11 seconds, even when the final outputs receive similar scores.
DeepSeek is the better fit for:
Interactive coding assistants
Chat-based debugging
Human-approved tool calls
Agents that expose progress while working
Applications where users abandon slow requests
GLM is the better fit for:
Background repository reviews
Batch code analysis
Cost-sensitive terminal tasks
Document and file workflows
Systems where completion cost matters more than immediate feedback
For long-running agents, test both. Error recovery can erase a nominal price advantage. A model that is 20% cheaper per token but needs more retries may cost more per completed task.
Speed and Latency
The current independent measurements show the clearest difference in this comparison.
| Performance metric |
DeepSeek V4.1 Flash |
GLM 5.3 Flash |
| Output speed |
214 tokens/s |
114 tokens/s |
| Time to first token |
1.37s |
2.45s |
| Time to first answer token |
10.70s |
19.96s |
| End-to-end response time |
13.03s |
24.34s |
| Average time per evaluated task |
320.60s |
529.28s |
In this snapshot, DeepSeek completed the measured response in roughly half the time.
Do not treat these numbers as permanent provider guarantees. Prompt length, reasoning effort, current server load, streaming behavior and output length can all change perceived latency.
The direction is still consistent across the measurements: DeepSeek Flash is the faster interactive model.
DeepSeek Flash vs GLM 5.3 Flash Pricing
GPT Proto currently provides GLM 5.3 Flash at 10% below its standard list input and output rates. DeepSeek Flash uses its standard variable pricing, with a 50% off-peak rate.
| Price per 1M tokens |
GLM 5.3 Flash |
DeepSeek off-peak |
DeepSeek peak |
| New input |
$0.135 |
$0.15 |
$0.30 |
| Cached input |
$0.03 |
$0.003 |
$0.006 |
| Output |
$0.45 |
$0.60 |
$1.20 |
Prices can change. Check the live GLM 5.3 Flash and DeepSeek Flash model pages before placing fixed rates in your product.
Example 1: Short Coding Request
Assume one request uses 10,000 new input tokens and produces 3,000 output tokens.
| Model |
Estimated cost |
| GLM 5.3 Flash |
$0.00270 |
| DeepSeek off-peak |
$0.00330 |
| DeepSeek peak |
$0.00660 |
GLM is less expensive for this ordinary, uncached request.
Example 2: Repository-Scale Request
Assume 200,000 new input tokens and 20,000 output tokens.
| Model |
Estimated cost |
| GLM 5.3 Flash |
$0.036 |
| DeepSeek off-peak |
$0.042 |
| DeepSeek peak |
$0.084 |
GLM keeps its price advantage when most of the repository context is new.
Example 3: Cache-Heavy Agent Workload
Now assume a monthly workload uses:
100M input tokens
An 80% cache-hit rate
10M output tokens
| Model |
Estimated cost |
| DeepSeek off-peak |
$9.24 |
| GLM 5.3 Flash |
$9.60 |
| DeepSeek peak |
$18.48 |
This is the exception hidden by the headline prices.
GLM has cheaper normal input and output. DeepSeek’s off-peak cached input is ten times cheaper, allowing it to edge below GLM when an agent repeatedly reuses the same system prompt, repository context and tool definitions.
An 80% cache-hit rate is not automatic. Measure it in production before using this example as a budget forecast.
Which Model Is More Cost-Effective?
For ordinary API calls, GLM 5.3 Flash is more cost-effective. Its GPT Proto input and output rates are lower, and the independent evaluation reports a slightly lower average task cost: $0.25 versus $0.27.
For cache-heavy workloads running off-peak, DeepSeek can cost less.
For user-facing products, speed complicates the calculation. A faster response can improve completion rates and reduce abandoned requests. That value does not appear in a token-price table.
The honest decision rule is:
Choose GLM when most input is new and output cost dominates.
Choose DeepSeek off-peak when most context is reused.
Choose DeepSeek when response time is part of the product experience.
Compare cost per accepted result when failures and retries are common.
Using Both Models Through One GPT Proto API Key
You do not need two separate provider integrations to evaluate these models.
GPT Proto provides OpenAI-compatible access to both. The API key, base URL and request structure can remain the same; change the model string to route a request.
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["GPTPROTO_API_KEY"],
    base_url="https://gptproto.com/v1",
)

# Use "glm-5.3-flash" for lower standard token prices.

# Switch to "deepseek-flash" for lower latency.
MODEL = "deepseek-flash"

response = client.chat.completions.create(
    model=MODEL,
    messages=[
        {
            "role": "system",
            "content": (
                "You are a coding assistant. Inspect the problem, "
                "propose the smallest safe change, and explain how to test it."
            ),
        },
        {
            "role": "user",
            "content": (
                "This Python function occasionally returns duplicate IDs. "
                "Find the likely race condition and propose a fix."
            ),
        },
    ],
)

print(response.choices[0].message.content)
A single key does not create a multi-agent system by itself. Your application, coding tool or agent framework still decides which worker receives a task, which model it uses and how results are combined.
What the shared API removes is integration duplication. You can route terminal tasks to GLM, interactive requests to DeepSeek and maintain a fallback without managing separate provider credentials and balances.
Explore both models in the GPT Proto model catalog.
Final Verdict
DeepSeek Flash is the better choice for interactive coding and latency-sensitive agents. It produces tokens much faster, reaches the first answer sooner, supports long output and performs well on workflow automation and long-context retrieval.
GLM 5.3 Flash is the better choice for lower standard token costs, terminal-oriented agents and batch workloads. Its overall independent score is slightly higher, and it uses fewer output tokens per evaluated task.
For frontend coding, there is no proven winner. Both accept screenshots. GLM accepts additional video and file inputs, while DeepSeek responds faster. Run the same visual regression task on both before deciding.
For agent costs, do not stop at the rate card. GLM is cheaper for ordinary tokens. DeepSeek can become cheaper when repeated context produces a high cache-hit rate during off-peak hours.
If I were building a new coding product, I would not choose only one. I would use DeepSeek Flash as the interactive default, GLM 5.3 Flash for selected batch and terminal tasks, and keep routing decisions behind the same API interface.