Best Affordable LLM APIs for Agents at a Glance
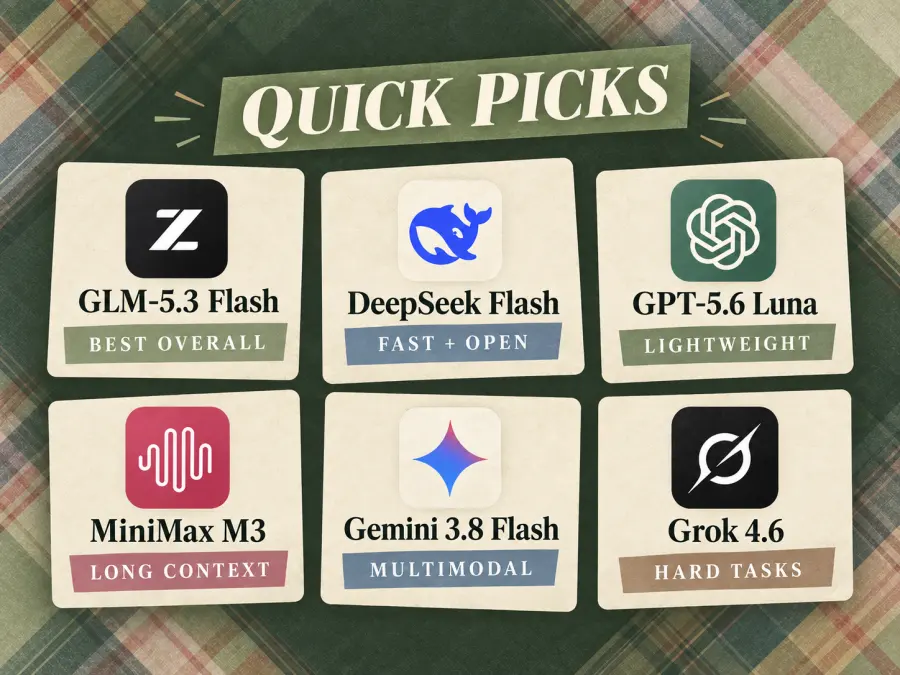
| Rank |
Model |
GPT Proto model string |
GPT Proto input/output price per 1M tokens |
Context |
Best for |
| 1 |
GLM-5.3 Flash |
glm-5.3-flash |
$0.15 / $0.50 |
Up to 1M |
Best overall affordable agent API |
| 2 |
DeepSeek Flash |
deepseek-flash |
$0.30 / $1.20 |
Up to 1M |
Fast, open-weight, input-heavy agents |
| 3 |
GPT-5.6 Luna |
gpt-5.6-luna |
Confirm live GPT Proto rate before publication |
About 1M |
Lightweight, high-volume agent calls |
| 4 |
MiniMax M3 |
MiniMax-M3 |
$0.48 / $0.96 |
About 1M |
Long-context document agents |
| 5 |
Gemini 3.8 Flash |
gemini-3.8-flash |
$0.90 / $4.50 |
About 1M |
Fast multimodal agents |
| 6 |
Grok 4.6 |
grok-4.6 |
$1.20 / $3.60 |
500K |
Difficult multi-step escalation |
Prices were checked on September 15, 2026. API rates and promotional discounts can change, so confirm the live model page before estimating a production budget.
Compare before you commit: Browse GPT Proto's available AI models and keep shortlisted model IDs behind configuration so you can switch without rebuilding the entire agent.
How We Ranked These Affordable LLMs for Agentic AI
Simon Willison offers a useful working definition: an LLM agent runs tools in a loop to achieve a goal. That loop changes how affordability should be measured. A normal chatbot comparison can focus on the cost of one response; an agent comparison must also count tool calls, tool results, retries, reasoning tokens, and unsuccessful runs.
We used the following order of evaluation.
1. The model must pass an agent capability gate
A model was not included merely because it had a low token price. Each shortlisted option needed a documented route for function calling or tool use, plus a usable way to return structured data or continue a multi-turn workflow.
2. Public agent evidence matters more than a general knowledge score
The Berkeley Function Calling Leaderboard is especially useful for understanding what a tool-use evaluation should inspect: correct function selection, valid arguments, multi-turn behavior, and cases where the model should avoid calling a tool. Its public leaderboard was last updated on April 12, 2026, however, which predates most models in this article. We therefore use its methodology rather than assigning its older scores to newer releases.
We also reference Artificial Analysis. Its Intelligence Index includes agentic knowledge work, real-world work, SaaS automation, terminal use, and long-context evaluations. It remains a mixed index—not a pure function-calling score—and should be treated as screening evidence rather than a guarantee for a particular agent.
3. Cost per successful task matters more than price per token
The useful production metric is:
Cost per successful task = Total API cost of all attempts and retries / Accepted task completions
This calculation should include uncached input, cached input, output, hidden or billed reasoning tokens where applicable, failed attempts, and recovery calls. If one model finishes 90 out of 100 tasks and another finishes 60, comparing only their headline token rates hides the cost of repairing the other 40 tasks.
4. Speed, verbosity, and integration friction affect cost
Output tokens per second measure only the generation phase. They do not capture time to first answer, internal reasoning, tool execution, rate-limit delays, or repeated calls. A verbose model may also turn a low output price into a larger final bill.
Finally, similar APIs still have model-specific rules. Reasoning fields, unsupported sampling parameters, function-response IDs, and model-name capitalization can all break an otherwise portable workflow. This is why the exact GPT Proto model string is included for every entry.
1. GLM-5.3 Flash — Best Overall Affordable LLM API for Agents
GLM-5.3 Flash currently offers the strongest balance of low token rates and documented agent features in this list. On GPT Proto, the model is listed at $0.15 per million input tokens, $0.03 per million cached-input tokens, and $0.50 per million output tokens.
The model accepts text, images, video, and files and can return text or tool calls. It supports function calling, structured JSON, context caching, response streaming, and streamed tool arguments. Its large context window is useful when an agent must retain documents, prior tool results, screenshots, or a long working history.
Independent screening is encouraging. Artificial Analysis reports an Intelligence Index score of 42 and an output speed of about 107 tokens per second. The model generated more output tokens than the comparison median during that evaluation, so teams should still set output and step limits.
The main trade-off is that reasoning is always enabled. That can help on ambiguous tool decisions but is unnecessary overhead for basic classification or extraction. “Flash” should not be interpreted as proof that every request will have the lowest end-to-end latency.
Choose GLM-5.3 Flash when:
an agent needs inexpensive function calling at meaningful volume;
a workflow combines text with screenshots, video, charts, or files;
structured output and streamed tool arguments matter;
open weights and hosted access are both useful options.
Avoid using it as the only model when: the workflow includes many trivial requests where always-on reasoning adds cost without improving acceptance rates.
For most teams, glm-5.3-flash is the most sensible first model to evaluate.
2. DeepSeek Flash — Best Fast Open-Weight Model for Tool-Driven Agents
The GPT Proto model string deepseek-flash currently routes to DeepSeek V4.1 Flash. The route supports text and image input, tool calls, JSON output, streaming, thinking and non-thinking operation, and a context window of up to one million tokens.
Its GPT Proto rate is $0.30 per million input tokens, $0.006 per million cache-read tokens, and $1.20 per million output tokens. That extremely low cache-read rate is relevant for agents that repeatedly reuse stable instructions, tool descriptions, or reference material.
Artificial Analysis measured an Intelligence Index score of 40 and about 222 output tokens per second. It was substantially faster than GLM-5.3 Flash in that measurement, although it was also highly verbose across the evaluation set. A fast model can still produce a large bill if it generates more tokens than the task needs.
DeepSeek Flash is particularly attractive for input-heavy agents. Its one-million-token context, long output ceiling, image understanding, and switchable reasoning modes make it suitable for document analysis, screenshot-assisted workflows, repository inspection, and multi-step automation.
There is one important compatibility detail. In DeepSeek's native thinking-mode tool workflow, prior reasoning_content may need to be preserved when subsequent messages are sent. Confirm how the GPT Proto route maps that field before moving a stateful tool loop into production.
Choose DeepSeek Flash when:
cached prompts make up a large part of your agent traffic;
you need high generation speed and open weights;
the same agent switches between routine non-thinking work and harder reasoning;
long input or image evidence must remain in the working context.
Watch for: excessive output, missing reasoning state in multi-turn requests, and tool arguments that pass JSON parsing but fail your business validation.
3. GPT-5.6 Luna — Best for Lightweight, High-Volume Agents
GPT-5.6 Luna is the cost-sensitive member of the GPT-5.6 family. It is intended for frequent tasks such as classification, extraction, summarization, routing, and user-facing chat. Those jobs often appear at the beginning of an agent workflow, before a more expensive model is needed.
The model accepts text, images, and documents, supports an approximately one-million-token context, and works with OpenAI-style prompts, JSON schemas, and tool definitions. Artificial Analysis reports an Intelligence Index score of 38 and an output speed of about 116 tokens per second. Its current official reference price is $0.20 per million input tokens and $1.20 per million output tokens.
Luna should not automatically control every part of a complex agent. Its best role is often the inexpensive first layer:
classify the request;
extract or normalize required fields;
attempt a simple tool call;
validate the result;
escalate only if the request fails or exceeds a complexity threshold.
This design prevents a stronger model from handling thousands of straightforward requests while still protecting difficult workflows from repeated low-quality attempts.
Choose GPT-5.6 Luna when: volume, predictable structured work, and compatibility with an existing OpenAI-style agent are more important than maximum long-horizon performance.
Escalate instead of retrying indefinitely when: the model cannot recover from a failed tool result, loses key details deep in the context, or repeatedly violates a strict output schema.
4. MiniMax M3 — Best Affordable API for Long-Context Document Agents
MiniMax M3 is designed for sustained coding and agent work across an approximately one-million-token context. On GPT Proto, use the exact case-sensitive model string MiniMax-M3. The listed price is $0.48 per million input tokens and $0.96 per million output tokens.
The model supports tool use and multi-step task decomposition. Its context capacity makes it a practical candidate for research agents, contract review, policy comparison, large support histories, and workflows that must retain results from many documents.
Artificial Analysis gives MiniMax M3 an Intelligence Index score of 30, about 107 output tokens per second, and a lower output-token total than several other models in this list. That relative concision can matter in agent loops, because every extra model turn becomes context for the next request.
The trade-off is capability. MiniMax M3's independent composite score is below the other primary candidates, so its long context should not be confused with uniformly stronger reasoning. More context only helps when the right evidence is retrieved, instructions remain clear, and the model can use the information correctly.
Choose MiniMax M3 when:
the agent needs to retain a large document collection or a long work history;
output cost and response concision matter;
the workflow can validate intermediate results;
you want an open-weight model but prefer hosted API access.
Test carefully when: successful completion depends on subtle cross-document reasoning rather than locating and transforming information.
5. Gemini 3.8 Flash — Best Fast Multimodal Agent API
Gemini 3.8 Flash is the strongest candidate here when one agent must process text, images, audio, video, and PDFs. It supports function calling, structured output, caching, and adjustable thinking levels. On GPT Proto, the model string is gemini-3.8-flash, with listed rates of $0.90 per million input tokens, $0.09 per million cached-input tokens, and $4.50 per million output tokens.
Its standout feature is speed. Artificial Analysis measured approximately 303 output tokens per second with an Intelligence Index score of 41. It was the fastest model in its comparison class at the time of measurement.
That does not make it the cheapest option. Artificial Analysis also found the model verbose, while its GPT Proto output rate is considerably higher than GLM-5.3 Flash, DeepSeek Flash, and MiniMax M3. A long multimodal agent that reasons, calls tools, and verifies its own work may consume substantially more output than a short chat request.
Gemini 3.8 Flash is best when its capabilities replace extra preprocessing steps. For example, a support agent that can inspect a video, read a PDF, and call a customer system in one workflow may be simpler than a pipeline that needs separate transcription, vision, and language models.
Choose Gemini 3.8 Flash when:
audio, video, screenshots, charts, or PDFs are central to the task;
user-facing responsiveness matters;
adjustable reasoning helps balance routine and difficult requests;
a single multimodal request can replace several preprocessing calls.
Watch for: high output-token use and the difference between fast generation and total workflow latency.
6. Grok 4.6 — Best Affordable Escalation Model for Difficult Tasks
Grok 4.6 is not the cheapest default model in this ranking. It is included because a model can still be cost-effective when it prevents expensive failures on difficult work.
The GPT Proto route grok-4.6 supports text and image input, function calling, structured output, four reasoning levels, and a 500,000-token context window. Standard GPT Proto rates are listed at $1.20 per million input tokens, $0.30 per million cached-input tokens, and $3.60 per million output tokens.
Artificial Analysis reports an Intelligence Index score of 44—the highest in this shortlist—but a generation speed of about 59 tokens per second. Its output was less verbose than several lower-cost alternatives, yet both latency and token price make it unsuitable for every routine request.
The practical role is escalation. A lower-cost model can attempt the task first, and the agent can route to Grok 4.6 when validation fails, the plan requires many dependent steps, or the cost of an incomplete result exceeds the additional API expense.
Choose Grok 4.6 when:
the agent must persist across a difficult multi-step workflow;
visual evidence and reasoning need to be combined;
a failed result would create more cost than a higher-priced request;
the application can select lower reasoning effort for simpler steps.
Do not use it by default for: basic extraction, rewriting, routing, or other high-volume work already handled reliably by a cheaper model.
Why the Absolute Cheapest LLM Is Not Ranked First
GPT Proto lists models with token prices below every main entry in this guide. For example, Doubao Seed 1.6 Flash has a much lower headline input rate. That makes it interesting for narrow workloads, but it does not establish that it is the cheapest LLM API for an agent.
Before a model enters an agent ranking, it should demonstrate four things:
it can select the correct tool from realistic alternatives;
its arguments consistently satisfy the required schema and business rules;
it can continue after receiving a tool result or error;
it avoids unnecessary tool calls when no available function fits.
A pricing table cannot answer those questions. Neither can a general reasoning score. An ultra-cheap model may be excellent for classification, tagging, or rewriting while remaining a poor controller for a workflow that can modify a database or send an external message.
The safer decision rule is simple: establish an acceptance-rate threshold first, then compare cost among the models that pass it.
A Practical Low-Cost Model Routing Strategy
Many production agents should use more than one model. This does not necessarily mean several autonomous agents. It can be a simple routing rule inside one application.
| Agent task |
Start with |
Escalate when |
| Classification, extraction, and request routing |
GPT-5.6 Luna |
The output fails schema validation or the request is ambiguous |
| General tool-driven workflow |
GLM-5.3 Flash |
Several dependent decisions or recovery steps are required |
| Fast, cached, input-heavy work |
DeepSeek Flash |
The model loses state or cannot verify the result |
| Large document or knowledge session |
MiniMax M3 |
Subtle cross-document reasoning fails acceptance checks |
| Audio, video, PDF, or visual workflow |
Gemini 3.8 Flash |
The task becomes a difficult long-horizon plan |
| Difficult multi-step work |
Grok 4.6 |
Human approval is required for the next action |
A cost-controlled agent loop can follow five rules:
Start with the least expensive model that has passed your task evaluation.
Validate every structured answer and tool argument before execution.
Limit the maximum number of model steps, output tokens, elapsed time, and total cost.
Escalate after a defined failure instead of repeating the same model indefinitely.
Require human confirmation for irreversible, financial, permission-changing, or externally visible actions.
Because the shortlisted models are available through one GPT Proto model catalog, an application can keep one account and API credential while selecting a different model string for each request. The orchestration logic still belongs to the application or agent framework; the API key alone does not create or coordinate multiple agents.
Minimal Tool-Calling Request with GPT Proto
The example below gives GLM-5.3 Flash one function definition. The model can propose a call, but your application—not the model—must execute the function, validate permissions, and return the result to the conversation.
curl https://gptproto.com/v1/chat/completions \
  -H "Authorization: Bearer $GPTPROTO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "glm-5.3-flash",
    "messages": [
      {
        "role": "user",
        "content": "Where is order A-1042?"
      }
    ],
    "tools": [
      {
        "type": "function",
        "function": {
          "name": "get_order_status",
          "description": "Return the current status of one order.",
          "parameters": {
            "type": "object",
            "properties": {
              "order_id": {
                "type": "string",
                "description": "The order identifier."
              }
            },
            "required": ["order_id"],
            "additionalProperties": false
          }
        }
      }
    ],
    "tool_choice": "auto"
  }'
If the response contains a tool_call, the application should:
confirm that the requested function is allowed;
validate order_id against the JSON schema and business rules;
execute get_order_status in the application;
send the tool result back with the correct call identifier;
let the model produce the final user-facing answer.
Changing the model value lets you send the same evaluation request to another compatible route. Do not switch production traffic solely because the request succeeds once; repeated runs are needed to expose inconsistent tool choices and arguments.
How to Test an Affordable LLM API for Your Agent
A small evaluation is more useful than a large generic benchmark if it reflects your actual tools. Start with four categories:
Single-tool selection: Give the model several similar tools and check whether it chooses the correct one.
Parallel calls: Ask for information that requires two independent tool calls and verify that neither is omitted.
No-tool relevance: Include requests that cannot or should not use any available function.
Recovery: Return a realistic tool error and check whether the model fixes the request without entering an uncontrolled loop.
Run each case at least five times per model with the same prompt, tools, context, reasoning setting, output limit, and acceptance criteria. Record:
accepted-task rate;
correct tool-selection rate;
schema-valid argument rate;
unnecessary calls;
recovery success;
total model steps;
input, cached-input, reasoning, and output tokens;
time to first answer and total workflow time;
total cost, including failures and retries.
With six models, four tasks, and five repeats, the minimum comparison contains 120 runs. Ten repeats are preferable when the decision affects meaningful production traffic.
What Agent Builders Say About Latency
Community reports add context that pricing pages cannot provide. In one AI Agents community discussion, a simple retrieval system reportedly answered in under one second, while a more agentic version took almost three seconds. For customer support, that difference was described as a dealbreaker.
Other participants disagreed with the universal conclusion. They noted that research and internal analytics users may accept much longer waits when tool use materially improves the answer. The useful lesson is not that three seconds is always too slow. It is that the same model can be affordable for one agent and unsuitable for another because latency, quality, and failure costs have different values.
Treat community comments as experience reports, not benchmark results. Use them to identify failure cases for your own evaluation.
Final Recommendation
For most cost-sensitive tool-driven agents, start by evaluating GLM-5.3 Flash. It combines the lowest confirmed output rate in the primary shortlist with function calling, structured output, multimodal inputs, caching, and a large context window.
Choose DeepSeek Flash when speed, open weights, switchable reasoning, or very cheap cache reads matter. Use GPT-5.6 Luna for lightweight high-volume steps after confirming the live GPT Proto price. Select MiniMax M3 for long document sessions, Gemini 3.8 Flash for fast multimodal workflows, and Grok 4.6 as an escalation model when harder tasks justify its higher price.
The best affordable LLM for an agent is the least expensive model that reliably completes your task—not the model with the smallest number in a pricing table.
Build a shortlist with one API: Explore LLM models on GPT Proto, test the same tool schema across candidates, and route each task to the lowest-cost model that meets its acceptance threshold.