TL;DR: Nano Banana 2.1 vs Nano Banana Pro
Choose Nano Banana 2.1 by default for product images, background replacement, packaging concepts, posters, multilingual ads, and high-volume generation.
Choose Nano Banana Pro selectively when you need its five-character reference allocation, three dedicated style-reference slots, or it produces a higher acceptance rate on your specific assets.
Google’s own evaluations put 2.1 ahead of Pro across overall image preference, infographic design, general editing, product consistency, and multi-reference editing.
Independent blind voting currently gives 2.1 a higher Elo score for both text-to-image generation and image editing.
Our test was exploratory: one output per model for each of five prompts. It shows useful differences, but it is not a statistical benchmark.
You can try Nano Banana 2.1 on GPT Proto or open the Nano Banana Pro model page to compare both with one GPT Proto API key.
Nano Banana 2.1 vs Nano Banana Pro at a Glance
| Comparison |
Nano Banana 2.1 |
Nano Banana Pro |
| Google model ID |
gemini-nano-banana-2.1 |
gemini-3-pro-image |
| Positioning |
Latest high-efficiency generation and conversational editing model |
Professional image model for complex design and editing |
| Output resolution |
1K, 2K, and 4K |
1K, 2K, and 4K |
| Reference allocation |
Up to 4 characters and 10 objects |
Up to 5 characters, 6 objects, and 3 style references |
| Aspect ratios |
14 ratios, including 1:4, 4:1, 1:8, and 8:1 |
10 standard ratios, including 1:1, 4:5, 16:9, and 21:9 |
| Search grounding |
Google Web and Image Search |
Google Search |
| Thinking control |
Minimal, medium, and high |
Thinking supported |
| Official 1K price |
$0.0336 per image |
$0.134 per image |
| GPT Proto starting price |
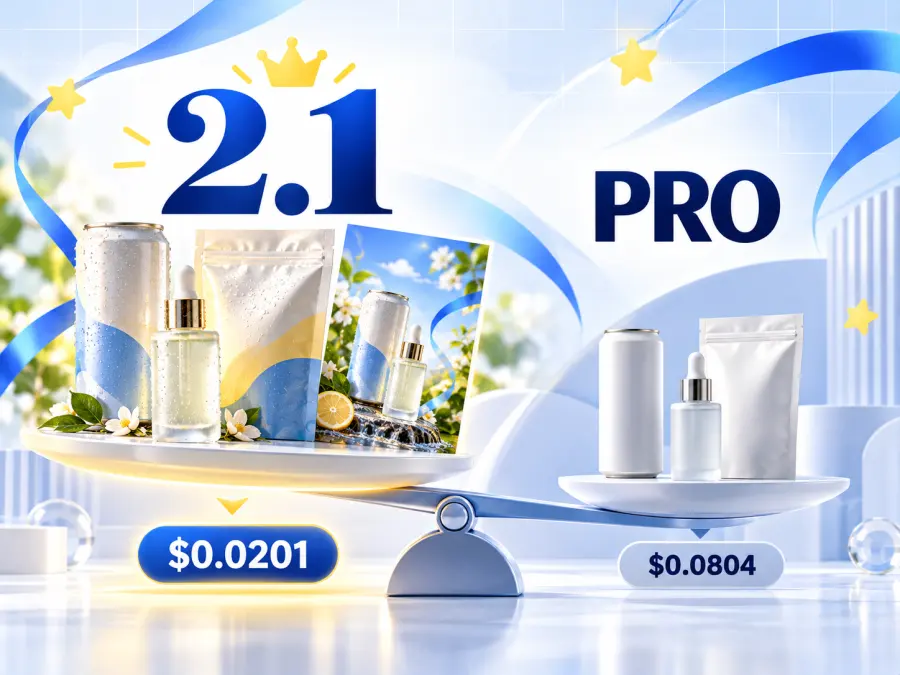
$0.0201 per image |
$0.0804 per image |
| Best starting use |
Ecommerce, editing, posters, multi-SKU work, batch generation |
Character-heavy or style-reference workflows |
The reference-image totals require context. Saying that both models accept “up to 14 images” hides a practical difference. According to Google’s image-generation documentation, 2.1 can allocate ten references to objects but only four to characters. Pro supports five character references and three dedicated style references, but only six object references. An ecommerce catalog may benefit more from 2.1; a campaign with five recurring people may still fit Pro better.
Want the lower-cost starting point? Open the Nano Banana 2.1 API and use Try this model to run a prompt before integrating the API.
What Changed in Nano Banana 2.1?
Nano Banana 2.1 is an update to Nano Banana 2, not a renamed version of Nano Banana Pro. Google describes it as the efficient counterpart to Pro and reports improvements in realism, prompt adherence, multi-turn character consistency, and text rendering. It keeps 1K, 2K, and 4K output while adding better support for extreme panoramic ratios.
The most relevant upgrades are:
corrected tiling artifacts at 1:4, 4:1, 1:8, and 8:1 in 2K and 4K output;
improved text rendering and infographic layouts;
up to 14 references, divided into four characters and ten objects;
Google Web and Image Search grounding;
minimal, medium, and high thinking levels; and
a 131,072-token input limit at the underlying Google model layer.
These specifications come from the official Nano Banana 2.1 model page. The route exposed by an API platform may support a narrower set of fields, so check the live schema before making video input, PDF input, search grounding, or every reference slot a production requirement.
There are still limits. The Google DeepMind model card warns that small text can become blurry at 1K, character consistency is not perfect, left/right instructions can be confused, and occasional slow responses or timeouts remain possible. Exact labels, prices, legal copy, and product geometry should still pass validation before publication.
Does Nano Banana 2.1 Actually Beat Pro on Quality?
The evidence currently points to 2.1, but it should be read in layers.
Google’s internal evaluation
Google reports the following preference-based results for Nano Banana 2.1 with thinking enabled versus Nano Banana Pro:
| Evaluation |
Nano Banana 2.1 |
Nano Banana Pro |
| Overall text-to-image preference |
1050 ± 14 |
935 ± 8 |
| Infographic design |
1048 ± 17 |
912 ± 12 |
| General editing |
1026 ± 12 |
939 ± 10 |
| Product consistency |
1024 ± 18 |
965 ± 14 |
| Multi-reference editing |
1066 ± 22 |
989 ± 12 |
This is first-party evidence, so it should not be treated as the only verdict. It does, however, challenge the assumption that Pro must deliver better output because it is the more expensive model.
Independent blind voting
The current Artificial Analysis text-to-image leaderboard gives Nano Banana 2.1 an Elo score of 1160 ± 10 across 6,055 samples. Nano Banana Pro scores 1102 ± 8 across 17,591 samples. On the image-editing leaderboard, 2.1 scores 1137 ± 9 and Pro scores 1101 ± 8.
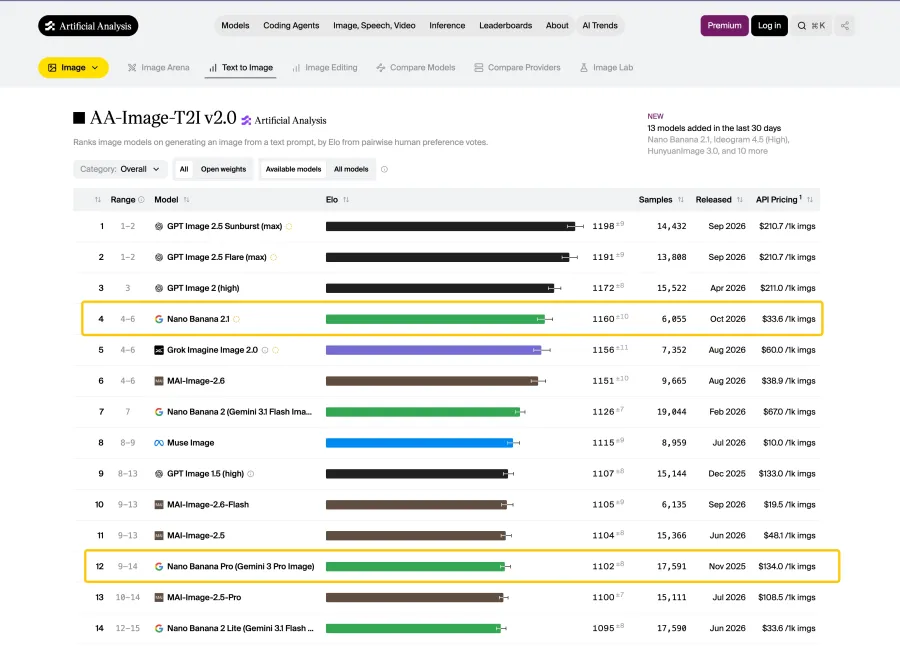
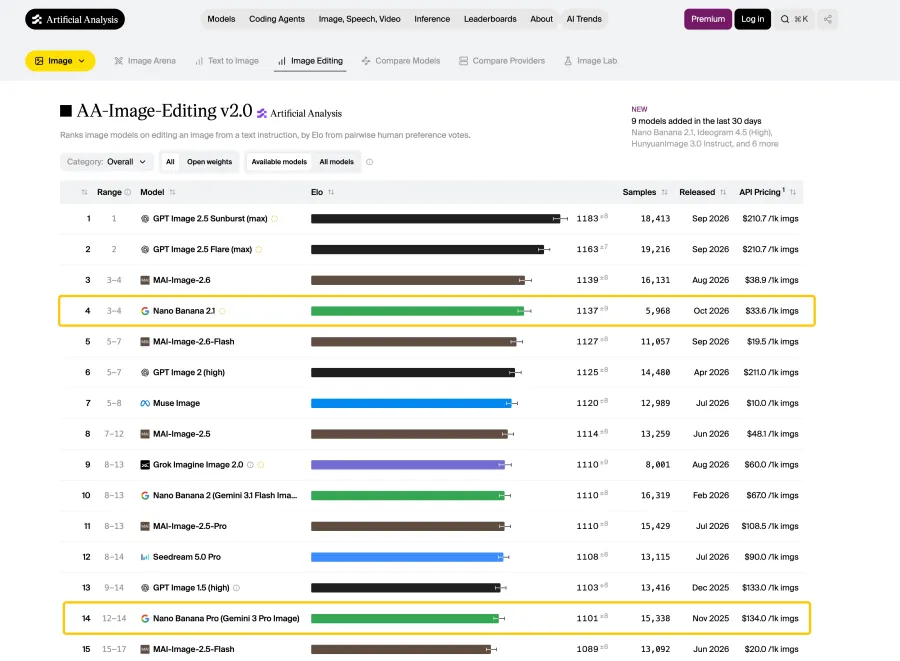
These rankings use blind comparisons in which people choose between outputs made from the same prompt. That makes them more useful than a vendor claim, but they still measure broad human preference—not whether a specific bottle label, SKU color, or product silhouette survived an edit.
Why community opinions remain mixed
Early creator discussions are less consistent. In one GeminiAI discussion about Nano Banana 2.1, several users complained about instruction following or preferred Pro, while a separate r/singularity thread includes both poor-adherence reports and users who found 2.1 better than Nano Banana 2.
Those reports are useful warning signals, not controlled API evidence. Many come from Flow or the Gemini app, where prompt rewriting, defaults, safety handling, and product-level settings may differ from a direct API route. The practical answer is to test both models on the same business assets.
Nano Banana 2.1 vs Nano Banana Pro in the Same Prompt: Five Tests
We ran five single-output comparisons through GPT Proto. Each pair used the same prompt, inputs, and aspect ratio; Test 1 used 3:4 for both models. The left image in each comparison is Nano Banana 2.1, and the right image is Nano Banana Pro.
Because this was one run per model rather than repeated sampling, the results below are observations—not stable win rates. A production evaluation should repeat each task at least three times and keep failed outputs instead of quietly regenerating them.
| Test |
Observed result |
Practical takeaway |
| Product hero |
2.1 lead |
Both followed the brief; 2.1 looked more natural and photographic |
| Exact packaging text |
2.1 lead |
Both rendered the copy correctly; 2.1 integrated it into a stronger package design |
| Background replacement |
Mixed |
2.1 preserved the product better; Pro blended the scene better but changed product shape |
| Four-SKU composition |
Near tie |
Both extracted the products; Pro preserved small text slightly better |
| Multilingual poster |
2.1 lead |
Both handled the copy; 2.1 produced the more marketable layout |
Test 1: Product hero image
The prompt requested one matte-white insulated bottle, a brushed silver cap, a thin cobalt-blue stripe, two water droplets, soft daylight, and no added logo or text.
Both models complied with the main instructions. Pro produced a clean, restrained studio image. The 2.1 result had more natural light falloff, background texture, and a round stone pedestal that made the image feel less synthetic. For a product detail page, both were usable; for a lifestyle-oriented hero image, we preferred 2.1.
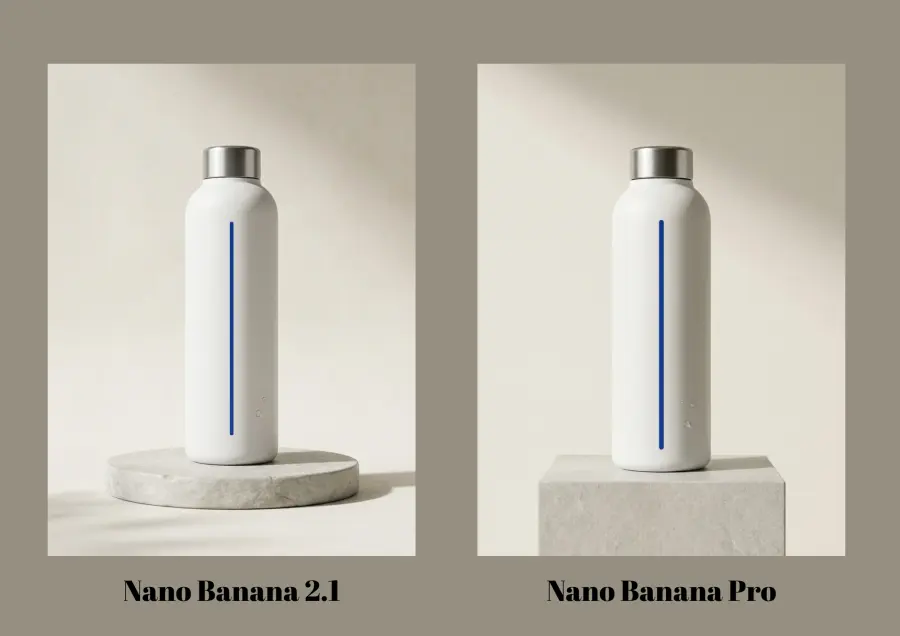
Test 1 result: both models followed the product brief, while Nano Banana 2.1 produced the more natural-looking commercial photo.
Test 2: Exact packaging text
The pouch had to display six exact lines: “NORTHLINE,” “OAT PROTEIN,” “VANILLA,” “20 SERVINGS,” “500 g,” and “$24.00.” Neither model misspelled or omitted the required copy.
The difference was design interpretation. Pro followed the hierarchy literally and placed the copy on a minimal white pouch. Nano Banana 2.1 used botanical decoration, varied spacing, and a more deliberate packaging hierarchy. Its text looked embedded in the package rather than overlaid on a blank mockup. If the goal is strict execution of a minimal layout, Pro’s directness may be useful. If the goal is a marketable concept from a written brief, 2.1 was stronger in this run.
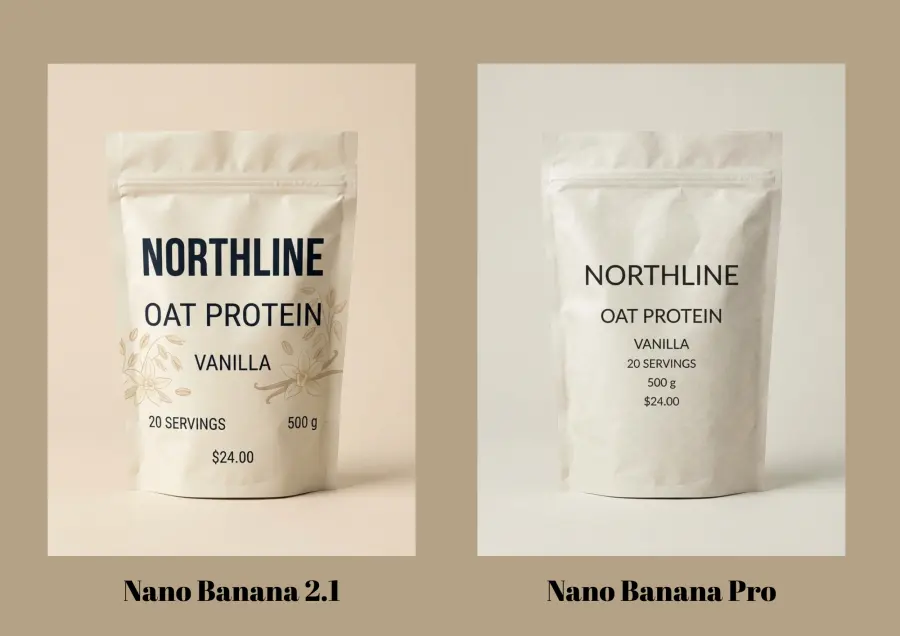
Test 2 result: both models rendered the exact copy, but 2.1 integrated it into the packaging more naturally.
Test 3: Ecommerce background replacement
This edit asked each model to replace only the background of a product photo with a bright kitchen scene while preserving the bottle’s geometry, label, colors, reflections, and surface details.
Nano Banana 2.1 did the better preservation job. The product shape and key details stayed closer to the supplied image. Pro applied warmer color grading and made the object feel more integrated with the kitchen lighting, but it also altered the product shape. For ecommerce, that is a serious tradeoff: a beautiful result is not acceptable if it misrepresents the item being sold.
This test illustrates why product fidelity and visual polish should be scored separately. 2.1 won on asset integrity; Pro had an advantage in scene-wide color treatment.
![https://oss-us.gptproto.com/growth/image-wall/4478d219-dd6d-496a-833f-2a3ce3fa1d9a.png]
Test 3 result: 2.1 preserved the product more faithfully, while Pro blended the lighting more aggressively but changed the product shape.
Test 4: Four-SKU composition
The models received four product references and were asked to place every item once in a single horizontal catalog composition without merging labels, changing colors, or inventing another SKU.
Both models extracted and arranged all four products successfully. Their overall results were close, and Pro retained slightly better small-text detail. The shared weakness was scale interpretation. “Equally scaled” was not precise enough to produce a consistent visual height across products with different shapes.
For a production prompt, replace vague sizing language with a measurable rule such as: “Make the visible body of every bottle 70% of the canvas height and align all bases to the same horizontal line.” The need for that extra instruction applies to both models.
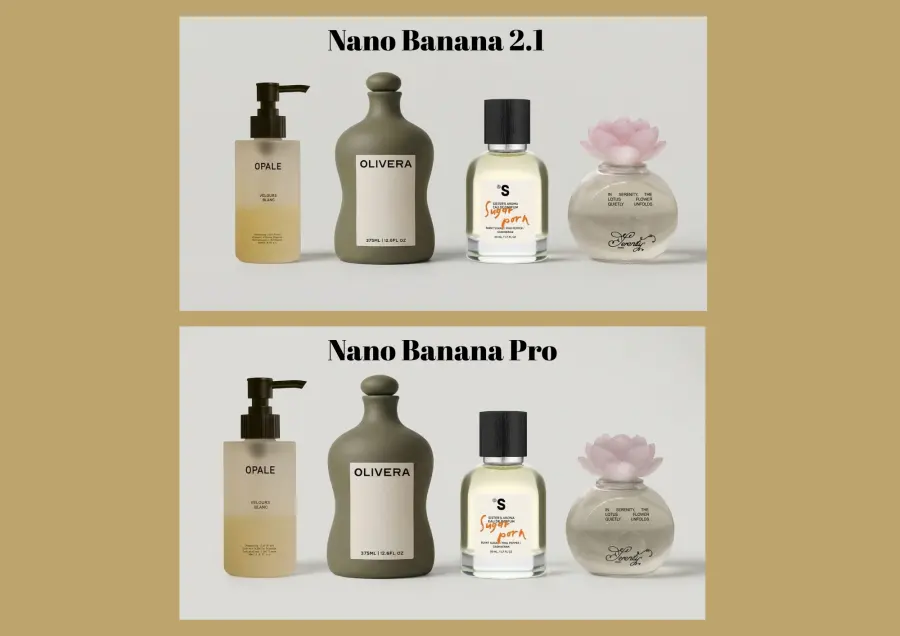
Test 4 result: both handled the four references well; Pro held a small advantage in fine label detail.
Test 5: Multilingual promotional poster
The poster required exact English and Japanese copy, including “YUZU SPARKLING WATER,” “ZERO SUGAR,” “6 CANS,” “¥1,280,” “ゆずスパークリング,” and “期間限定.”
Both models reproduced the multilingual text correctly. Nano Banana Pro produced a clean, readable product poster with a restrained grid. Nano Banana 2.1 created a more persuasive ad: the can, fruit, ice, water splash, promotional badge, and price box formed a clearer campaign hierarchy. It required less art-direction work before use as a retail or social creative.
This was the clearest example of 2.1 doing more than satisfying the literal instruction. It interpreted the marketing purpose of the prompt.
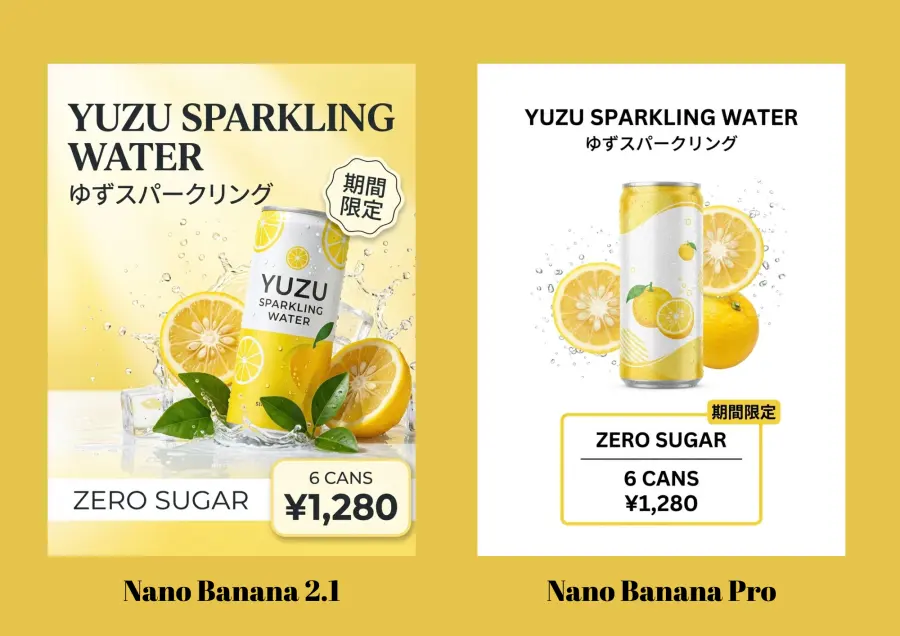
Test 5 result: both models handled English and Japanese correctly; 2.1 delivered the stronger layout and marketing intent.
Nano Banana 2.1 vs Nano Banana Pro Pricing
Google’s official Gemini API pricing makes 2.1 substantially cheaper at every resolution:
| Resolution |
Nano Banana 2.1 official price |
Nano Banana Pro official price |
2.1 savings |
| 1K |
$0.0336 |
$0.134 |
74.9% |
| 2K |
$0.0504 |
$0.134 |
62.4% |
| 4K |
$0.113 |
$0.240 |
52.9% |
On GPT Proto, a 1K image starts at $0.0201 with Nano Banana 2.1 and $0.0804 with Nano Banana Pro. That is a 75% reduction. At 1,000 images, the starting generation cost is approximately $20.10 versus $80.40—a $60.30 difference before accounting for retries.
| GPT Proto 1K volume |
Nano Banana 2.1 |
Nano Banana Pro |
Difference |
| 100 images |
$2.01 |
$8.04 |
$6.03 |
| 1,000 images |
$20.10 |
$80.40 |
$60.30 |
| 10,000 images |
$201.00 |
$804.00 |
$603.00 |
Price per generation is only the first layer. The better production metric is:
cost per accepted image = total generation spend / outputs that pass review
If Pro costs four times as much but does not deliver four times the accepted output rate, its premium is difficult to justify. If its style or character controls substantially reduce rework in a specific campaign, it may still be the cheaper model at the workflow level.
Pricing was checked on October 8, 2026. Image-model prices can change, so confirm the current value on each model page before publishing a fixed budget.
Planning hundreds or thousands of assets? See how to structure retries, concurrency, and output handling with a batch image generation API.
Which Model Is Better for Ecommerce Products?
For most ecommerce product work, start with Nano Banana 2.1. Our tests found a stronger combination of product fidelity, package design, multilingual layout, and marketing intent, while its starting 1K price was one quarter of Pro’s.
| Ecommerce use case |
Recommended starting model |
Why |
| Product hero images |
Nano Banana 2.1 |
More natural result in our test at lower cost |
| Packaging concepts |
Nano Banana 2.1 |
Strong text accuracy plus better design integration |
| Background replacement |
Nano Banana 2.1 |
Better product-shape preservation in our test |
| Multi-SKU catalog layouts |
Test both |
Results were close; Pro held slightly better small-text detail |
| Multilingual campaign posters |
Nano Banana 2.1 |
Better visual hierarchy and marketing interpretation in our test |
| Large catalog batches |
Nano Banana 2.1 |
Lower per-image cost and more object-reference slots |
| Five recurring people |
Nano Banana Pro |
Pro allocates references to as many as five characters |
| Style-led campaign system |
Nano Banana Pro |
Three dedicated style-reference slots |
| Existing verified Pro pipeline |
Keep Pro until retested |
Migration risk may outweigh immediate savings |
For broader comparisons beyond these two Google models, see our guide to the best AI image models for ecommerce.
A Practical Two-Model Workflow
A business does not need to choose one model forever. A simple routing strategy can capture most of 2.1’s cost advantage while keeping Pro available for specific failures:
Send the initial task to Nano Banana 2.1 and generate three candidates.
Validate required text, product count, label fidelity, colors, geometry, and aspect ratio.
Accept outputs that pass the rules without manual repair.
Rewrite ambiguous size or placement instructions once before changing models.
Route the remaining failures to Nano Banana Pro.
Compare acceptance rate, rework time, and cost per accepted image every month.
This approach is more useful than assigning every “important” image to Pro. It lets actual output quality determine when the premium model is worth using.
How to Test Both Models With One GPT Proto API Key
GPT Proto exposes both models through separate routes. The following examples use synchronous mode so the request waits for the generated result. Replace the environment variable with your own key; do not paste a key directly into source code.
Nano Banana 2.1 cURL request
curl --request POST "https://gptproto.com/api/v3/google/gemini-nano-banana-2.1/text-to-image" \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "prompt": "Create a clean 3:4 ecommerce hero image of one matte-white insulated bottle with a brushed silver cap and one thin cobalt-blue stripe. No logo or extra text.",
    "aspect_ratio": "3:4",
    "size": "1k",
    "output_formart": "png",
    "enable_base64_output": false,
    "enable_sync_mode": true
  }'
Nano Banana Pro cURL request
curl --request POST "https://gptproto.com/api/v3/google/gemini-3-pro-image-preview/text-to-image" \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "prompt": "Create a clean 3:4 ecommerce hero image of one matte-white insulated bottle with a brushed silver cap and one thin cobalt-blue stripe. No logo or extra text.",
    "size": "1K",
    "aspect_ratio": "3:4",
    "output_format": "png",
    "enable_sync_mode": true,
    "enable_base64_output": false
  }'
The two live schemas currently spell the output field differently: the 2.1 page shows output_formart, while the Pro page shows output_format. Copy the current example from the relevant model page if the schema changes.
For a fair comparison, save every result with the model and run number in its filename. Use the same prompt, references, aspect ratio, and output size, and avoid giving one model additional retries.
Prompt Tips for a Fair Comparison
A prompt should describe both the desired output and the details the model is not allowed to change.
Put exact packaging or poster copy in a separate block.
Use measurable constraints: “exactly four products,” “70% of canvas height,” or “align all bases.”
For edits, state the change first and list protected product elements second.
Separate product fidelity from background style when scoring results.
Run at least three outputs per model before deciding that a difference is stable.
Keep failed outputs in the test set; retries are part of the real cost.
For additional structures and examples, adapt these Nano Banana Pro prompts and keep every model-facing variable unchanged during the comparison.
Final Verdict
Nano Banana 2.1 is our default recommendation. It is substantially cheaper, ranks above Pro in current official and independent evaluations, and produced the more convincing result in three of our five direct comparisons. For ecommerce, the strongest difference was not basic prompt compliance: both models often followed the instructions. It was whether the output understood the commercial purpose of the prompt.
Pro remains a useful specialist. It preserved fine text slightly better in our multi-SKU test, offers another character-reference slot, and includes dedicated style references. But it should now be the exception that proves its value through a higher acceptance rate.
Start with Nano Banana 2.1 on GPT Proto, keep Nano Banana Pro available as a fallback, and let the cost per accepted image decide which model stays in your production route.