Quick Answer: What Are Claude Fable 5.1 and Mythos 5.1?
Claude Fable 5.1 and Claude Mythos 5.1 are two access versions of the same underlying Anthropic model. Fable 5.1 is available to regular Claude users and API customers with cybersecurity and biology safeguards. Mythos 5.1 is limited to approved organizations in Anthropic's trusted-access programs.
| Detail |
Claude Fable 5.1 |
Claude Mythos 5.1 |
| Release date |
September 1, 2026 |
September 1, 2026 |
| Underlying model |
Same |
Same |
| General API access |
Yes |
No |
| Access route |
Claude products, API, and partner clouds |
Project Glasswing and approved programs |
| Cybersecurity and biology access |
Additional safeguards and fallback routing |
Expanded access for vetted research |
| Claude API model ID |
claude-fable-5-1 |
claude-mythos-5-1 |
| Context window |
1 million tokens |
1 million tokens |
| Maximum output |
128,000 tokens |
128,000 tokens |
Anthropic's launch announcement describes the pair as the same model with different levels of safeguards. Its developer documentation lists Fable 5.1 for all Claude API customers and Mythos 5.1 for Project Glasswing participants only.
What Is the Relationship Between Claude Fable 5.1 and Mythos 5.1?
Fable and Mythos are not separate capability tiers in the way that Sonnet, Opus, and earlier Claude families were positioned. Anthropic says they use the same underlying model. The split occurs at the safeguards and access layer.
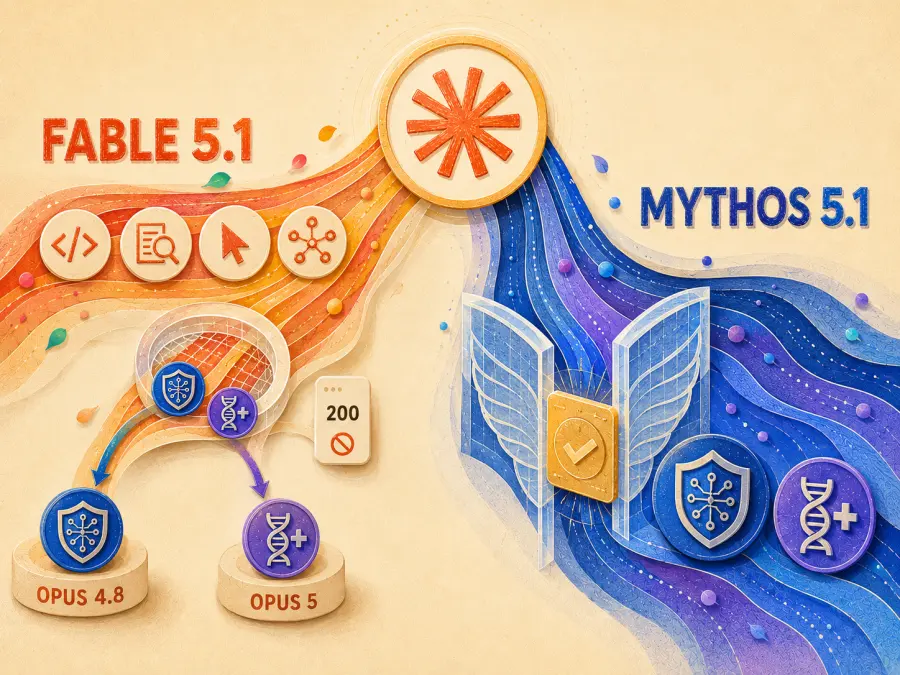
Fable 5.1 is the public product. It is intended for long-running coding, research, computer use, and knowledge work, but classifiers monitor requests in cybersecurity and biology. A flagged cybersecurity request can fall back to Claude Opus 4.8, while a flagged biology request can fall back to Claude Opus 5. API developers need to configure this behavior; a refusal can also arrive as an HTTP 200 response with stop_reason: "refusal" rather than as a conventional request error.
Mythos 5.1 is for organizations that Anthropic has reviewed and approved for work in areas such as defensive security and life sciences. It provides broader access to the same model's cyber and biology capabilities. That does not make Mythos a setting hidden inside the public Fable endpoint. Access is controlled by Anthropic, and approved customers must go through programs such as Project Glasswing.
The safeguards are also more precise than those launched with Fable 5. Anthropic reports that its new cybersecurity controls produce 60% fewer false positives. It says the biology safeguards intervene on benign requests 85% less often. Fable 5.1 can now identify vulnerabilities in source code, but penetration testing, exploit generation, and binary-based vulnerability scanning can still be restricted. These percentages come from Anthropic's own evaluation, not an independent audit. The Fable and Mythos product pages explain the current boundaries.
Both versions carry 30-day data retention by default for safety monitoring. Anthropic says its forthcoming Enterprise Frontier Safeguards will let eligible enterprise customers keep data in customer-controlled cloud infrastructure; until that rolls out, expressly authorized customers can receive zero-data-retention access. This is an access condition, not a general default for every Fable 5.1 API account.
In plain language: Mythos 5.1 is not “Fable 5.1 with max effort.” It is Fable 5.1 under a different access and safety arrangement.
Claude Fable 5.1 Features: What Changed From Fable 5?
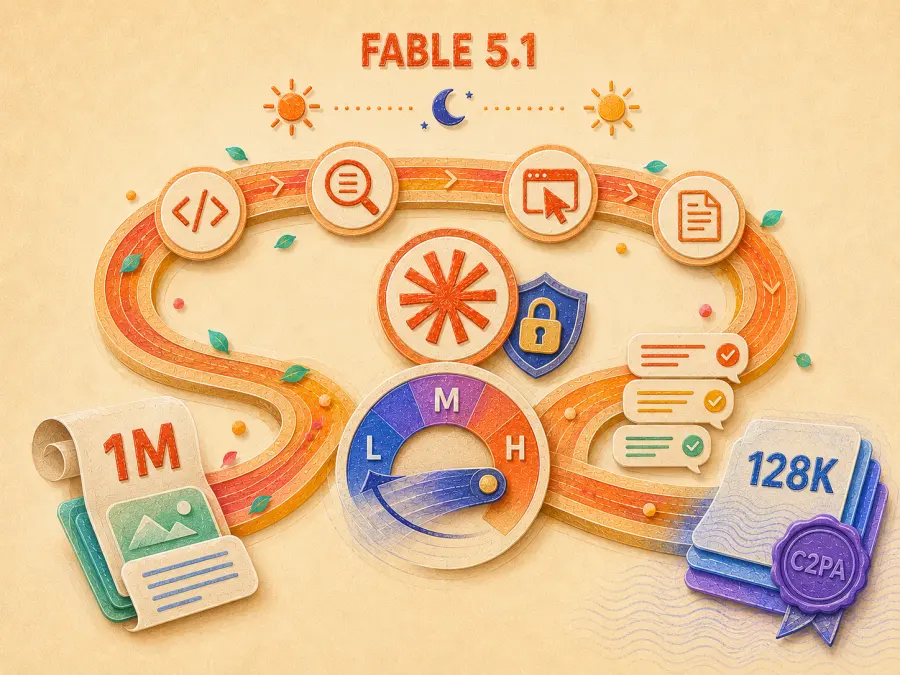
Fable 5.1 keeps the broad shape of Claude Fable 5: a 1-million-token context window, up to 128,000 output tokens, image and text input, and adaptive reasoning that is always enabled. The 5.1 upgrade concentrates on long-running work, controllable effort, agent communication, and fewer unnecessary safeguard interventions.
More capable long-running agents
Anthropic positions Fable 5.1 for assignments that can occupy an agent for hours or days: codebase-wide implementation, root-cause analysis, multi-stage research, document production, browser operation, and work that crosses several applications. High effort is the default in Claude Code, while Medium is the default in Claude.ai and Claude Cowork.
The claimed improvement is not just more reasoning at the highest setting. Anthropic says Fable 5.1 at Low or Medium effort can match or beat Fable 5 on some measured tasks at lower cost. That makes effort selection part of deployment design rather than a decorative control. Routine retrieval and formatting may not need Max; a difficult architectural diagnosis might.
Effort can change inside a conversation
With a beta feature, an application can raise or lower effort mid-conversation without invalidating the prompt cache. An agent could use High effort to plan a migration, then switch to Low effort to summarize the completed steps. Claude Opus 5 also supports this behavior.
Fable 5.1 additionally supports turn-scoped system messages. A temporary instruction can apply to the current turn and clear on the next user message while remaining in the append-only message history. This is useful for tool loops that need short-lived reminders without rewriting earlier context.
Progress updates and content provenance
Developers can request readable status updates between tool calls with the beta thinking.display: "updates" option. Raw chain-of-thought is still not returned. The feature exposes short progress messages while keeping private reasoning hidden.
Anthropic also says text generated by Fable 5.1 and Mythos 5.1 carries its statistical text watermark. Supported image and video files produced through tools can receive signed C2PA Content Credentials when retrieved through the Files API. These features do not add visible characters or billable tokens to the text response.
Not every behavior change is an improvement
The migration notes are unusually candid about regressions and trade-offs:
Parallel tool calling can be more variable. Fable 5.1 may perform one call per turn where Fable 5 previously batched several independent calls. Extra turns add round trips, tokens, and wall-clock time.
At Low effort, the model is more likely to answer from memory rather than call a search or retrieval tool. Tasks that require current information need a higher effort level or an explicit verification instruction.
Progress narration is less frequent during long runs unless the application requests it.
Prose can be denser, with longer sentences and fewer paragraph breaks.
For a small file edit, the model may rewrite the whole file instead of returning a targeted patch, increasing output cost.
Document summaries can reproduce source wording without consistently marking it as a quotation.
These are not reasons to reject the upgrade. They are reasons to rerun an agent's own evaluations instead of assuming a higher model number preserves every behavior.
Claude Fable 5.1 vs Claude Fable 5
| Area |
Claude Fable 5 |
Claude Fable 5.1 |
| Standard input |
$10 / 1M tokens |
$10 / 1M tokens |
| Standard output |
$50 / 1M tokens |
$50 / 1M tokens |
| Cache read |
$1 / 1M tokens |
$0.25 / 1M tokens |
| Context window |
1M tokens |
1M tokens |
| Maximum output |
128K tokens |
128K tokens |
| Adaptive thinking |
Always on |
Always on |
| Mid-conversation effort |
No equivalent launch feature |
Supported in beta |
| Safeguard false positives |
Higher |
Reduced in Anthropic's testing |
| Forced named tool choice |
Existing integrations may use it |
any and named tool return an error |
| Content provenance |
Earlier behavior |
Statistical text watermark and C2PA support |
One additional billing detail deserves attention. Fable 5.1 uses the same tokenizer as Fable 5, introduced with Claude Opus 4.7. Anthropic says the same text can produce roughly 30% more tokens than it did on models older than Opus 4.7. Teams migrating from Fable 5 will not see that tokenizer jump, but teams comparing 5.1 with older Claude generations should not estimate cost from character count alone.
Claude Fable 5.1 Pricing: Cheaper Cache, but Not Always a Cheaper Task
Fable 5.1 preserves Fable 5's headline API rates. The change is concentrated in prompt caching.
| Billing item |
Claude Fable 5.1 official price |
| Standard input |
$10 / 1M tokens |
| 5-minute cache write |
$12.50 / 1M tokens |
| 1-hour cache write |
$20 / 1M tokens |
| Cache read |
$0.25 / 1M tokens |
| Standard output |
$50 / 1M tokens |
| Batch input |
$5 / 1M tokens |
| Batch output |
$25 / 1M tokens |
The cache read rate fell from $1 to $0.25 per million tokens, a 75% reduction. That matters for agents that repeatedly read a large system prompt, repository map, tool definitions, or accumulated working context. Anthropic estimates typical token-billed workloads will cost about 25% less than Fable 5, while highly agentic workloads may save as much as approximately 45%. The full rates and cache multipliers are in the Claude pricing documentation.
But “75% cheaper cache” is not the same claim as “75% cheaper model.” Fresh input remains $10 and output remains $50. If a new effort setting produces a longer reasoning trace or answer, the output bill can erase the cache saving.
That happened in Artificial Analysis's pre-release evaluation. Its launch analysis found that Fable 5.1 at Max effort used roughly 1.7 times as many output tokens as Fable 5 Max. Its measured cost was about $3.7 per Intelligence Index task—around 20% above Fable 5 Max—even after the cache discount. At Extra-high effort, the model scored one point below Max on the index but cost materially less per task.
This is the more useful cost conclusion:
Fable 5.1 is cheaper at rereading cached context. Whether it is cheaper at completing your task depends on cache hits, effort, output length, tool rounds, and fallback behavior.
Before switching production traffic, compare cost per accepted result, not price per million cached tokens.
How Strong Is Claude Fable 5.1? Benchmarks and Their Limits
Anthropic reports large improvements over Fable 5 on scientific research, terminal work, business automation, and agentic coding. The launch table below uses Anthropic's own test setup, so it should be read as vendor evidence rather than a neutral verdict.
| Benchmark |
Fable 5.1 |
Fable 5 |
Opus 5 |
GPT-5.6 Sol |
| Terminal-Bench-Science 0.1 |
52.6% |
24.7% |
29.0% |
22.4% |
| Terminal-Bench 4.0 |
55.8% |
42.0% |
52.3% |
37.3% |
| GDPval-AA v2 |
1,853 |
1,723 |
1,824 |
1,711 |
| OSWorld 2.0, strict |
41.7% |
36.1% |
39.6% |
— |
| Humanity's Last Exam, no tools |
60.9% |
57.8% |
56.6% |
— |
| AutomationBench |
31.4% |
17.1% |
26.9% |
19.6% |
| CursorBench 3.2.0 |
73.4% |
70.5% |
70.0% |
67.2% |
Source: Anthropic's Fable 5.1 and Mythos 5.1 launch report.
On Terminal-Bench 4.0, Mythos 5.1 scored 60.9% against Fable 5.1's 55.8%. Anthropic attributes this gap to tasks where Fable's cyber safeguards intervened, not to a different base model. The company also notes that some benchmark requests routed to Opus models when safeguards fired.
Independent testing puts Fable 5.1 first—with a caveat
Artificial Analysis evaluated Fable 5.1 before release and scored Max effort at 66 on its Intelligence Index. At the time of launch, that placed it ahead of Opus 5 Max at 63, Fable 5 Max at 62, GPT-5.6 Sol Max at 61, and the Max configurations of Kimi K3 and GLM-5.3 at 60.
| Model and setting |
Artificial Analysis Intelligence Index |
| Claude Fable 5.1 Max |
66 |
| Claude Opus 5 Max |
63 |
| Claude Fable 5 Max |
62 |
| GPT-5.6 Sol Max |
61 |
| Kimi K3 Max |
60 |
| GLM-5.3 Max |
60 |
The caveat is important: Artificial Analysis enabled Anthropic's default server-side fallback. Opus 4.8 or Opus 5 generated about 4% of output tokens across the index when safety classifiers intervened. The 66 score therefore represents a realistic Fable 5.1 production configuration, not a laboratory run in which every token came from Fable alone.
Independent results also reveal a less flattering trade-off. On AA-Omniscience, Fable 5.1 attempted more questions and achieved higher raw accuracy than Fable 5. But when it did not know the correct answer, it was also more likely to attempt one. The two effects canceled each other out on the benchmark's reliability index. More willing to answer is not automatically less likely to hallucinate.
The honest benchmark reading is conditional. Fable 5.1 has the strongest early composite result, particularly for agentic and knowledge work, but it is expensive and verbose at Max. A team choosing a production model should compare the effort levels against its own acceptance criteria rather than deploy Max everywhere.
Claude Fable 5.1 vs Opus 5, GPT-5.6 Sol, Kimi K3, and GLM-5.3
The models below overlap in coding, research, and agent work, but they occupy very different price and deployment positions. Prices in this table are direct vendor list rates per million standard input and output tokens; linked GPT Proto model pages may offer different rates.
| Model |
AA Intelligence Index, Max |
Direct input / output price |
Practical reason to choose it |
| Claude Fable 5.1 |
66 |
$10 / $50 |
Highest-end long-running reasoning and agent work |
| Claude Opus 5 |
63 |
$5 / $25 |
Lower-cost Anthropic default for most workloads |
| GPT-5.6 Sol |
61 |
$5 / $30 |
Agent efficiency, coding, computer use, and multi-agent execution |
| Kimi K3 |
60 |
$3 / $15 |
Open weights, image input, and lower API cost |
| GLM-5.3 |
60 |
$1.40 / $4.40 |
Lower-cost text coding and agent workflows |
Price sources: Anthropic, OpenAI, Moonshot AI, and Z.AI. Independent index results come from Artificial Analysis.
Claude Fable 5.1 vs Claude Opus 5
Fable 5.1 has the higher measured ceiling, but Opus 5 costs half as much per standard input and output token. Anthropic's own developer guide tells most workloads to start with Opus 5 and use Fable 5.1 when demanding reasoning or long-horizon work still falls short at higher Opus effort. That is unusually direct guidance: the newest, highest-scoring model is not the recommended default.
Choose Fable 5.1 when the value of solving a difficult task justifies extra inference cost. Keep Opus 5 when it already passes the evaluation, particularly for high-volume production traffic.
Claude Fable 5.1 vs GPT-5.6 Sol
Fable 5.1 leads the current Artificial Analysis composite index, while GPT-5.6 Sol has lower list pricing and is designed around token-efficient tool use, computer operation, and multi-agent execution. Anthropic's launch table favors Fable 5.1 on several shared tests, but those results use Anthropic's harness. OpenAI's GPT-5.6 report publishes different evaluations that favor GPT-5.6 Sol over the previous Fable 5 in coding efficiency.
The safest conclusion is workload-specific. Fable 5.1 is the stronger early candidate for a single difficult, long-running reasoning job. GPT-5.6 Sol deserves priority when cost, parallel workstreams, and tool-call efficiency matter as much as peak composite intelligence.
Claude Fable 5.1 vs Kimi K3
Kimi K3 reaches 60 on the same independent index while charging $3 per million input tokens and $15 per million output tokens. It also offers open weights, a 1-million-token context window, and native image understanding. Fable 5.1 scores higher, but it is proprietary and costs more than three times as much on standard input and output.
Use Fable 5.1 for tasks where the last few points of measured capability have a clear business value. Kimi K3 is easier to justify when private deployment, model access, or inference budget is central to the decision.
Claude Fable 5.1 vs GLM-5.3
GLM-5.3 also scores 60 on the Artificial Analysis index and supports a 1-million-token context window. Its direct rates are $1.40 per million input tokens and $4.40 per million output tokens. Unlike Fable 5.1, the standard GLM-5.3 model is text-only.
Fable 5.1 is the better fit for difficult visual-document work and the highest-end autonomous assignments. GLM-5.3 is the more economical option for text-based coding and agents, especially when a team needs to run many tasks rather than maximize the success probability of one expensive task.
Migrating From Claude Fable 5 to Fable 5.1
Changing the model ID is necessary, but it is not the whole migration.
1. Update the Claude API model ID
This runnable Python example uses Anthropic's official SDK and the public Fable 5.1 model ID:
import os
from anthropic import Anthropic

client = Anthropic(api_key=os.environ["ANTHROPIC_API_KEY"])

response = client.messages.create(
    model="claude-fable-5-1",
    max_tokens=4096,
    messages=[
        {
            "role": "user",
            "content": "Review this migration plan and identify the three highest-risk assumptions.",
        }
    ],
)

for block in response.content:
    if block.type == "text":
        print(block.text)
Existing Fable 5 code changes from:
model = "claude-fable-5"
to:
model = "claude-fable-5-1"
2. Remove forced tool choice
Fable 5.1 does not support tool_choice values of any or a named tool. Either returns a 400 invalid_request_error:
tool_choice: type "tool" and "any" are not supported for this model.
Use automatic selection instead:
{
  "tool_choice": {"type": "auto"}
}
If the output must match a JSON schema, combine automatic tool choice with strict tool use or structured outputs. If the model must call a particular tool, state the condition explicitly in the prompt and validate the returned action.
3. Keep thinking-block history append-only
Fable 5.1 can read thinking blocks produced by earlier Claude models. Earlier models cannot read thinking blocks produced by Fable 5.1. A conversation can move from Opus 5 or Fable 5 to Fable 5.1 and preserve reasoning state, but moving back drops the newer thinking blocks.
Editing an earlier message, changing the top-level system prompt, rebuilding the tools array, or serving different file bytes at the same document URL can also invalidate later thinking blocks. Where enforcement is active, the API can return:
The block is bound to a different conversation
Treat long-running conversation history as append-only. Add temporary instructions through mid-conversation or turn-scoped system messages, and use server-side compaction or context editing instead of silently rewriting earlier turns. Anthropic's Fable 5.1 migration notes document the accepted patterns.
4. Re-run cost and behavior evaluations
At minimum, measure:
accepted-result rate at Low, Medium, High, and Max effort;
output and reasoning tokens per completed task;
prompt-cache hit rate;
number of tool rounds and parallel tool calls;
time to first useful answer;
refusals and fallback frequency;
whether Low effort still triggers search when fresh information is required;
whether small file edits remain targeted.
A model can score higher while making a particular agent slower or more expensive. Migration is complete only when the new configuration passes the workload's own quality and cost thresholds.
Evaluating the current Fable model through GPT Proto
GPT Proto's current model page exposes Claude Fable 5 through an OpenAI-compatible chat endpoint. The following call uses the listed claude-fable-5 ID; it does not pretend that the ID is Fable 5.1:
curl --request POST "https://gptproto.com/v1/chat/completions" \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "model": "claude-fable-5",
    "messages": [
      {
        "role": "user",
        "content": "Review this migration plan and identify the three highest-risk assumptions."
      }
    ]
  }'
You can try Claude Fable 5 through GPT Proto or use the linked GPT-5.6 Sol, Kimi K3, and GLM-5.3 pages to evaluate lower-cost alternatives with the same account and balance. Before using a future Fable 5.1 route, confirm its exact model ID on the model page rather than guessing it from Anthropic's ID.
What Early Testers and Developers Are Saying
Early reaction is split between excitement about long-running work and distrust of launch benchmarks.
Every tested Fable 5.1 for about a week across coding, writing, and knowledge work. Its team reported that the model was easier to communicate with than the original Fable, could work for extended periods, and used less than half the tokens of Opus 5 on some comparable tasks. Their hands-on review also recorded limitations: Fable 5.1 still exceeded requested word counts, and at higher effort it sometimes continued working after a tester interrupted to ask what it was doing. The team did not directly measure savings against Fable 5.
That is useful evidence, but it is still an early-access report from one team. It does not establish a general cost or reliability result.
The launch discussion in r/ClaudeAI was more skeptical. Several commenters questioned whether published benchmarks would translate into everyday coding and pointed to the absence of a DeepSWE result in Anthropic's headline table. Others treated the cache-read reduction as the most consequential part of the announcement because cached context represents most of their agent usage.
Both reactions can be true. Fable 5.1 can be a meaningful upgrade for difficult delegated work while still being overspecified and overpriced for ordinary chat, routine coding, or short tool calls. Launch-day sentiment cannot settle that choice; repeated workload testing can.
Should You Upgrade to Claude Fable 5.1?
Choose Fable 5.1 when:
a task runs for hours or days and failure is more expensive than inference;
Opus 5 at higher effort still misses your acceptance threshold;
the workload combines code, visual documents, research, and several tools;
the agent repeatedly reads a large cached prefix;
your integration can handle refusals, fallback, append-only thinking blocks, and automatic tool choice;
you will tune effort per task instead of sending every request at Max.
Stay with Opus 5 or Fable 5 when:
the current model already passes your evaluation;
workloads are short, predictable, and output-heavy;
the application depends on forced named tool calls;
conversation history is regularly rewritten on the client;
the team cannot yet monitor fallback and refusal behavior;
cost matters more than the final few points on a composite benchmark.
Consider Kimi K3 or GLM-5.3 when:
API cost is a binding constraint;
open weights or self-hosting matter;
the workload consists mainly of text-based coding and agent tasks;
you need to process many jobs and can tolerate a lower peak benchmark score;
routing each job to a suitable model is more economical than standardizing on the most expensive option.
Claude Fable 5.1 is therefore a high-ceiling specialist, not an automatic replacement for every Claude deployment.
Final Verdict
Claude Fable 5.1 and Claude Mythos 5.1 are the same underlying model offered through two access arrangements. Fable is the public version with additional cybersecurity and biology safeguards. Mythos is reserved for vetted organizations that need broader capabilities in those areas. Ordinary developers cannot enable Mythos through a model parameter.
The 5.1 upgrade brings stronger early results on long-running coding, scientific research, knowledge work, and business automation. It also adds useful controls for changing effort, temporary system instructions, progress updates, and content provenance. The cost story is narrower than the headline suggests: cache reads are 75% cheaper, but output rates are unchanged, and independent testing found that Max effort could still cost more per completed evaluation task than Fable 5.
If an existing Opus 5 or Fable 5 deployment already works, keep it until Fable 5.1 passes the same task-level evaluation. If the current model fails on difficult, multi-stage assignments, Fable 5.1 is one of the first candidates worth testing. For price-sensitive text agents, GLM-5.3 offers a much lower rate. Kimi K3 adds open weights and image input, while GPT-5.6 Sol emphasizes efficient tool use and multi-agent execution.
The right comparison is not model name against model name. It is accepted result, total tokens, time, and cost on the work your application actually performs.