2026년 중국 LLM 모델 한눈에 보기
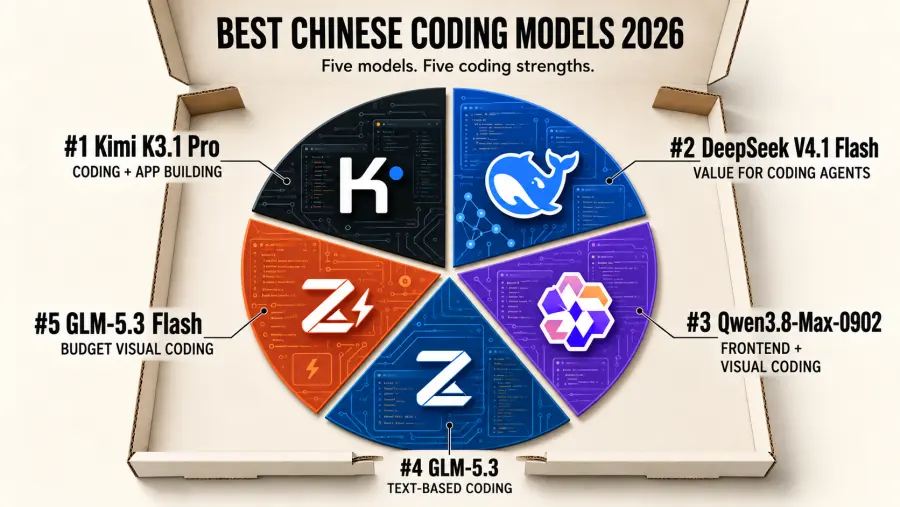
| 순위 |
모델 |
권장 용도 |
주요 고려 사항 |
| 1 |
Kimi K3.1 Pro |
난이도 높은 코딩, 앱 빌딩 및 확장된 에이전트 작업 |
가성비 모델 대비 높은 토큰 비용 |
| 2 |
DeepSeek V4.1 Flash |
비용 효율적인 코딩 에이전트 및 반복적인 구현 작업 |
1017 벤치마크 결과 적용 전 제공되는 체크포인트 확인 필요 |
| 3 |
Qwen3.8-Max-0902 |
프론트엔드 구현 및 시각적 디버깅 |
DeepSeek 및 GLM Flash 대비 높은 토큰 비용 |
| 4 |
GLM-5.3 |
텍스트 기반 리포지토리 조사 및 터미널 작업 |
네이티브 시각적 증거 확인을 위한 별도 경로 필요 |
| 5 |
GLM-5.3 Flash |
가성비 시각적 코딩 및 빈번한 에이전트 하위 작업 |
단독 프로덕션 모델로 사용 전 난이도 높은 작업 테스트 권장 |
가격 비교는 아래와 같습니다. 가격과 성능을 분리하여 살펴보면, 특정 작업에서 왜 더 비싼 모델을 테스트할 가치가 있는지 쉽게 이해할 수 있습니다.
속도 측정값은 Artificial Analysis에서 측정한 각 모델 제작사의 API 기준입니다. 이는 스냅샷일 뿐이며 GPT Proto에 대한 지연 시간을 보장하지는 않습니다. 제공업체의 부하, 프롬프트 길이, 추론 노력, 캐시 동작 및 출력 길이에 따라 실제 성능은 달라질 수 있습니다.
The modality column describes the routes exposed by GPT Proto. A downloadable checkpoint and a hosted API with a similar name may not expose identical features.
중국 LLM 모델의 평가 기준
매개변수 규모가 크거나 100만 토큰의 컨텍스트 윈도우를 지원한다고 해서 해당 모델이 실제 리포지토리 작업을 완벽히 수행할 수 있는 것은 아닙니다. 이번 중국 LLM 순위에서 다루는 5개 모델은 모두 비슷한 수준의 긴 컨텍스트 처리 능력을 갖추고 있으며, 실질적인 차이는 다른 부분에서 나타납니다.
저희는 다음 6가지 질문을 고려했습니다:
개발사가 제공하는 벤치마크 차트가 아닌, 독립적인 평가에서 모델이 어떤 성능을 보이는가?
다중 파일 코딩, 터미널 작업, 도구 호출, 그리고 '계획-실행-검증' 루프를 안정적으로 수행할 수 있는가?
텍스트 외에 스크린샷, 다이어그램, 문서, 기록된 제품 흐름 등을 분석할 수 있는가?
출력 토큰, 추론 비용, 그리고 발생 가능한 재시도 횟수를 포함했을 때 실제 API 작업 비용은 얼마인가?
모델 가중치를 실제로 다운로드할 수 있으며, 상업적 배포를 위한 라이선스는 무엇인가?
독자가 동일한 계정과 API 형식으로 테스트해 볼 수 있는 실시간 GPT Proto 경로가 존재하는가?
현재 Artificial Analysis 리더보드에 따르면, Intelligence Index 점수는 Kimi K3.1 Pro가 46점, Qwen3.8 Max 0902가 34점, DeepSeek V4.1 Flash 1017(최대 추론)과 GLM-5.3(최대 추론)이 각각 32점을 기록하고 있습니다. 이 지수는 광범위한 성능 측정치일 뿐, 애플리케이션의 버그를 수정하는 실제 비용을 직접적으로 측정하지는 않습니다.
해당 점수는 Intelligence Index v5.0 기준입니다. 이전 버전의 지수와 혼합하거나, 평가 버전 변경에 따른 점수 변화를 모델 자체의 성능 저하로 해석해서는 안 됩니다. 또한 현재 리더보드에 비교 가능한 값이 없는 경우, GLM-5.3 Flash에 이전 지수 점수를 임의로 부여하지 않았습니다.
코딩 결과는 지표마다 다를 수 있습니다. Artificial Analysis의 DeepSeek-GLM 비교를 보면, GLM은 Terminal-Bench 4.0에서 앞서고, DeepSeek는 FrontierCode 2.0에서 우위를 점합니다. 이러한 차이 때문에 본 리스트는 작업별 추천 사항을 포함하고 있으며, 비용 요소를 고려하여 순서를 정했습니다.
1. Kimi K3.1 Pro: Best Overall Coding Candidate
Kimi K3.1 Pro moves into first place because the new release brings stronger evidence for difficult, extended software work. Moonshot's technical blog reports 65.7% on Terminal-Bench 4.0 and 61.2% on its internal Kimi Code Bench 3.0 Long-horizon, compared with K3's 55.95% on the latter. These are vendor-reported results.
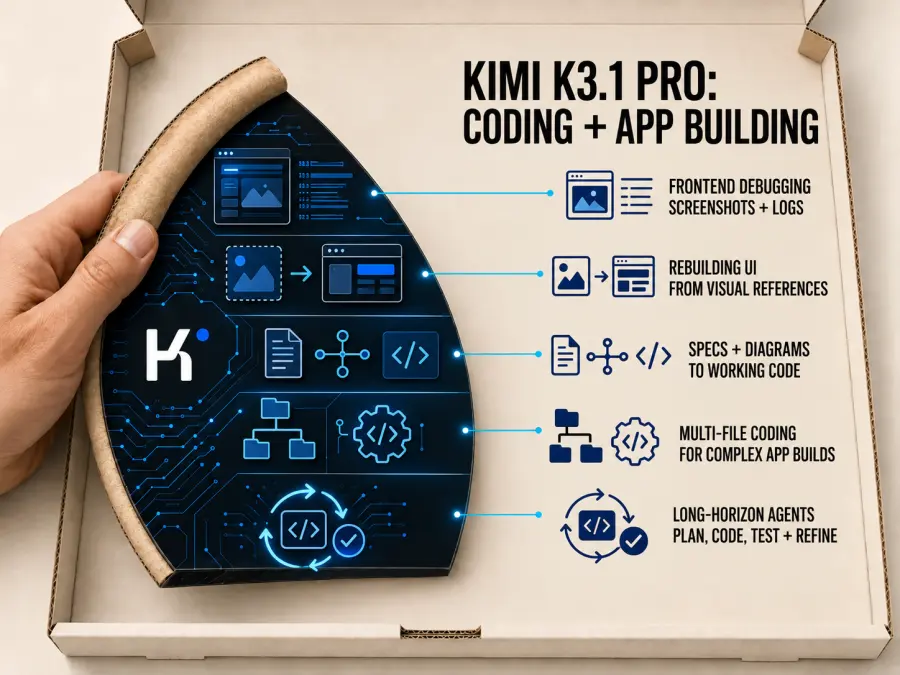
There is an independent signal as well: Artificial Analysis records approximately 67% on Terminal-Bench 4.0. That result belongs to its evaluation setup; it should remain separate from Moonshot's number.
I would test K3.1 Pro first when an agent must understand an unfamiliar application, change several connected files, and keep working after a failed test. For app builders, the useful question is whether it can deliver a feature that meets the brief after implementation and correction.
Its GPT Proto route accepts text and visual input. That makes it a candidate for work combining source code, a design reference, and a rendered interface. It is still worth starting with a bounded task: define the expected behavior and give the agent a way to verify it.
The higher token bill is the trade-off. Reserve it for work where improved completion quality can justify the expense. Also keep deployment status precise: as of this update, Moonshot schedules the full K3.1 Pro weights for release by November 4. Existing K3 weights do not establish that K3.1 Pro is already downloadable.
Verdict: Start with Kimi K3.1 Pro for a difficult feature or app build, then compare accepted changes and total spend with a cheaper candidate.
2. DeepSeek V4.1 Flash: Best Value for Coding Agents
DeepSeek deserves a higher position when the goal is to keep useful coding capability within a repeatable production budget. It is a candidate for agents that read code, propose patches, inspect test output, and make another attempt.
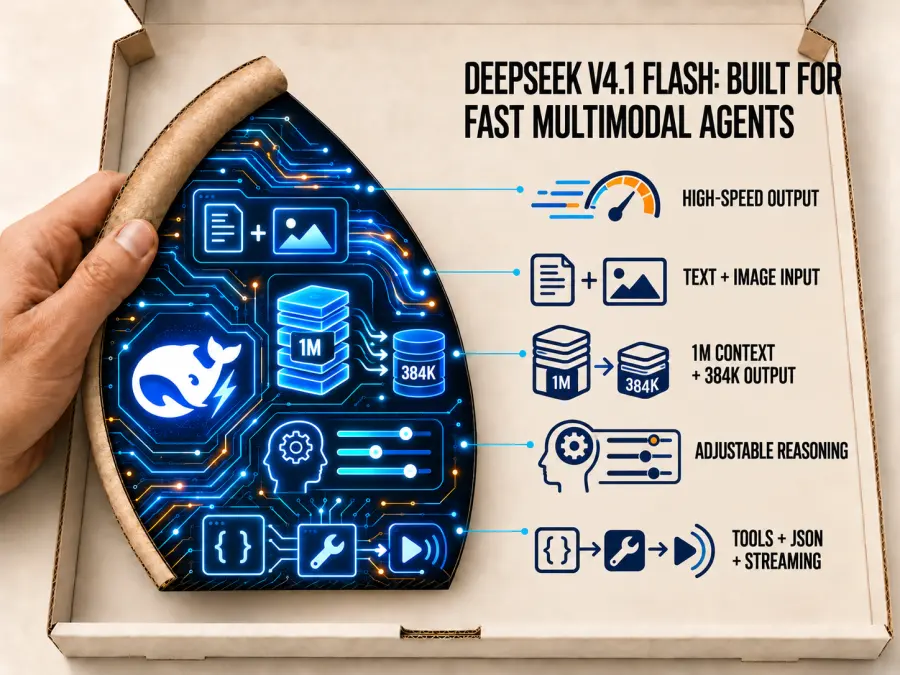
The DeepSeek V4.1 Flash 1017 model card reports improvements over the earlier V4.1 Flash release: Terminal-Bench 4.0 rises from 31.2 to 42.3, DeepSWE v1.1 from 74.2 to 77.0, and ProgramBench from 20.3 to 29.1. These are DeepSeek's reported evaluations, rather than a GPT Proto reproduction.
That update strengthens the case for including DeepSeek in a coding trial. It does not make every other model redundant. Independent coding evaluations still show different winners depending on the task, and a production agent must be judged on the tools and limits it will actually use.
Keep the route distinction explicit. GPT Proto exposes DeepSeek Flash using deepseek-flash; its public page describes V4.1 Flash without identifying the 1017 checkpoint. Confirm the deployed revision before treating the newer results as evidence about that exact endpoint.
Verdict: Test DeepSeek as the value-first implementation model. Record the model revision alongside success rate, retries, latency, and spend so a later alias update does not make the comparison ambiguous.
3. Qwen3.8-Max-0902: Best Fit for Frontend and Visual Debugging
Qwen remains a useful choice when a coding task starts with something visible: a reference page, a broken layout, a chart, or a sequence of interface states. The Qwen3.8-Max-0902 route supports multimodal input, allowing an application to combine visual material with code and instructions.
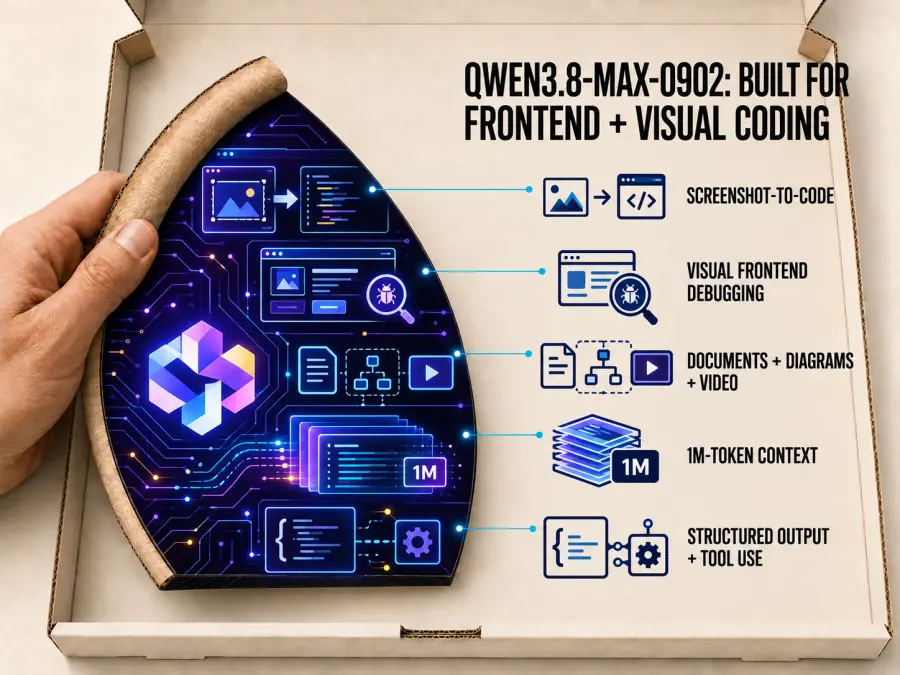
For a frontend evaluation, give it the same design reference and repository access as the other candidates. Ask the agent to implement the page, render it, check the important states, and correct the result. Judge spacing, hierarchy, responsiveness, and working interactions alongside code correctness.
That is why Qwen keeps a dedicated place here even after Kimi's upgrade. A frontend selection needs visual acceptance criteria, and a general intelligence score only partly describes that work. This is our workflow recommendation; it is not a claim that Qwen has won a new five-model frontend test.
The cost trade-off is straightforward: its displayed token rates are higher than DeepSeek's and GLM Flash's. For a small text-only patch, include one of those cheaper routes in the trial. Also keep the exact 0902 hosted snapshot separate from any related downloadable checkpoint when documenting features.
Verdict: Put Qwen on the shortlist when matching a visual brief is central to whether the implementation succeeds.
4. GLM-5.3: Best Fit for Text-Based Repository Work
GLM-5.3 remains relevant for code investigation, terminal tasks, and changes whose evidence is available as text. The updated ranking gives Kimi the overall recommendation while keeping GLM as a focused coding candidate.
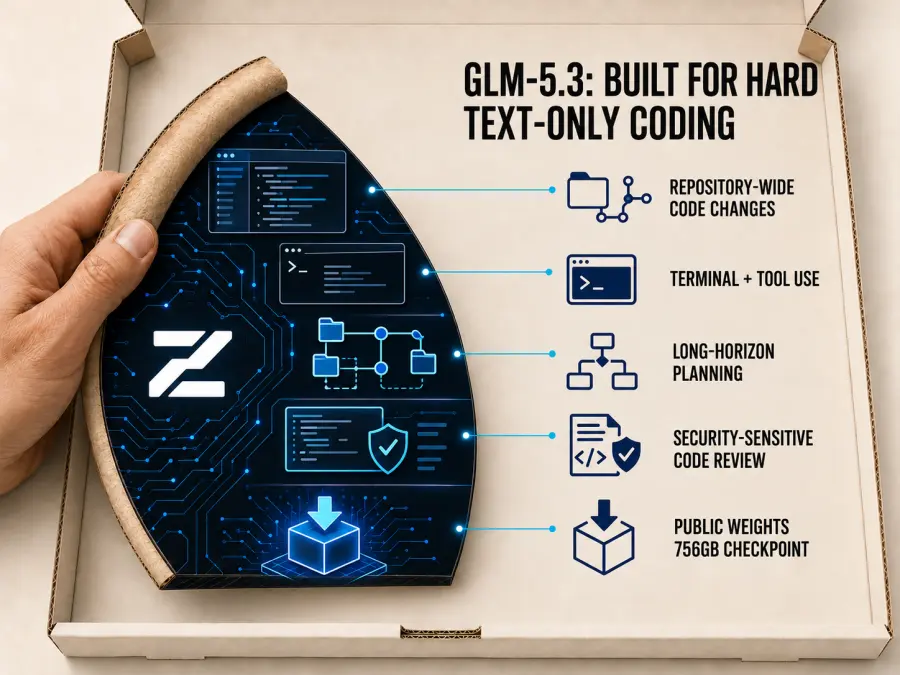
The independent DeepSeek–GLM comparison illustrates its position: GLM scores 42% on Terminal-Bench 4.0 against DeepSeek 1017's 34%, while FrontierCode 2.0 favors DeepSeek, 28% to 22%. Those results describe that evaluator's setup, so they should not be substituted for the vendors' differently configured runs.
I would keep GLM in a trial involving a failing backend integration, an unfamiliar dependency, or a repository change that requires several command-and-test cycles. The acceptance criteria should include a passing reproduction test and an explanation of what changed.
The GPT Proto GLM-5.3 page documents text input and text output. If the agent needs to inspect a screenshot directly, use a visual route for that step. Its higher token rates than the budget models also make repeated retries worth measuring.
Verdict: Keep GLM-5.3 for repository and terminal workflows where it passes your tests consistently. Compare it with Kimi for difficult tasks and with DeepSeek for cost.
5. GLM-5.3 Flash: Best Budget Visual-Coding Candidate
GLM-5.3 Flash keeps its place because frequent agent calls can make token rates matter more than a small difference in headline capability. It has the lowest displayed input and output rates among these five GPT Proto entries in the pricing snapshot below.
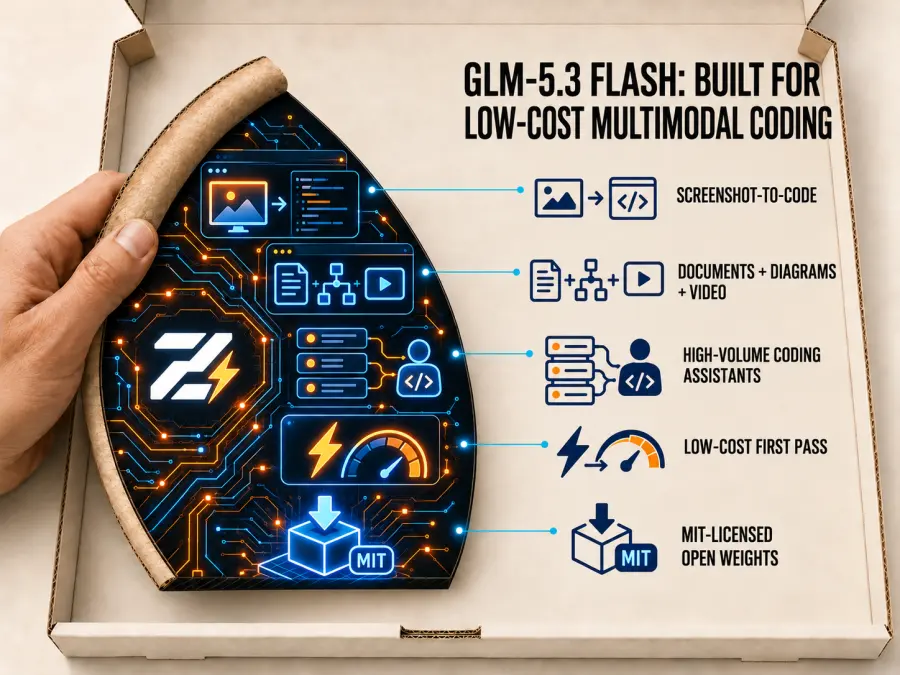
The model page documents text, image, video, and file input, along with MIT-licensed weights. It also explains that Flash uses a different multimodal base from standard GLM-5.3. Treat the two as separate candidates when building a routing policy.
A practical evaluation would assign Flash a bounded issue, a visual layout check, or an initial implementation. Keep the same acceptance tests used for the larger models. If the result fails, count the failed attempt and the escalation in the total cost.
Low rates leave room for iteration, but repeated unproductive attempts can erase that advantage. Measure how often the task succeeds before choosing it as the default. Reasoning is always enabled on the documented model, so include reasoning-token use and response time in that check.
Verdict: Test GLM-5.3 Flash as the budget default for visual coding and recurring subtasks, with a clear escalation path for failures.
기타 주목할 만한 중국 LLM 모델
MiniMax M3.1 Flash
MiniMax's current candidate deserves attention beyond the older M3 entry. The October 19 release announcement reports 73.7% on DeepSWE v1.1 and emphasizes lower-cost agent execution. That makes M3.1 Flash relevant to the same budget discussion as DeepSeek and GLM Flash.
Keep it in the research shortlist until the exact GPT Proto route, model ID, pricing, and supported features are confirmed. An existing MiniMax M3 endpoint should not be labeled M3.1 Flash without verification.
Xiaomi MiMo-V2.6 and Other Emerging Models
MiMo-V2.6 remains worth monitoring; Artificial Analysis includes MiMo-V2.6-Pro in its evaluations. Give a new model a main-list position after checking both its task evidence and the actual access path being recommended.
Older Kimi K3 and DeepSeek V4 Pro deployments may still be worth keeping when an application depends on validated behavior. Test a replacement on those same tasks before moving existing traffic.
Models to Watch
Step 5 Preview and Xiaomi’s MiMo-V2.6 family are relevant new Chinese models, but they are not included in the main ranking because GPT Proto did not have confirmed live routes for them at the time of this update. Add them to the ranked list only after the exact model page, API string, price, and supported request fields are live and tested.
하나의 실제 코딩 작업, 다섯 가지 다른 선택지
기존 TypeScript SaaS 애플리케이션에 구독 결제 기능을 추가한다고 가정해 보겠습니다. 에이전트는 현재 사용자 모델을 이해하고, 결제 흐름을 구현하며, 웹훅 이벤트를 안전하게 처리하고, 계정 권한을 업데이트하며, 결과를 검증해야 합니다.
| 요구사항 |
평가 대상 |
확인 항목 |
| 여러 파일에 걸쳐 연결된 기능 구현 |
Kimi K3.1 Pro |
올바른 동작, 일관된 변경 사항, 테스트 실패 후 복구 능력 |
| 반복적인 구현 및 수정 시도 실행 |
DeepSeek V4.1 Flash |
비용 대비 수락된 수정 사항; 제공된 리비전 기록 |
| 결제 인터페이스를 디자인 참조와 일치 |
Qwen3.8-Max-0902 |
시각적 정확성, 반응형 동작 및 작동 상태 |
| 백엔드 및 터미널 오류 진단 |
GLM-5.3 |
재현 품질, 명령어 사용 및 테스트 결과 |
| 제한된 구현 또는 시각적 검사를 저렴하게 처리 |
GLM-5.3 Flash |
실패율, 재시도 횟수 및 에스컬레이션을 포함한 비용 |
이 예시에서 보기 좋은 결제 버튼은 결과의 일부일 뿐입니다. 웹훅은 반드시 검증되어야 하며, 중복 이벤트가 중복 혜택을 부여해서는 안 되고, 구독 변경 사항은 올바른 계정에 업데이트되어야 합니다. 모델을 비교하기 전에 이러한 인수 테스트를 먼저 작성하십시오.
동일한 코딩 작업의 비용은 얼마일까요?
단순한 토큰 비용 비교를 위해, 한 번의 시도에 100,000개의 캐시되지 않은 입력 토큰과 20,000개의 과금 대상 출력 토큰이 사용된다고 가정합니다. 다음은 2026년 10월 29일 기준 GPT Proto에 표시된 가격 패널을 사용한 결과입니다. 요금은 100만 토큰당 USD 기준이며, 캐시나 비수기 할인 등은 고려하지 않았습니다. 중국 LLM 모델의 효율적인 선택을 위해 참고하시기 바랍니다.
계산식은 0.1 × 입력 요금 + 0.02 × 출력 요금입니다. DeepSeek 행은 표시된 GPT Proto 경로의 가격을 책정한 것이며, 해당 별칭으로 제공되는 체크포인트를 확정하는 것은 아닙니다.
이는 예시를 위한 토큰 비용입니다. 실제 출력에는 적용 가능한 경우 과금 대상 추론 비용이 포함되어야 하며, 전체 작업에는 더 많은 턴, 도구 결과, 재시도 또는 다른 모델이 포함될 수 있습니다. 예산을 계획할 때는 실시간 가격 패널을 확인하십시오.
총 API 비용을 인수 테스트를 통과한 변경 사항으로 나누어 측정하십시오. 이는 모든 모델이 동일한 토큰 수로 작업을 완료한다고 가정하는 것보다 훨씬 유용한 비교 방법입니다.
Why the Benchmark Winner May Not Be the Best Coding Agent
Your coding agent controls which files the model sees, how tools are called, when tests run, and what happens after failure. Changing that setup can change the result even when the model stays the same.
Before comparing candidates, hold the repository, task instructions, tools, acceptance tests, and time limit constant. Allow each model the request format it requires, and record its reasoning settings. Then measure completed tasks, regressions, retries, elapsed time, and API spend.
For this shortlist, use Kimi to test the capability ceiling, DeepSeek and GLM Flash to test production economics, Qwen for visual acceptance, and GLM for text-based repository execution. Let the results determine which stages share a model and which need a different route.
Which Chinese Coding Model Should You Use?
Choose Kimi K3.1 Pro first when completing a difficult feature or app is the priority and you can justify a higher per-token budget.
Choose DeepSeek V4.1 Flash when repeated agent calls make cost important. Confirm the deployed revision before basing a rollout on 1017-specific evidence.
Choose Qwen3.8-Max-0902 when the implementation must match screenshots, layouts, or other visual references.
Choose GLM-5.3 when your evaluation centers on source code, terminal output, and backend behavior.
Choose GLM-5.3 Flash when you want a low-rate visual-coding candidate and can detect failures before escalating them.
For an initial comparison, use one bounded task that already has a reliable acceptance test. A small verified change gives you more useful deployment evidence than a large generated application that nobody has checked.
하나의 API로 이러한 중국 LLM 모델을 호출하는 방법
사용해 보고 싶은 모델의 페이지를 연 다음, 모델 사용해 보기 → 빠른 시작을 이용하세요. GPT Proto API 키를 생성하거나 선택한 후, AI용 마크다운 복사를 사용하여 현재 통합 지침을 코딩 어시스턴트에 전달하세요.
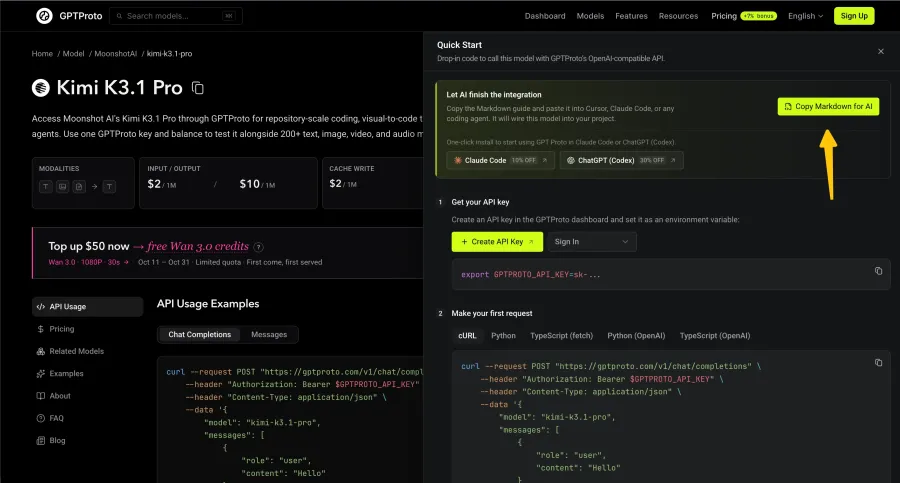
코딩 어시스턴트에게 프로젝트를 검토하도록 요청하고, 복사된 엔드포인트와 요청 필드를 따르며, 키는 서버 측 구성에 유지하고 간단한 연결 확인을 추가하세요. 실제 키는 공개 프롬프트나 저장소에 붙여넣지 말고 로컬 환경에서 구성하세요.
아래 모델 ID는 이번 업데이트에서 검토된 공개 GPT Proto 경로를 식별합니다:
| 모델 |
GPT Proto 모델 ID |
| Kimi K3.1 Pro |
kimi-k3.1-pro |
| DeepSeek Flash |
deepseek-flash |
| Qwen3.8-Max-0902 |
qwen3.8-max-0902 |
| GLM-5.3 |
glm-5.3 |
| GLM-5.3 Flash |
glm-5.3-flash |
각 경로에 대한 실시간 모델 페이지 가이드를 활용하세요. 모델마다 추론 필드, 도구 호출 처리, 멀티모달 요청 형식이 다를 수 있으므로, 모델 문자열을 변경하는 것은 마이그레이션의 일부일 뿐입니다. 성공적인 단일 요청 후에는 프로덕션 환경에서 사용하기 전에 다중 턴 도구 사용 테스트를 수행해야 합니다.
모델 API를 애플리케이션에 연결하는 것은 코딩 어시스턴트를 구동하는 모델을 변경하는 것과는 별개의 작업입니다. 후자의 경우 클라이언트가 지원하는 연결 형식을 확인하세요.
모든 GPT Proto 모델 비교 후 프로덕션 트래픽을 할당하세요. 하나의 API 키와 공유 잔액을 사용하면 각 공급자마다 별도의 통합 및 선불 계정을 유지할 필요 없이 지원되는 다양한 모델을 평가할 수 있습니다.
어려운 코딩 작업부터 시작하려면 Kimi K3.1 Pro를 열거나, 반복 호출 비용이 우선순위라면 DeepSeek Flash와 GLM-5.3 Flash를 비교해 보세요. 모델 페이지의 통합 가이드를 사용하고 작업량을 늘리기 전에 작은 변경 사항 하나를 먼저 검증하세요.