What Is an LLM API Provider?
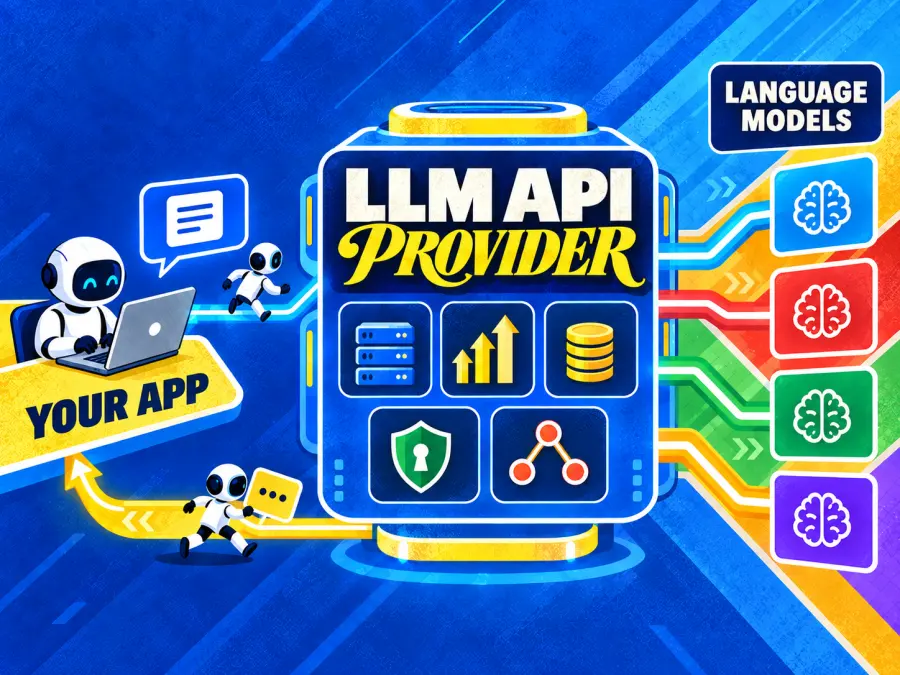
An LLM API provider gives developers hosted access to language models without requiring them to provision and operate the underlying inference infrastructure. The provider handles deployment, scaling, metering, authentication, and—depending on the platform—routing, observability, safety controls, or fine-tuning.
The label covers several different businesses:
First-party model APIs serve models built by the same company, such as a model lab exposing its own frontier models.
Multi-model API providers place models from several creators behind one account and often one API convention.
Routers and gateways send a request to one of several underlying hosts based on price, availability, latency, or user-defined rules.
Managed cloud AI platforms combine model access with enterprise identity, private networking, governance, and other cloud services.
Inference specialists optimize selected open-weight models for speed, cost, fine-tuning, or dedicated deployment.
These categories overlap. What matters is not simply, “Does this provider list the model?” but, “Can it deliver the model with the protocol, economics, reliability, and controls our application requires?”
How We Ranked the Best LLM API Providers
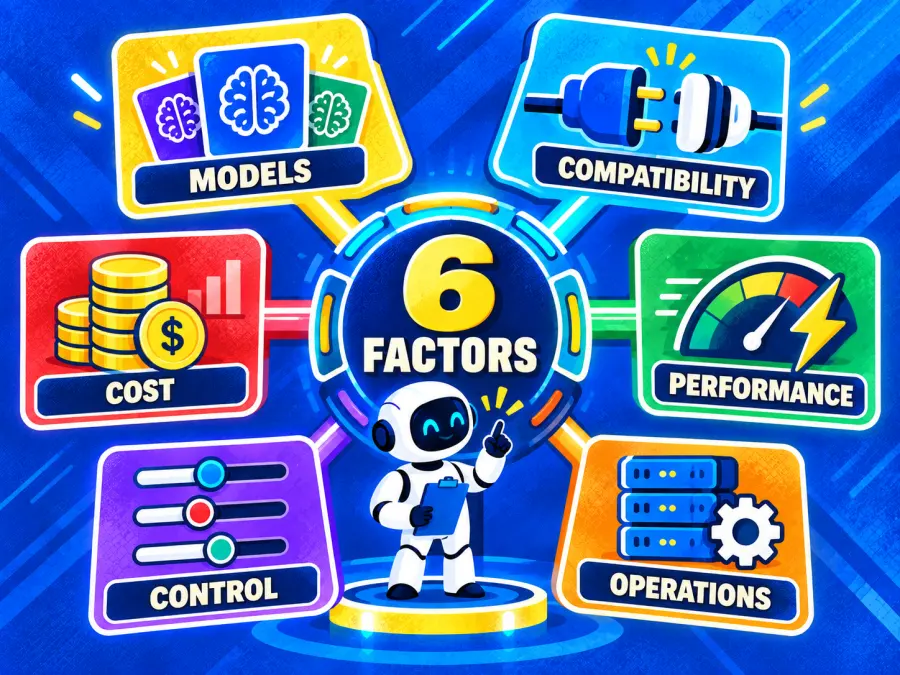
We reviewed each provider across six factor groups:
Model choice: the number and variety of useful models, not just raw catalog size
Compatibility: API consistency, tools, structured outputs, and streaming
Real cost: token rates, platform fees, caching, batch discounts, and retries
Performance: time to first token, throughput, tail latency, and capacity behavior
Control: provider pinning, fallback rules, error semantics, and model lifecycle
Operations: identity, regions, networking, governance, documentation, and migration effort
No provider wins every factor. Our order favors the best general-purpose platform for teams that value broad model access, then identifies the cases where a more specialized provider is the better decision.
LLM API Provider Comparison
| Rank |
Provider |
Best for |
Catalog profile |
API approach |
Main tradeoff |
| 1 |
GPT Proto |
One API key across LLM and multimodal models |
232 total models, including 124 text models at review time |
OpenAI-compatible chat endpoint for supported LLMs; task-specific APIs for other modalities |
Newer platform with a smaller enterprise ecosystem than hyperscalers |
| 2 |
OpenRouter |
Maximum LLM choice and cross-provider routing |
500+ models from 80+ providers |
OpenAI-compatible routed API with provider preferences and fallbacks |
Routing can complicate caching, performance consistency, and cost attribution |
| 3 |
Amazon Bedrock |
AWS governance and enterprise deployment |
100+ models through Bedrock Marketplace |
Consistent managed interfaces, including the Converse API |
AWS concepts, regional availability, and model-specific behavior add complexity |
| 4 |
Together AI |
Open-weight models, fine-tuning, and experimentation |
Broad open-model catalog |
OpenAI-compatible serverless API plus fine-tuning and dedicated options |
Feature support differs by model |
| 5 |
Fireworks AI |
Production open-model inference |
100+ available models |
OpenAI-compatible APIs with serverless and dedicated deployment |
Best fit is concentrated around open-model workloads |
| 6 |
GroqCloud |
Very fast generation on a focused catalog |
Smaller, curated model selection |
Mostly OpenAI-compatible API |
Narrower choice and documented compatibility gaps |
Catalog totals are directional, not directly comparable. One company may count model versions, modalities, providers, or fine-tunes differently from another. Availability also changes faster than a yearly list can capture.
1. GPT Proto — Best Overall Multi-Model LLM API Provider
GPT Proto ranks first for developers who want one account and API key that can grow beyond text generation. At review time, its catalog showed 232 models, including 124 text models, plus image, video, and audio options.
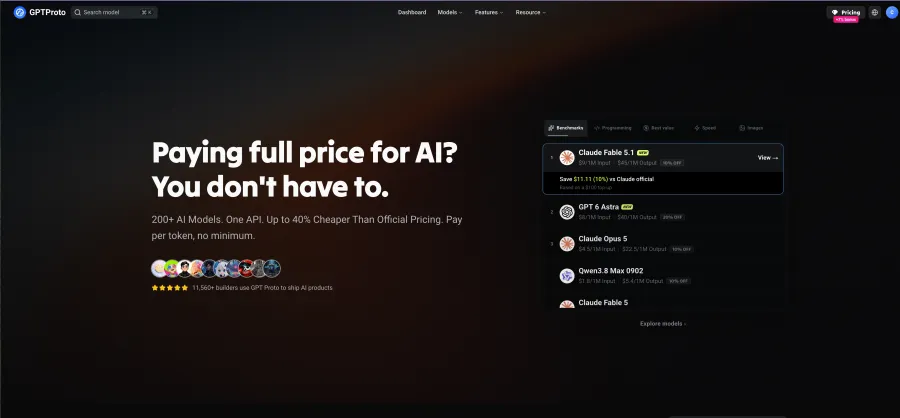
For supported LLMs, GPT Proto exposes an OpenAI-compatible chat-completions pattern. Developers can browse the text-model catalog, inspect model-specific rates, and test a model before integration.
Each model page exposes input and output rates. The GLM-5.3 API, for example, was listed at $1.26 per million input tokens and $3.96 per million output tokens when reviewed—10% below the displayed Z.ai direct rates. Prices can change, so check the model page.
GPT Proto is not the default winner for every enterprise: Bedrock has deeper AWS governance, OpenRouter a larger routed LLM catalog, and specialists may perform better for a specific open model. Its advantage is practical breadth across model families and modalities.
Best for: SaaS products, AI agencies, prototypes moving toward production, and multimodal applications.
Watch for: Treat OpenAI compatibility as model- and endpoint-specific. Image and video models use task-specific request bodies rather than the LLM chat format.
2. OpenRouter — Best for LLM Catalog Breadth and Routing
OpenRouter is the strongest choice when catalog breadth is the primary requirement. Its published offering exceeds 500 models across more than 80 providers. A single endpoint can route requests among underlying hosts, and developers can set provider preferences, allow fallbacks, or use automatic selection.
The tradeoff is that routing becomes part of application behavior. The same model name may run on a different host, hardware stack, or model variant. That can change latency, supported context, error handling, and prompt-cache economics. OpenRouter also lists a 5.5% fee on credit purchases for its standard pay-as-you-go plan, which should be included in total-cost calculations.
In recent developer discussions, users reported lower cache-hit consistency when traffic moved among providers. A separate community analysis examined thousands of turns. These reports are anecdotal, but teams with repeated long prompts should test pinned-provider and fallback-disabled configurations against default routing.
Best for: model discovery, broad LLM access, fallback routing, and applications that can benefit from provider choice at request time.
Watch for: platform fees, provider-level differences, cache misses, and the tension between automatic fallback and deterministic performance.
3. Amazon Bedrock — Best for AWS-Centered Enterprises
Amazon Bedrock is the most compelling option here for organizations already operating inside AWS. Bedrock Marketplace advertises access to more than 100 models, while services such as Agents, Knowledge Bases, and Guardrails connect model inference to a larger managed stack.
Its central value is governance rather than raw model count. AWS customers can align model access with familiar identity, logging, regional, networking, procurement, and security patterns. The Converse API gives supported models a more consistent message-based interface, reducing some integration differences across vendors. AWS also states that content sent through this API is not stored, a significant consideration for enterprise review.
Consistency does not mean every model behaves identically. Availability varies by region, capability support differs, and AWS account or service-limit concepts add work. Those costs make less sense for a small team that only needs a key and chat endpoint.
Best for: regulated workloads, established AWS teams, and companies that want model access inside an existing cloud-governance boundary.
Watch for: region-specific availability, model-specific features, service quotas, and cloud architecture overhead.
4. Together AI — Best for Open-Weight Experimentation and Fine-Tuning
Together AI is a strong LLM model API provider for teams working primarily with open-weight models. Its serverless service uses per-token pricing without provisioning replicas or committing to a minimum deployment cost. The platform also supports fine-tuning and dedicated endpoints, giving teams a path from quick evaluation to a more controlled deployment.
The OpenAI-compatible interface lowers migration effort for standard chat workloads. Together also publishes capability indicators for features such as function calling and structured outputs. Those indicators matter because feature support is not uniform across the catalog; a model that is excellent for plain generation may not satisfy an agent workflow that depends on strict JSON or reliable tool calls.
Together offers more depth than a pure router for teams that want to fine-tune an open model, test it through a hosted endpoint, and later choose dedicated serving. Teams still need to select the right model, serving mode, and feature set.
Best for: open-model research, fine-tuning, evaluation, and teams that may graduate from serverless to dedicated inference.
Watch for: per-model support for tools, structured output, context, and serving modes.
5. Fireworks AI — Best for Production Open-Model Deployment
Fireworks AI focuses on serving open models for production use. It lists more than 100 available models and offers both serverless access and dedicated deployments. Its API surface includes OpenAI-compatible Chat Completions and Responses-style interfaces, which can reduce the code changes needed for common LLM applications.
The platform is especially relevant when a team wants to begin with per-token serverless inference and later move a stable workload onto more isolated capacity. Batch inference is priced at 50% of serverless rates for workloads that can wait, creating a clear optimization path for offline enrichment, classification, summarization, and data-processing jobs.
Independent inference benchmarks also show why no provider should be assigned a permanent “speed” label. Performance varies by model, region, load, and measurement method. Test the exact provider-model pair with realistic prompts rather than transferring a result from one model to the whole platform.
Best for: production open-model inference, workloads that may need dedicated capacity, and delay-tolerant batch jobs.
Watch for: model-by-model performance variation and whether serverless, batch, or dedicated deployment matches the workload.
6. GroqCloud — Best for Low-Latency Text Generation
GroqCloud is the specialist in this list. Its focused catalog runs on Groq’s inference architecture, and public measurements have repeatedly placed supported models among the fastest for token generation. That makes it attractive for interactive agents, voice pipelines, coding tools, and other experiences where users feel every pause.
Groq describes its API as mostly OpenAI compatible, and the qualifier matters. Its documentation identifies unsupported fields, including logprobs, logit_bias, top_logprobs, and messages[].name; n must be set to 1. Flex processing allows much higher rate limits but can return a 498 capacity_exceeded response when capacity is unavailable. Preview models may also be discontinued on short notice.
Choose GroqCloud when a supported model fits the task and latency has measurable product value. Do not choose it solely because a framework already has an OpenAI adapter.
Best for: real-time assistants, agent loops, voice applications, and latency-sensitive generation on supported models.
Watch for: smaller model selection, unsupported request fields, capacity behavior, and preview-model lifecycle risk.
Why the Same LLM Can Behave Differently Across Providers
A 2026 measurement study, “When Is the Same Model Not the Same Service?”, argues that a hosted model should be treated as a provider-specific service object. Its observed behavior includes the model variant, protocol, context capacity, price, latency, throughput, reliability, and task feasibility—not just the model name.
The distinction gives developers a better LLM API provider comparison framework:
Model identity and version
Two endpoints may display the same model family while serving different checkpoints, quantizations, precision levels, or update schedules. Ask whether the model identifier is version-pinned and what happens when an upstream model changes.
Compatibility beyond the base URL
“OpenAI compatible” often means the provider accepts a familiar chat-completions request. It does not guarantee support for every parameter, tool schema, streaming event, response field, or error code. Build a contract test for the features your application actually uses.
Routing and cache stability
Automatic routing can improve availability, but provider switching may reduce prompt-cache reuse. If repeated context dominates your input bill, test a fixed host against routed traffic. Compare effective cost per completed task, not the advertised price per million tokens.
Latency, throughput, and errors
Measure the entire distribution. P50 latency describes a typical call; P95 or P99 exposes slow tails. Track time to first token separately from generation speed. Record rate limits, timeouts, capacity errors, and retry success because a cheap endpoint that needs frequent retries may be expensive in both compute and user patience.
The same study gives a useful indication of the upside: in its measured cases, routing reduced the cost of one Qwen3-32B workload by 37.8%, while provider choice increased throughput for a DeepSeek-V3.2 workload by about 90%. Those results are workload-specific, but they show why the provider layer deserves its own evaluation.
Which LLM API Provider Should You Choose?
Use the ranking as a shortlist, then decide by workload:
Choose GPT Proto for broad text and media access under one key.
Choose OpenRouter for maximum LLM choice and provider routing.
Choose Amazon Bedrock for AWS governance and managed services.
Choose Together AI for open-model experimentation and fine-tuning.
Choose Fireworks AI for production open-model deployment.
Choose GroqCloud for latency-sensitive generation on supported models.
Keep a first-party API in the comparison when one proprietary model is a stable dependency. Otherwise, test at least two providers with cached conversations, tool calls, structured responses, peak concurrency, and failures—not only short demo prompts.
How to Access Multiple LLMs With One GPT Proto API Key
Start in GPT Proto’s text-model catalog, open a model page, and use the model’s Try This Model option to confirm output before integration. After creating an API key, send a standard chat-completions request:
export GPTPROTO_API_KEY="replace_with_your_key"

curl https://gptproto.com/v1/chat/completions \
  -H "Authorization: Bearer $GPTPROTO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "glm-5.3",
    "messages": [
      {
        "role": "user",
        "content": "Return a JSON comparison of two caching strategies."
      }
    ]
  }'
For another compatible LLM, change the model value to the identifier shown on its model page. Keep model selection in configuration rather than hard-coding it throughout the application, and validate feature support before switching. Image, video, and audio models use their task-specific endpoints and request bodies.
Final Verdict
The best LLM API provider is the one that turns the right model into a dependable service for your workload. Model quality sets the ceiling, but compatibility, cache behavior, latency, error handling, lifecycle policy, and total cost determine what users actually experience.
For broad day-to-day use, GPT Proto offers the most balanced starting point in this six-provider comparison: one key, a large text catalog, transparent model pages, and access to other generative media APIs. OpenRouter wins on routed LLM breadth; Amazon Bedrock on AWS enterprise controls; Together AI and Fireworks AI on different stages of the open-model lifecycle; and GroqCloud on speed-focused inference.
Shortlist the provider category that matches your operating needs, then benchmark the exact provider-model-task combination. In 2026, that service combination—not the logo or model name alone—is the unit worth choosing.