料金プラン+7% ボーナス

AI API for Roleplay Chat.Your Characters, Your Models.

Write the character card. Set the lore. Decide which parts of the conversation your app sends with each turn. Try different models through one OpenAI-compatible API, then choose the voice and cost that fit your story.

提供モデル
curl https://gptproto.com/v1/chat/completions \
  -H "Authorization: Bearer $GPTPROTO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "claude-opus-5",
    "messages": [
      { "role": "system", "content": "<roleplay rules + 2,818-token card>" },
      { "role": "user",   "content": "You can't just take whatever you want." }
    ],
    "max_tokens": 400,
    "stream": true
  }'
Get API key6,000 in · 400 out ≈ $0.036 per turn  ·  10% below list
Make a character. Hear what changes when you switch models.
Start with a character card, a scene and a first message. Ask a follow-up, then run the same conversation on another model. Keep the prompt and history fixed so you can judge the response, not a different setup.
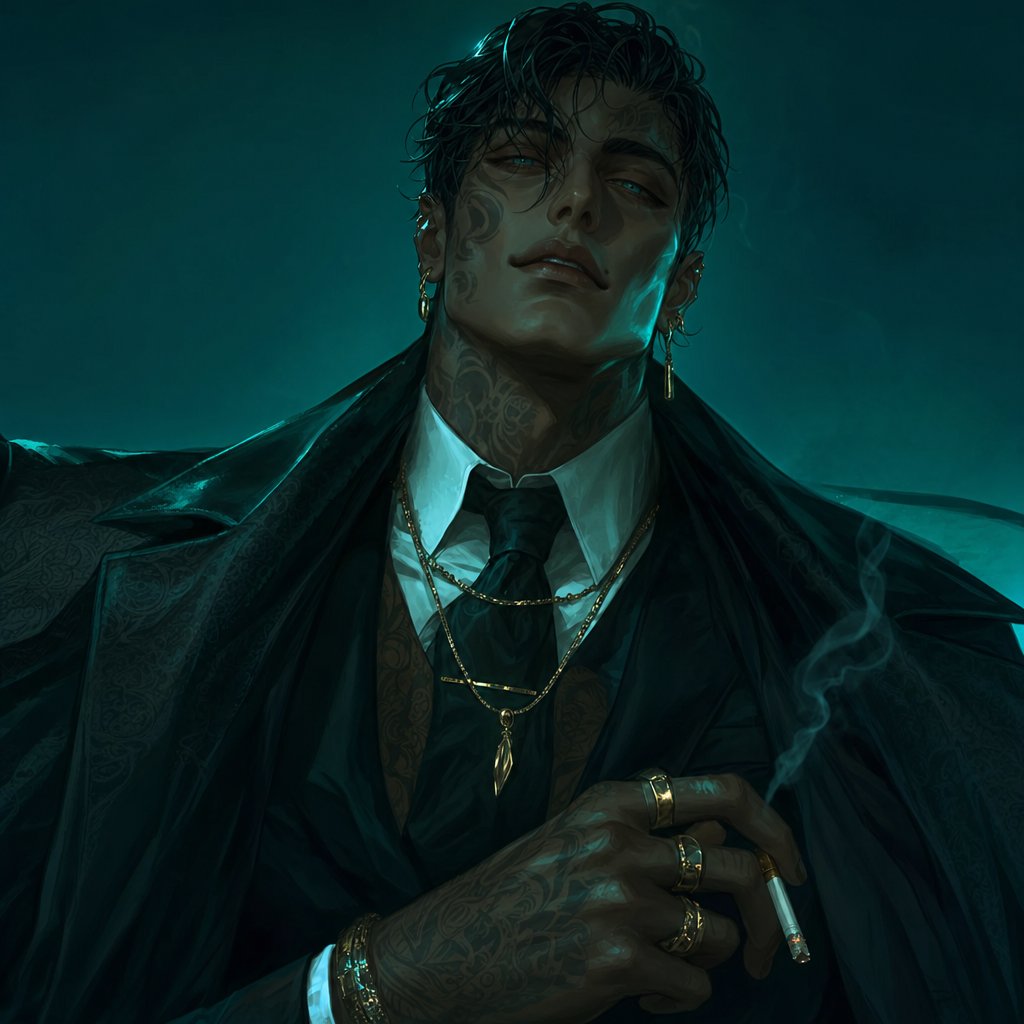
BaronOnline · talk to him yourself
⚡ トークンメーター·最終リクエスト 3,151 tok·今日 3,151 tok·× 1日 5,000 人料金計算へ
// 乗り換える理由

Long chats cost more.The story still needs to hold together.

As conversations grow, character details and chat history can make each turn more expensive. Your app also needs to keep the plot on track and choose a model that fits each character.

01

Token Burn Compounds Every Turn

A 2,818-token card plus 50 turns of history means every single reply carries thousands of input tokens. At list price, one engaged player can cost more per month than they pay you.

Price your own traffic
02

Characters Forget, Players Churn

Roleplay lives on memory. The card, the lorebook and a thousand turns of history need room to sit in the window — not a summarisation hack that quietly drops the plot.

See context windows
03

One Voice Doesn't Fit Every Character

A brooding rival, a lively sidekick and a narrator all want different models. Running three integrations to get three voices is how a two-person team ends up doing ops work.

See the lineup
Top up $100+ → wan-3.0, free & unlimitedSep 29 – Oct 10 · Limited quota · First come, first served
Top up now
// ROLEPLAY MODEL LINEUP

Find the right voice for each character.One key for all of them.

Start with the same card and scene. Switch models to hear the difference, then compare the input price, output price and context limit before you commit.

Long conversations with fictional characters — fixed personas and rich worldbuilding, where character consistency and memory continuity decide the experience.

Low-cost long contextキャラクターの一貫性Streaming
API キーを取得
モデル価格: GPTProto公式比OpenRouter比コンテキストモダリティ安定性操作
Claude Opus 5Claude
$4.50 / $22.50$0.45 キャッシュ読み込み · 1M トークンあたり−10%−15%1M→試す
GPT 5.6 SolOpenAI
$3.20 / $16.00$0.32 キャッシュ読み込み · 1M トークンあたり−20%−24%1.05M→試す
Kimi K3MoonshotAI
$2.70 / $13.50$0.27 キャッシュ読み込み · 1M トークンあたり−10%−15%1.05M→試す
GPT 5.6 TerraOpenAI
$1.60 / $9.60$0.16 キャッシュ読み込み · 1M トークンあたり−20%−24%1.05M→試す
GLM 5.2Z-AI
$1.26 / $3.96$0.23 キャッシュ読み込み · 1M トークンあたり−10%−15%1.05M→試す
DeepSeek v4 ProDeepSeek
$1.12 / $3.37$0.04 キャッシュ読み込み · 1M トークンあたり−15%−19%1.05M→試す
Top up $100+ → wan-3.0, free & unlimitedSep 29 – Oct 10 · Limited quota · First come, first served
Top up now
// 信頼性

Your Players Don't Pause for
Upstream Issues.

A failed reply is most noticeable when players are in the middle of a scene. Backup routes, automatic failover and continuous monitoring help your app handle upstream trouble during busy hours.

01

自動フェイルオーバー

Major models run on redundant upstream channels. If one degrades mid-evening, traffic shifts to a backup automatically — no code change, no dropped sessions.

02

冗長な上流チャネル

Major models are served through redundant upstream channels, so a single provider outage never ends your players' evening with it.

モデルを見る
03

24時間監視

Continuous monitoring with automatic traffic shifting — issues get routed around before they turn into a scene that ends mid-sentence.

// ROLEPLAY COST CALCULATOR

What does a long conversationactually cost?

Choose a model and describe a typical chat. See the cost per conversation and what it adds up to across your players.

テキスト · 100万トークンあたり
トークン / 月
$816
Claude と比べた年間の節約と OpenRouter(概算)
年月日
Claude$6,000$500.00$16.44
OpenRouter (est.)$6,330$527.50$17.34
GPTProto$5,400$450.00$14.79
モデル割引を見る
Top up $100+ → wan-3.0, free & unlimitedSep 29 – Oct 10 · Limited quota · First come, first served
Top up now
// USER FEEDBACK

What users say aboutGPTProto.

From switching models and handling fallback to creating images and video, people use GPTProto for different kinds of work. Here's what they chose to share.

BL
Blogstra
Reddit · r/Bloggers
#Routing

For a team already juggling DeepSeek, Kimi, Qwen, or other providers, a shared routing layer can be reasonable if it removes duplicated work and the fallback behavior is tested. GPTProto is one implementation of this approach.

K
K
X (Twitter) · @ChillaiKalan__
#Cost

I've been testing GPTProto recently, and it's honestly made my creative workflow much simpler. Instead of paying for multiple subscriptions, I can access several leading AI models from one place.

SN
Sanskriti Naruka
X (Twitter) · @snskritinaruka
#Video

I turned this single prompt into a cinematic fantasy video using GPTProto. "Continuous 15-second cinematic shot, 4K resolution, hyper-realistic dark fantasy photorealism…"

CF
Caden Flux
X (Twitter) · @Caden_Flux
#Video

I challenged myself to create a cinematic AI cooking short in just 15 seconds. I used GPTProto to bring the entire workflow together, from image generation to video, all in one place.

Z
Zara
X (Twitter) · @ZaraIrahh
#Creative

Made with Seedance 2.0 + GPT Image 2 on GPTProto. A Pixar-style commercial with the perfect glow.

MO
Many-Operation2625
Reddit · r/LLMDevs
#Integration

What worked for me was pointing the cloud connections at GPTProto so the frontend only sees one endpoint and I just change the model name to swap. I am not rebuilding a connection from scratch every time.

// 料金

Choose the model.
Pay for the tokens in each conversation.

Use one GPTProto balance to test models and run your character chat app. Input and output tokens are priced by model; check the current rate before you scale.

$10
等額入金 · ボーナスなし

Get started. Great for testing the endpoint and trying new models. Top up $20+ anytime to unlock bonus credits.

最大のお得 · +6%
$1,000
+6% ボーナスクレジット

You get $600 in balance for $500 — bonus credits stack on top of already-discounted model pricing. Built for teams running production workloads.

GPT 5.6 Sol で月 1 億トークンを使うと、GPTProto の料金では公式より年間およそ $960 安くなります(ボーナスクレジット適用前)
// よくある質問

Before you build acharacter chat app

Answers to the questions behind the demo: control, models, memory and cost.

01Can I use my own character cards, lore and dialogue rules?+

Yes. Your app can include character details, world information and examples in the messages it sends to the model. You decide how to structure that context and which parts to include on each turn, within the selected model's limits and policies.

02Does GPTProto store a character's memory between conversations?+

Your app manages persistent character data and conversation history. For each request, send the details the model needs, or retrieve and summarize earlier events in your own application. A larger context window gives you more room in a request; it is not long-term memory by itself.

03Can I try several roleplay models with one API key?+

Yes, you can select from the models currently available in the GPTProto catalog using the same API integration. Change the model ID and compare the same character and scene. Check each model page for its current price, context limit and supported features.

04How do I decide which model is best for my character chat?+

Run the same character card and conversation on a short list of models. Compare whether each reply stays in character, uses the right plot details, follows your rules, arrives quickly enough and fits your cost per turn. Test with your own scenes rather than relying on a generic rank.

05What makes long roleplay chats expensive?+

Input tokens can grow when your app sends a character card, lore and prior dialogue with every turn. Output tokens have a separate price. The calculator lets you estimate both; any cache savings depend on the selected model and an eligible request pattern.

06Will older messages be kept when a chat gets long?+

That depends on what your app sends and the selected model's context limit. Your app can keep recent dialogue, retrieve relevant earlier events or summarize older turns before sending a request. The API cannot guarantee that an unlimited history will fit unchanged.

07Can I use streaming for a chat interface?+

Streaming can deliver a response progressively where the selected model and endpoint support it. Confirm the model's supported features and implement interruption and retry handling in your app.

08How do I switch an existing character chat integration?+

If your client uses the supported OpenAI-compatible request format, start by testing the GPTProto base URL, API key and a model ID in staging. Verify your use of streaming, tools and error handling for the models you plan to deploy.

09Are all kinds of roleplay content allowed?+

Content rules can vary by model and provider. Review the current model-specific restrictions and GPTProto terms before choosing a model for your application. Do not assume that "fully custom" overrides those rules.

10How are conversation data and billing handled?+

See the current GPTProto data handling, privacy and billing documentation for retention, logging, invoicing and regional terms. Do not infer these from the API interface alone.

// 始める

Make every character your own.Find the right model for less.

ブラウザで画像や動画を作るか、一つの API キーでテキスト、画像、動画のモデルをアプリに組み込めます。対象モデルの割引も確認できます。

  • ✓OpenAI 互換
  • ✓200以上のモデル
  • ✓公式より 10–30% 安い
  • ✓高い稼働率、自動フェイルオーバー
✓クリップボードにコピーしました