A character can answer your opening message convincingly, then spend the rest of the conversation repeating itself, resolving every disagreement, or forgetting what happened earlier. Fewer refusals would solve only part of that problem.
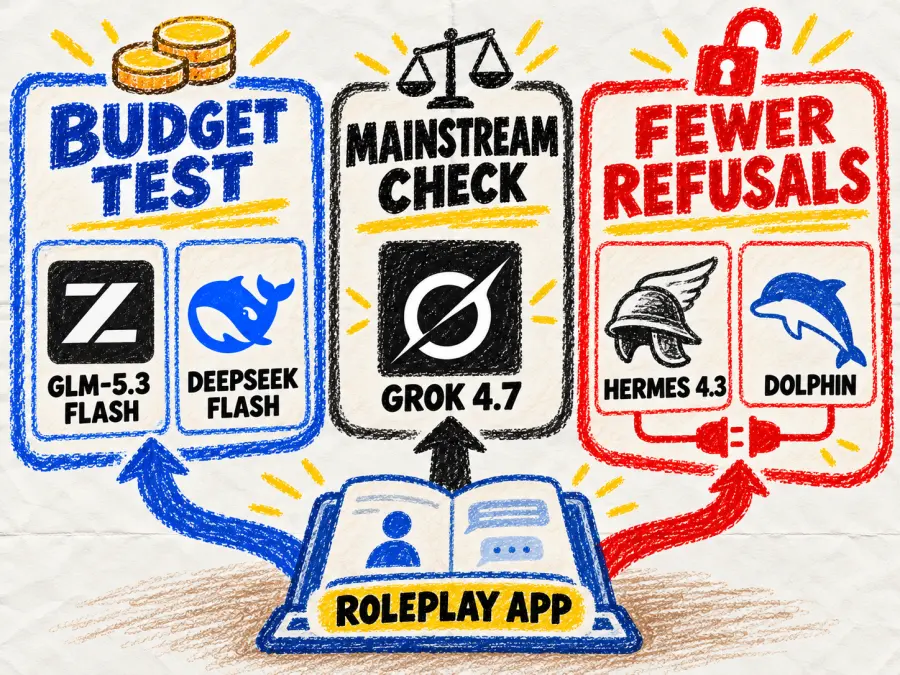
For a roleplay or AI chat app, my starting shortlist is GLM-5.3 Flash and DeepSeek Flash for budget evaluation, with Grok 4.7 as another mainstream option to compare. If reducing refusals is your overriding requirement, investigate purpose-built models such as Hermes 4.3 or Dolphin and the conditions of the endpoint serving them.
The best uncensored LLM API for your app has to satisfy both requirements: it must handle the creative material you intend to support and deliver conversations people want to continue.
Research checked October 15, 2026. This shortlist uses official documentation, published model information, and attributed community experiences. It is a source-based selection guide; no live, cross-model roleplay benchmark was performed for this article.
Best Uncensored LLM API Options at a Glance
“Uncensored” is an imprecise label. A model trained to reduce refusals, a general model that accepts your particular scene, and a host with permissive terms are different things. Check all three before building a feature around that label.
| Model |
Why consider it? |
Main trade-off |
Access covered here |
| Grok 4.7 |
A mainstream model to evaluate alongside your current chat backend |
Published capabilities do not establish a zero-refusal guarantee |
GPT Proto model page and request example available |
| GLM-5.3 Flash |
Budget dialogue candidate with positive character-writing anecdotes |
Thinking cannot be disabled through the documented official control |
GPT Proto model page and request example available |
| DeepSeek Flash |
Budget candidate with an officially supported non-thinking mode |
Older Flash names can resolve to a newer underlying model |
GPT Proto model page and request example available |
| Hermes 4.3 36B |
Explicit reduced-refusal positioning with author-published evaluation results |
Hosted behavior and charges depend on the serving endpoint |
Open weights; GPT Proto availability not confirmed |
| Dolphin 3.0 Mistral 24B |
Model-owner control over the system prompt and behavioral rules |
Its model card does not supply a completed evaluation suite |
Open weights; GPT Proto availability not confirmed |
For the supported hosted options, compare models for your roleplay app using the same character and scene. Keep those inputs fixed so you can hear what changes when the model changes.
Three Hosted LLM APIs to Compare for Roleplay and Chat Apps
These are candidates to evaluate by workload. Their order does not represent measured refusal rates.
Grok 4.7 — A Mainstream Option to Evaluate
Grok’s developer documentation lists a 500,000-token context window, text and image input, and configurable reasoning. Those capabilities make it a practical comparison candidate when your application combines character conversation with visual references or substantial background material.
They do not establish how well it remembers a particular fictional relationship or whether it will accept every scene. Its behavior also remains subject to the published acceptable-use policy.
I would include Grok when evaluating a mainstream hosted option against budget models, then judge the actual dialogue: does the character retain its voice, allow disagreement, and respond to the user's last action without taking over their role?
On GPT Proto’s Grok 4.7 page, the documented model string is grok-4.7. The published rates checked for this guide are $1.20 per million input tokens and $3.60 per million output tokens.
My take: Include it in the comparison if you can justify the higher token cost. A convincing sample should earn that budget; the model name alone should not.
GLM-5.3 Flash — Budget Dialogue With a Thinking Trade-Off
GLM-5.3 Flash is worth evaluating when character dialogue matters and your application needs inexpensive repeated calls.
In a SillyTavern discussion comparing GLM Flash with DeepSeek Flash, one participant preferred GLM's adherence to character speech patterns while describing DeepSeek as better at advancing the plot. Other participants disagreed about long-session consistency. These are individual experiences, without a shared testing setup.
The more concrete limitation comes from Z.ai’s official documentation: thinking.type only supports enabled. You cannot assume that adding a “disable thinking” setting will produce a faster chat response.
That matters because a roleplay app needs the next readable line, not merely evidence that generation has started. A separate user report about GLM’s thinking delays describes liking its writing while finding the wait disruptive. The report concerns another API environment, so it does not establish GPT Proto latency.
The GLM-5.3 Flash API page documents glm-5.3-flash. Check its current pricing before forecasting spend.
My take: A useful budget dialogue candidate, provided its time to the first readable reply fits your app. Test that directly.
DeepSeek Flash — A Low-Cost Option With Non-Thinking Mode
DeepSeek Flash is the other budget option I would put into the same comparison.
The official documentation identifies the current route as DeepSeek-V4.1-Flash and supports both thinking and non-thinking operation. A non-thinking option gives you a configuration to evaluate for short conversational turns; it is not a promise of a particular response time.
Version identity deserves attention. DeepSeek’s current model details say that the legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp remain accepted, but their requests are now served by V4.1 Flash. An older review may describe a different model from the one a familiar identifier reaches today.
On GPT Proto’s DeepSeek Flash page, the documented string is deepseek-flash, with published rates of $0.24 per million input tokens and $0.96 per million output tokens.
My take: Start here when a low-cost baseline and the ability to evaluate non-thinking operation matter. Confirm which controls the selected endpoint exposes before comparing configurations.
When Should You Choose Hermes or Dolphin Instead?
If reduced refusal behavior is central to your product, an explicitly documented model design is more useful than a generic “unfiltered” marketing label.
Hermes 4.3: Published Reduced-Refusal Evidence
The Hermes 4.3 model card emphasizes reduced refusals and reports RefusalBench answer rates of 74.60% in non-reasoning mode and 72.29% in reasoning mode.
Those are the model author's results on that evaluation. They are not independent measurements of every hosted endpoint, and they do not tell you whether users will enjoy a character conversation.
I would investigate Hermes when explicit reduced-refusal training is a requirement. Verify the exact checkpoint, available serving route, and workload terms before treating its published score as relevant to your deployment.
Dolphin: Control Over the Model’s Instructions
The Dolphin 3.0 Mistral 24B model card emphasizes the operator's control over system instructions and behavioral rules. It describes ways to deploy the model, while its evaluation section remains marked “TBD.”
That makes Dolphin a customization candidate, rather than an evidence-backed winner for writing quality.
Neither model is confirmed in GPT Proto's public inventory for this guide. Open weights also do not come with a universal API price: self-hosting requires infrastructure, while hosted access inherits the endpoint's charges and conditions. Compare those costs against the control you actually need.
What Does a Long Roleplay Conversation Actually Cost?
A per-million-token price is only the beginning. With a stateless chat-completions request, your application supplies the history it wants the model to use. Repeatedly sending a growing transcript increases input volume.
The following is an illustrative estimate, using these fixed assumptions:
Character card and system rules: 1,500 tokens.
Each new user message: 100 tokens.
Each assistant reply: 250 tokens.
Conversation length: 30 turns, with one user message and one reply per turn.
Every request includes the full preceding conversation.
The first request contains 1,600 input tokens. Each subsequent request adds the previous 350-token exchange. Across the conversation, that totals 200,250 input tokens and 7,500 output tokens.
| Model |
Input / output price per 1M tokens |
Estimated base cost for the conversation |
| Grok 4.7 |
$1.20 / $3.60 |
$0.267 |
| DeepSeek Flash |
$0.24 / $0.96 |
$0.055 |
| GLM-5.3 Flash |
Check current model pricing |
Excluded pending rate confirmation |
The estimates exclude cache discounts, additional reasoning tokens, message-format overhead, retries, and time-dependent promotions. They are not observed bills. GLM's checked page contained inconsistent discount and promotional text, so I have left it out of the worked calculation.
Cache hits can reduce the cost of repeated inputs. Summaries can reduce the history sent, but may drop details the character needs. Longer replies and extra reasoning can add costs beyond the visible dialogue.
To estimate your roleplay API costs, begin with the actual amount of history your app sends. Multiplying the price by only the newest message will miss much of the bill.
How to Compare Models With the Same Character and Conversation
Use a fictional scene whose constraints are easy to inspect. For example, a ship captain promised to protect a passenger's identity, distrusts the crew's navigator, and must negotiate a route change without revealing the secret.
Keep the character card and user turns identical across models. Include a disagreement, a callback to an earlier detail, and a request that should leave the user's next action undecided.
| Check |
What to inspect |
| Character consistency |
Does the captain retain the established voice, motives, and relationships? |
| User control |
Does the model invent the user's dialogue or actions? |
| Story continuity |
Does it preserve earlier events without repeating whole passages? |
| Creative-request handling |
Does it answer the intended fictional task, refuse it, or silently change it? |
| Interaction cost |
How long until readable dialogue appears, and what usage is billed? |
A successful harmless scene does not prove broad uncensored behavior. Evaluate representative requests from the creative use cases your product supports, and record which ones were actually tested.
Send the Character and History Through the API
Set GPTPROTO_API_KEY in your server environment first. The following cURL request follows the published DeepSeek Flash request format. The short history is an illustrative fixture, not a claimed model output.
curl --fail-with-body --request POST \
  "https://gptproto.com/v1/chat/completions" \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "model": "deepseek-flash",
    "messages": [
      {
        "role": "system",
        "content": "You are Captain Mara in a fictional adventure. You promised to protect the identity of passenger Irena and distrust navigator Vale. Keep these facts consistent. Write only dialogue and observable actions for Mara. Leave the user in control of their character. Keep the reply concise."
      },
      {
        "role": "user",
        "content": "I ask you to change course before the navigator returns."
      },
      {
        "role": "assistant",
        "content": "Mara folds the chart. Tell me why, and keep your voice down."
      },
      {
        "role": "user",
        "content": "Vale enters and asks who is hiding below deck. What do you say?"
      }
    ]
  }'
This is a documentation-based example, not a live-tested request. It leaves reasoning at the endpoint default. For a controlled comparison, verify supported settings, retain the returned usage information, and save actual assistant replies in your application history.
For a web app, keep the API key on your backend. The browser sends user messages to your server, which assembles the character instructions and relevant history before calling the model.
SillyTavern’s context documentation explains an important distinction: messages outside the sent context are unavailable to the model. Check the outgoing request before blaming “bad memory.” For a longer setup walkthrough, see how to create your own AI character with an API.
Which Option Fits Your App?
My recommendation is to choose a small comparison set around the behavior your product needs.
| Your priority |
Where I would start |
| Explicit reduced-refusal model design |
Investigate Hermes or Dolphin and verify the serving conditions |
| Budget character dialogue |
Compare GLM-5.3 Flash and DeepSeek Flash on the same scenes |
| Testing non-thinking operation |
DeepSeek Flash, after checking endpoint controls |
| Evaluating another mainstream hosted model |
Add Grok 4.7 and compare its dialogue against its higher token cost |
For an existing app, replay representative conversations before changing the default model. Record the exact version, endpoint, settings, and date alongside your observations.
Then use the GPT Proto roleplay model comparison to evaluate supported options with one account. The winning choice is the one whose creative behavior, conversation quality, and bill fit the application you are building.