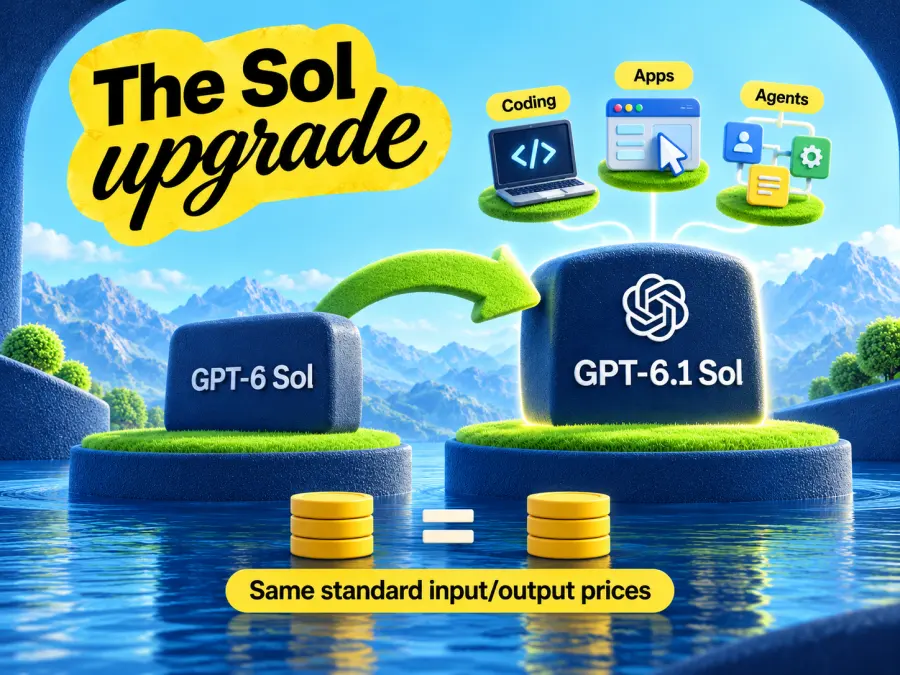
GPT-6.1 Sol is OpenAI's upgraded Sol model for coding, computer use, and professional agent work. Released on September 29, 2026, it brings several results closer to GPT-6 Astra while keeping Sol's standard input and output prices. The practical question is whether that improvement justifies changing your existing agent.
GPTProto is rolling out GPT-6.1 Sol API access at 20% off official pricing. Visit the model page for current access, prices, and Quick Start.
Last checked: September 30, 2026. This guide separates published specifications, benchmark results, and our recommendations. It does not report a private head-to-head test.
What Is GPT-6.1 Sol?
OpenAI introduced GPT-6.1 Sol at DevDay 2026, one week after GPT-6 Sol. Its API model ID is gpt-6.1-sol.
In OpenAI's model-selection guidance, Astra remains the highest-intelligence tier, while Sol balances capability and cost. Think of 6.1 Sol as an upgrade within that role. A newer version number does not establish a win on every task.
| Specification |
GPT-6.1 Sol |
| Context window |
1,050,000 tokens |
| Maximum output |
128,000 tokens |
| Native input |
Text and images |
| Native output |
Text |
| Default reasoning effort |
medium |
The official model specification documents these limits. Native audio and video are unsupported; access to an image-generation tool is a separate capability. Our GPT-6 Sol overview covers the predecessor.
What Changed from GPT-6 Sol?
The important changes involve quality, caching, and API compatibility. Context capacity and standard input/output prices stay the same.
| Area |
GPT-6 Sol |
GPT-6.1 Sol |
| Standard input / output per million tokens |
$2 / $10 |
$2 / $10 |
| Cached input per million tokens |
$0.20 |
$0.10 |
| Context / maximum output |
1.05M / 128K |
1.05M / 128K |
Reasoning effort none |
Supported |
Unsupported |
| Tool calling through Chat Completions |
Only with none |
Unsupported |
| Tool calling through Responses |
Supported |
Supported |
The old Sol documentation and GPT-6 migration guide explain the compatibility difference. GPT-6.1 Sol accepts low, medium, high, xhigh, and max; it accepts neither none nor minimal.
This matters if your agent currently sends tools through Chat Completions with reasoning_effort: "none". Changing only the model name will leave it with an unsupported combination. Move the tool workflow to a verified Responses route and choose a supported effort.
GPT-6.1 Sol Pricing: What Will You Actually Pay?
These are OpenAI's published Standard rates, in US dollars per million tokens.
| Token category |
GPT-6.1 Sol |
GPT-6 Sol |
GPT-6 Astra |
| Uncached input |
$2.00 |
$2.00 |
$10.00 |
| Cached input reads |
$0.10 |
$0.20 |
$1.00 |
| Cache writes |
$2.50 |
$2.50 |
$12.50 |
| Output |
$10.00 |
$10.00 |
$50.00 |
On GPT Proto's GPT-6.1 Sol model page, the 20% discount brings standard input to $1.60 per million tokens and output to $8.00 per million tokens. Check its live pricing panel for cache billing, long-context rates, and any processing options you select.
The official pricing documentation distinguishes cache reads from writes. A cache hit can reduce the input bill; writing reusable context has its own rate. An unchanged input/output price also means that output-heavy workloads do not automatically become cheaper.
OpenAI's long-context pricing adds another boundary: requests exceeding 272,000 input tokens receive twice the input and cache rates and 1.5 times the output rate for the entire request. That is a pricing threshold inside the larger context window.
For a hypothetical uncached request with 300,000 input tokens and 10,000 output tokens, the OpenAI Standard token cost is:
0.30 × $4 + 0.01 × $15 = $1.35
Using the shorter-context rates would produce $0.70 and understate the bill. This calculation excludes tools, retries, cache writes, and other processing options; it is an illustration, not a measured task cost.
How Good Is GPT-6.1 Sol at Coding and Agent Tasks?
OpenAI's launch evaluation reports improvements across different kinds of agent work:
| Evaluation |
Reported improvement over GPT-6 Sol |
Reading the result |
| DeepSWE 1.1 |
6.4 percentage points above old Sol's best score |
Achieved at lower effort and cost; this is not a same-effort comparison |
| AutomationBench |
4.8 percentage points at medium effort |
Business workflow completion |
| OSWorld 2.0 offline |
7 percentage points at maximum effort |
Partial reward on the v2026.08.08 computer-use set |
These are vendor-reported results from OpenAI's evaluation environment. Repository coding, business tools, and desktop interaction test different abilities. None provides a guaranteed success rate for your agent.
Artificial Analysis's independent evaluation supports the broader improvement: its Intelligence Index rises four points over old Sol and sits one point below Astra. At maximum effort, its Coding Agent Index rises three points over old Sol and remains two below Astra.
Its Intelligence Index cost per task is $0.72 for 6.1 Sol, $1.05 for old Sol, and $3.26 for Astra at maximum effort. Those figures belong to that benchmark suite. They do not predict the cost of a pull request. Artificial Analysis also reports roughly 10–30% more output tokens than old Sol across effort levels.
Early community observations are narrower. In his September 29 notes, Simon Willison considered his GPT-6.1 Sol SVG pelicans visually similar to earlier GPT-6 outputs. That illustrates how an upgrade may barely change a familiar prompt, though this drawing exercise says little about repository engineering.
GPT-6.1 Sol vs GPT-6 Astra: Should You Switch?
We would start a comparison with Sol for repeated code reviews, scoped repository changes, document work, and business agents where operating cost matters. Its published results justify testing it as a cheaper candidate for work you currently send to Astra.
Keep Astra in the comparison for the hardest research and tasks where a failed result requires expensive human repair. OpenAI's launch evaluation still places Astra highest on Terminal-Bench Science. “Near-Astra” describes selected results rather than universal equivalence.
The decision metric we recommend is cost per accepted result: total model and tool spending, including retries and escalation, divided by outputs that pass your acceptance criteria. A cheaper attempt can become an expensive completed task. Keep GPT-6 Astra as a fallback until the replacement proves itself on your workload.
Where Can You Use GPT-6.1 Sol?
Access depends on the product, account, and integration. OpenAI's rollout notes cover Codex and ChatGPT Work availability.
| Surface |
Status checked September 30, 2026 |
| OpenAI API |
Documented as gpt-6.1-sol |
| Codex |
Available to eligible accounts; check workspace access |
| ChatGPT Work |
Included in the announced rollout |
| Ordinary ChatGPT Chat |
Not available at launch |
| Claude Code |
No official support for routing to non-Claude models |
| GPT Proto |
Model page rolling out; API pricing is 20% below official rates |
Is GPT-6.1 Sol Available in Codex?
Yes. OpenAI announced access for Plus, Pro, Business, Enterprise, and Edu users in Codex and ChatGPT Work. The developer settings documentation shows codex --model gpt-6.1-sol. Your account and workspace must permit the selection; specifying an identifier does not grant access.
Can You Use GPT-6.1 Sol in Claude Code?
Anthropic's LLM gateway documentation says routing Claude Code to non-Claude models through a gateway is unsupported. Third-party adapters may attempt it, but their behavior needs separate validation. A working text response does not establish correct tool execution, streaming, or permission handling.
Use GPT-6.1 Sol Through GPT Proto
Open the GPT-6.1 Sol model page and select Try this model for Quick Start. During the rollout, use that panel to check access and the current request parameters. Create a GPT Proto key and replace the value below. This basic text request uses GPT Proto's OpenAI-compatible Chat Completions endpoint and the documented gpt-6.1-sol identifier:
export GPTPROTO_API_KEY="your_gptproto_api_key"

curl --fail-with-body --silent --show-error \
  --request POST "https://gptproto.com/v1/chat/completions" \
  --header "Authorization: Bearer ${GPTPROTO_API_KEY}" \
  --header "Content-Type: application/json" \
  --data '{
    "model": "gpt-6.1-sol",
    "messages": [
      {
        "role": "user",
        "content": "Review this Python function for correctness and edge cases: def average(values): return sum(values) / len(values)"
      }
    ]
  }'
The example contains no tools and follows GPT Proto's published Chat Completions request format. No authenticated live inference was performed for this guide.
For an agent that calls tools, follow the model page's Responses example and check the supported parameters. An account or rollout restriction can block a request before the model runs; inspect the returned API error before evaluating quality. Keep results from GPT-6 Sol as your upgrade baseline.
What Should You Check Before Upgrading an Agent?
Start with the request configuration. Confirm the model ID, choose a supported reasoning effort, and verify the endpoint handles your tools. A provider's general OpenAI compatibility does not prove every model/parameter combination is implemented.
Then replay representative tasks using the same repository revision, instructions, tools, and permissions. Include cases your current agent handles poorly. For coding, inspect the patch and run the repository's relevant checks; for business workflows, verify the final application state.
Record accepted results, elapsed time, cache hits, billed tokens, retries, and escalations. Compare both the effort level you normally use and a lower-cost setting. Introduce traffic gradually once quality and spending meet your targets, with a tested fallback for unsuccessful tasks.
GPT-6.1 Sol's main appeal is better task performance at familiar Sol token prices, with cheaper cache reads. Explore GPT-6.1 Sol on GPT Proto for 20% off API pricing and Quick Start, retain your baseline, and migrate when your own results support the change.