What Should a Venice API Alternative Actually Replace?
A useful comparison starts with Venice's real differentiators, not a generic feature checklist.
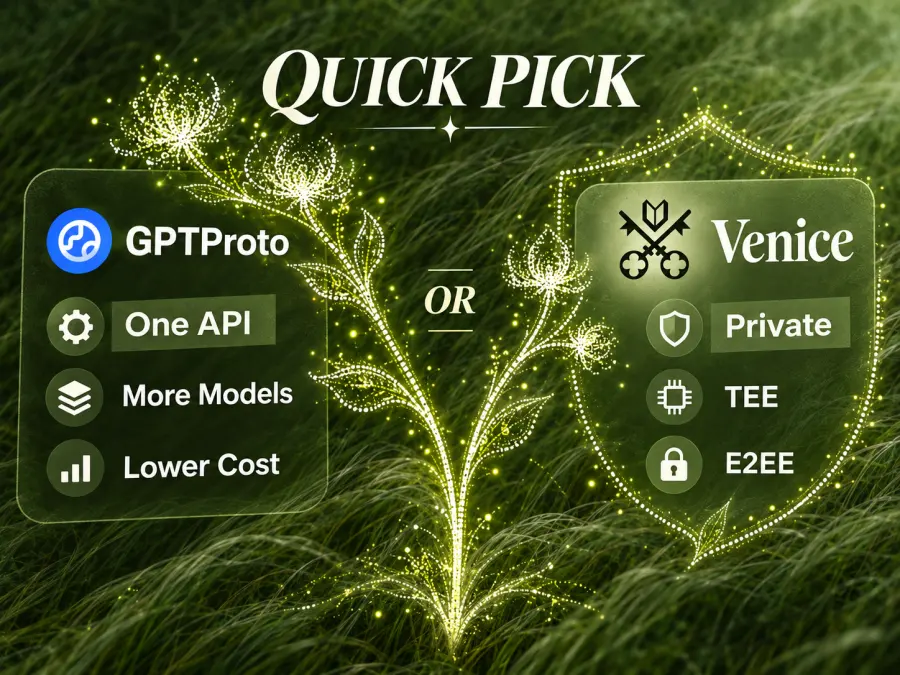
Venice exposes more than 350 text, image, video, and audio models through one key. Its API is broadly compatible with OpenAI clients, while four privacy modes—Anonymous, Private, trusted execution environment (TEE), and end-to-end encrypted (E2EE)—set it apart. It also supports prepaid credits, a daily DIEM allowance, and x402 USDC payments.
Those strengths have limits. TEE and E2EE currently support text only, and E2EE disables features that require plaintext, including web search, memory, summaries, and some tools. Venice may append its system prompt unless disabled, and model deprecation windows may be only 7 to 15 days.
I evaluated each Venice API competitor across six questions:
Coverage: Which text, image, video, and audio models are available?
Compatibility: Can an OpenAI client connect with a base URL and model-name change?
Privacy: Is protection contractual, technical, or provider-dependent?
Operations: How are queues, retries, cold starts, limits, and retirements handled?
Customization: Are fine-tuning, adapters, custom models, or self-hosting available?
Cost: What fees or infrastructure costs sit beyond the listed rate?
No alternative wins all six. The best choice depends on which Venice benefit is essential and which is merely convenient.
Best Venice API Alternatives: Quick Comparison
| Rank |
Alternative |
Best for |
Modalities |
OpenAI-compatible path |
Main tradeoff |
| 1 |
GPT Proto |
Affordable multimodal access |
Text, image, video, audio |
Yes |
Does not claim Venice-style TEE or E2EE privacy |
| 2 |
OpenRouter |
LLM routing and provider fallback |
Mainly text and vision |
Yes |
Privacy and availability vary by routed provider |
| 3 |
Together AI |
Open-weight models and fine-tuning |
Text, image, video, audio |
Yes, across several endpoints |
Less useful for broad closed-model access |
| 4 |
Fireworks AI |
Production open-model inference |
Primarily text and multimodal open models |
OpenAI- and Anthropic-style APIs |
More infrastructure-focused than catalog-focused |
| 5 |
fal |
Image and video applications |
Image, video, audio, 3D |
Not a drop-in chat API |
Model-specific schemas require workflow code |
| 6 |
Replicate |
Community and custom model experiments |
Text, image, video, audio |
No |
Cold starts and prediction-specific integration |
| 7 |
vLLM |
Self-hosted privacy and control |
Primarily language and embedding models |
Yes |
You own GPUs, security, scaling, and operations |
1. GPT Proto — Best Overall and Affordable Venice API Alternative
GPT Proto is the closest match for developers using Venice as a single gateway. It offers more than 200 text, image, video, and audio models. Its OpenAI-compatible base URL means many chat integrations need only a new key, URL, and model identifier.
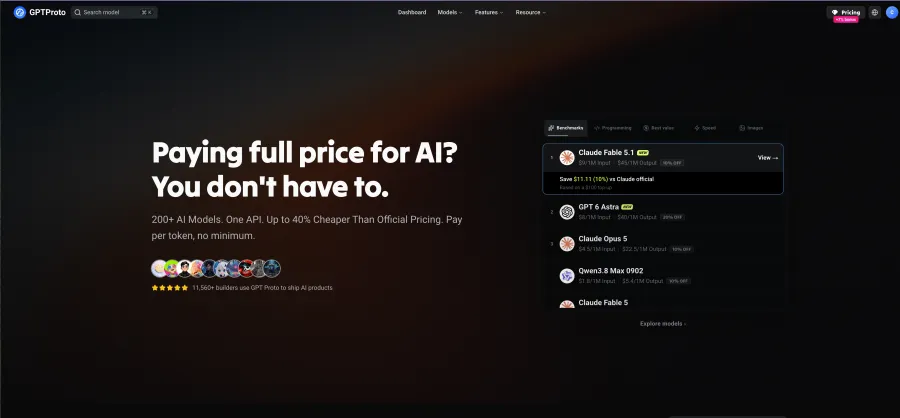
The catalog includes image and video options from Chinese model families, useful when comparing visual quality and price-performance beyond the usual US vendors.
GPT Proto discounts official model pricing and uses pay-as-you-go billing without a minimum. One current GLM-5.3 example:
| Platform |
Input per 1M tokens |
Output per 1M tokens |
| GPT Proto |
$1.26 |
$3.96 |
| Together AI |
$1.40 |
$4.40 |
| Venice API |
$1.75 |
$5.50 |
At 100 million input and 20 million output tokens, those rates imply $205.20 on GPT Proto, $228 on Together AI, and $285 on Venice. This is model-specific; recalculate for your own mix.
GPT Proto is not a privacy-equivalent replacement. It does not advertise Venice's four-mode design or text-only TEE and E2EE paths. If cryptographic separation is required, lower cost is not a substitute.
Best for: SaaS products, AI agents, internal tools, and multimodal applications that want broad model choice and predictable usage pricing.
Why it ranks first: It combines one key, many models, familiar requests, and strong economics.
Explore GPT Proto's model gateway if cost and multimodal coverage are your main selection criteria.
2. OpenRouter — Best for LLM Routing and Fallbacks
OpenRouter is a strong Venice API alternative when your main problem is resilient language-model routing. It can route requests across multiple providers, apply fallbacks, and let teams bring their own provider keys. Its OpenAI-compatible interface makes it approachable for applications already using the OpenAI SDK.
Routing is also the complication. Privacy, retention, regional processing, and availability differ by provider. Production teams should pin allowed routes and verify each provider's policy.
Credit purchases carry a 5.5% fee with an $0.80 minimum, so effective cost is not just the displayed inference rate.
It is less compelling for image or video products because it is primarily a language-model routing marketplace.
Best for: Teams that need cross-provider LLM access, automatic fallbacks, and routing controls.
Choose it over GPT Proto when: Provider selection and failover logic matter more than a broad media catalog or the lowest effective gateway cost.
3. Together AI — Best for Open Models and Fine-Tuning
Together AI suits teams building around open-weight models. It offers more than 100 serverless models and APIs for chat, vision, images, speech, embeddings, and other workloads, with OpenAI-style patterns across many endpoints.
Teams can fine-tune models, train LoRA adapters, and run them on the same platform. Batch inference can reduce eligible costs by up to 50% for offline evaluation, labeling, summarization, or backfills.
It is not a neutral gateway to every major closed model. Choose its customization depth when you plan to build on families such as Llama, Qwen, or DeepSeek.
Best for: Open-model products, fine-tuning programs, evaluation pipelines, and batch inference.
Watch for: Endpoint-level differences. “OpenAI compatible” still does not guarantee that every field, tool-call sequence, or streaming event behaves identically.
4. Fireworks AI — Best for Production Open-Model Inference
Fireworks AI serves more than 100 open models through serverless, on-demand dedicated, and reserved deployments. It supports function calling, structured outputs, fine-tuning, and LoRA customization.
A prototype can start on serverless inference, then move to dedicated capacity for stricter throughput or latency. OpenAI- and Anthropic-compatible interfaces reduce client changes for common requests.
It is not the best catalog of closed models or creator media tools. Its value is inference performance and deployment control.
Best for: Production applications standardizing on open models and planning for dedicated capacity.
Choose it over Together AI when: Serving performance and deployment controls carry more weight than broad research, training, or multimodal experimentation.
5. fal — Best Venice API Alternative for Image and Video
fal offers more than 1,000 image, video, audio, and 3D models. It supports synchronous requests, queued jobs, webhooks, and real-time connections for generations that may take seconds or minutes.
fal documents up to 10 automatic retry attempts for some failures and generally charges for successful outputs rather than queue or server errors.
It is not a drop-in Venice chat replacement: models have their own schemas, and generated media URLs may remain public until expiry. Confidential assets need a deliberate storage and deletion workflow.
Best for: Creative applications, image editing, video generation, audio tools, and media production pipelines.
Choose it over GPT Proto when: Media-model depth and job orchestration matter more than keeping text and media behind one OpenAI-style API.
6. Replicate — Best for Community and Custom Models
Replicate offers more than 100 official models plus community models, fine-tunes, private models, and custom deployments. Processing-time or model-specific billing lets teams test unusual models without provisioning hardware.
Shared public models can cold boot or queue, and integration revolves around predictions rather than an OpenAI chat contract. Standard prediction endpoints allow roughly 600 requests per minute and many other endpoints around 3,000, subject to model and account conditions.
It works best as a model lab or custom execution layer, not a uniform chat API.
Best for: Testing community models, deploying custom models, and shipping prototypes before infrastructure requirements settle.
Watch for: Cold-start latency, per-model schemas, output persistence, and the difference between shared and dedicated hardware.
7. vLLM — Best Self-Hosted Alternative for Maximum Control
vLLM runs supported models on infrastructure you control. It exposes OpenAI-compatible chat, completions, responses, and embedding endpoints, with streaming, structured output, and tool calling where supported.
It can keep prompts, weights, logs, and network paths inside your environment, but you must configure isolation, encryption, logging, backups, and retention. Its --api-key setting does not protect every endpoint, so hardened deployments need an authenticated reverse proxy.
There is no gateway markup, but GPU, engineering, monitoring, scaling, and on-call costs remain. High, steady utilization may justify them; spiky traffic often does not.
Best for: Regulated deployments, private networks, sustained open-model workloads, and teams with GPU operations experience.
Do not choose it if: You need closed models, instant catalog breadth, or a managed service with no infrastructure ownership.
Which Venice API Alternative Should You Choose?
Use the decision that matches your bottleneck:
| Your main requirement |
Best choice |
Why |
| One affordable API for many modalities |
GPT Proto |
Broad catalog, OpenAI-compatible access, and discounted model pricing |
| Automatic LLM provider routing |
OpenRouter |
Routing policies, fallbacks, and bring-your-own-key support |
| Open-model fine-tuning |
Together AI |
Fine-tuning, LoRA, batch jobs, and serverless inference |
| Production open-model serving |
Fireworks AI |
Multiple deployment tiers and inference-focused controls |
| Deep image and video catalog |
fal |
Large media catalog plus queues, webhooks, and retries |
| Community or custom model testing |
Replicate |
Flexible prediction layer and broad public model ecosystem |
| Infrastructure-level privacy |
vLLM |
Self-hosted data path and full operational control |
| Venice-specific Private, TEE, or E2EE modes |
Stay with Venice |
None of the managed alternatives duplicates the complete privacy design |
Most teams do not need to reproduce every Venice feature. They need a reliable gateway, the right models, and a forecastable bill. GPT Proto is the best default; the ranking changes when routing, fine-tuning, media specialization, or cryptographic privacy dominates.
How to Switch from Venice API to GPT Proto
For a standard chat-completions integration, the first code change is small:
| Setting |
Venice API |
GPT Proto |
| API key environment variable |
Your Venice key |
GPTPROTO_API_KEY |
| Base URL |
Venice API base URL |
https://gptproto.com/v1 |
| Model |
Venice model identifier |
GPT Proto model identifier, such as glm-5.3 |
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["GPTPROTO_API_KEY"],
    base_url="https://gptproto.com/v1",
)

response = client.chat.completions.create(
    model="glm-5.3",
    messages=[
        {
            "role": "user",
            "content": "Summarize the main risks in this product launch plan.",
        }
    ],
)

print(response.choices[0].message.content)
OpenAI compatibility covers the request shape, not identical behavior. Before moving production traffic, test:
JSON mode and schema-constrained output
Tool definitions, parallel tool calls, and multi-turn tool results
Streaming event order and usage accounting
Error objects, retryable status codes, and timeout behavior
Context-window limits and truncation behavior
Image, audio, or video inputs and outputs used by your application
Model aliases, retirement notices, and fallback behavior
Any Venice-specific parameters, including its system-prompt control
One public developer report showed why: a generic compatible SDK layer dropped reasoning metadata during multi-turn Gemini tool use, and the next request failed with a 400. This was not necessarily a Venice defect; it shows how adapters can lose provider-specific state.
Send a small traffic percentage first, compare latency and structured-output validity, and keep a reversible routing switch until errors stabilize. The base URL is the easy part; the behavior audit is the migration.
When Should You Stay with Venice API?
Stay with Venice when one of these conditions defines the product:
You need its specific Anonymous, Private, TEE, or E2EE inference modes.
You want access to more than 350 models under its current catalog and policies.
Your application depends on Venice's permissive model selection.
DIEM allowance or x402 USDC payments fit your billing design.
You already tested Venice-specific parameters and do not gain enough from switching to justify another compatibility cycle.
No-retention language is not the same as end-to-end encryption, and self-hosting is not secure merely because the server sits in your account. Compare threat models, not labels.
If you stay, set Venice's system-prompt preference, monitor retirements, and verify which privacy modes support your tools. E2EE cannot coexist with server-side features that require plaintext.
Final Verdict
GPT Proto is the top Venice API alternative in 2026 for developers seeking affordable access to text, image, video, and audio models through one familiar API. It offers the closest practical replacement for Venice's gateway role, with a lower price in the GLM-5.3 comparison and minimal code changes for standard chat requests.
OpenRouter is better for provider routing. Together AI and Fireworks AI are better for open-model customization and production inference. fal leads for media-specific workflows, Replicate for community experimentation, and vLLM for self-hosted control.
Venice still wins when its privacy architecture is the deciding factor. No managed alternative in this ranking should be described as a complete substitute for Venice's Private, TEE, and E2EE modes.
Choose two finalists, replay a representative test set, and compare total cost, p95 latency, output validity, and failure recovery. For most teams without a Venice-specific privacy requirement, GPT Proto is the first option I would test.