Best Affordable LLM APIs for Agents at a Glance
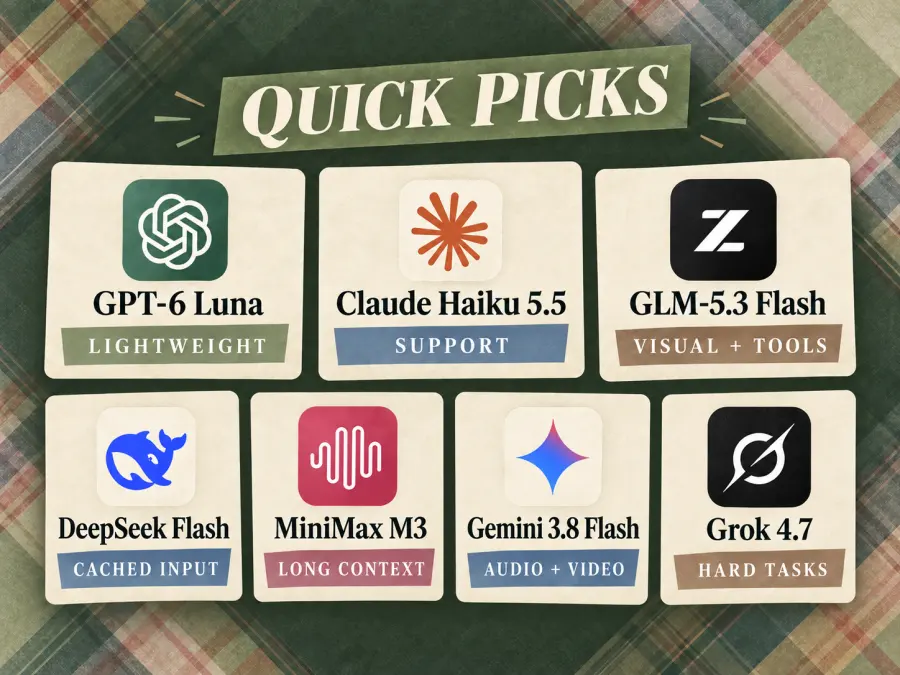
This shortlist groups models by the work they are worth testing for. It is an editorial selection based on published capabilities and pricing, not a private head-to-head performance ranking.
| Model |
GPT Proto model string |
Published GPT Proto input / output per 1M tokens |
First workload to test |
| GPT-6 Luna |
gpt-6-luna |
$0.08 / $0.40 |
Classification, extraction, and routing |
| Claude Haiku 5.5 |
See the model page’s Quick Start |
$0.09 / $0.45 for prompts ≤100K tokens |
Repetitive support tasks and coding sub-tasks |
| GLM-5.3 Flash |
glm-5.3-flash |
$0.15 / $0.50 |
Visual and tool-driven workflows |
| DeepSeek Flash |
deepseek-flash |
$0.30 / $1.20 |
Repeated instructions and cache-heavy inputs |
| MiniMax M3 |
MiniMax-M3 |
$0.48 / $0.96 |
Long document and research sessions |
| Gemini 3.8 Flash |
gemini-3.8-flash |
$0.90 / $4.50 |
Audio, video, image, and PDF workflows |
| Grok 4.7 |
grok-4.7 |
$1.20 / $3.60 |
Difficult coding and multi-step escalation |
Rates checked or confirmed October 8, 2026. These are GPT Proto rates, not provider-direct promotional prices. Haiku 5.5 costs $0.45 input and $2.25 output per million tokens for prompts above 100K tokens. Confirm the applicable context tier, cache charges, service tier, and live rate on each model page before budgeting.
Compare before you commit: Browse GPT Proto's available AI models and keep shortlisted model IDs behind configuration so you can switch without rebuilding the entire agent.
How We Ranked These Affordable LLMs for Agentic AI
Simon Willison offers a useful working definition: an LLM agent runs tools in a loop to achieve a goal. That loop changes how affordability should be measured. A normal chatbot comparison can focus on the cost of one response; an agent comparison must also count tool calls, tool results, retries, reasoning tokens, and unsuccessful runs.
We used the following order of evaluation.
1. The model must pass an agent capability gate
A model was not included merely because it had a low token price. Each shortlisted option needed a documented route for function calling or tool use, plus a usable way to return structured data or continue a multi-turn workflow.
2. Public agent evidence matters more than a general knowledge score
The Berkeley Function Calling Leaderboard is especially useful for understanding what a tool-use evaluation should inspect: correct function selection, valid arguments, multi-turn behavior, and cases where the model should avoid calling a tool. Its public leaderboard was last updated on April 12, 2026, however, which predates most models in this article. We therefore use its methodology rather than assigning its older scores to newer releases.
We also reference Artificial Analysis. Its Intelligence Index includes agentic knowledge work, real-world work, SaaS automation, terminal use, and long-context evaluations. It remains a mixed index—not a pure function-calling score—and should be treated as screening evidence rather than a guarantee for a particular agent.
3. Cost per successful task matters more than price per token
The useful production metric is:
Cost per successful task = Total API cost of all attempts and retries / Accepted task completions
This calculation should include uncached input, cached input, output, hidden or billed reasoning tokens where applicable, failed attempts, and recovery calls. If one model finishes 90 out of 100 tasks and another finishes 60, comparing only their headline token rates hides the cost of repairing the other 40 tasks.
4. Speed, verbosity, and integration friction affect cost
Output tokens per second measure only the generation phase. They do not capture time to first answer, internal reasoning, tool execution, rate-limit delays, or repeated calls. A verbose model may also turn a low output price into a larger final bill.
Finally, similar APIs still have model-specific rules. Reasoning fields, unsupported sampling parameters, function-response IDs, and model-name capitalization can all break an otherwise portable workflow. This is why the exact GPT Proto model string is included for every entry.
1. GPT-6 Luna — Best for Lightweight, High-Volume Agent Steps
GPT-6 Luna is our first pick for frequent, bounded requests: classify a ticket, extract product attributes, select a workflow, or summarize a tool result. GPT Proto lists it at $0.08 per million input tokens and $0.40 per million output tokens, the lowest listed input and output rates in this shortlist.
The model accepts text and images, supports structured outputs, and offers a 1.05M-token context window. Adjustable reasoning lets developers test how much effort a task needs. A simple routing decision rarely needs the same configuration as an ambiguous coding problem.
There is a compatibility detail to check before using it as a tool-calling controller. OpenAI documents reasoning-enabled function calling through Responses; Chat Completions supports function calling only with reasoning_effort: "none". Use the GPT Proto model page's Try this model Quick Start to verify the route and supported fields.
Luna's role is the inexpensive first layer. It can handle routine steps while a more capable model takes over after a clear failure or complexity signal. A low token rate only helps if those first steps remain accurate.
Choose GPT-6 Luna when:
the workflow contains large volumes of classification, extraction, or summarization;
each step has a clear schema and a result your application can check;
you want a low-cost baseline for an existing OpenAI-compatible application;
difficult cases can be escalated instead of retried indefinitely.
Watch for: endpoint-specific tool support and repeated validation failures. Use Luna for bounded work; evaluate a stronger model for complex planning and recovery.
2. Claude Haiku 5.5 — Best for Low-Cost Support and Claude Agent Steps
Claude Haiku 5.5 is a strong alternative for repetitive support work, conversation summaries, classification, and smaller coding tasks. Released on October 7, 2026, it brings adjustable effort to the Haiku tier and can serve as the less expensive worker in a workflow that also uses larger Claude models.
GPT Proto offers Haiku 5.5 at 10% below official rates. For requests with up to 100K input tokens, that means $0.09 per million input tokens and $0.45 per million output tokens. Above 100K input tokens, the corresponding rates are $0.45 input and $2.25 output.
That threshold matters more than the maximum context window. Haiku supports 1M context, but a growing conversation can cross into the higher price tier well before it reaches that capacity. The threshold applies to the input of each request, including retained conversation and tool results.
Adaptive thinking is enabled by default, with effort controlling how much work the model spends on a task. Start with focused requests and compare completion quality, latency, and billed tokens before increasing effort.
Choose Claude Haiku 5.5 when:
an agent handles repeated support questions or ticket triage;
summaries and compacted conversation state are frequent workflow steps;
a Claude-based coding workflow needs help with focused sub-tasks;
most requests stay within the lower prompt-length price tier.
Watch for: requests crossing 100K input tokens. Keep reusable state compact and check the full request cost, especially in long conversations.
3. GLM-5.3 Flash — Best for Low-Cost Visual and Tool-Driven Agents
GLM-5.3 Flash remains one of the most useful candidates for workflows that combine visual evidence with external tools. Its published GPT Proto rates are $0.15 per million input tokens and $0.50 per million output tokens.
Z.ai documents native input support for text, images, video, and files, together with a 1M-token context window. Function calling, structured JSON, caching, streaming, and streamed tool arguments make it relevant to agents that inspect documents or interfaces and then take another step.
A practical example is a visual QA workflow: inspect a screenshot, identify a layout issue, propose a code change, and review the rendered result through the application's tools. The model supplies decisions and arguments; the surrounding agent provides the browser, code execution, and verification.
The main trade-off is always-on reasoning. That can help with ambiguous decisions, but it also creates overhead for basic labeling or extraction. GPT-6 Luna and Haiku 5.5 have lower short-request token rates in this shortlist.
Choose GLM-5.3 Flash when:
screenshots, charts, documents, or video evidence influence the next action;
the workflow needs tool calls and structured results;
visual coding or iterative interface checks are part of the task;
open weights are useful alongside hosted API access.
Watch for: reasoning and output volume. Set limits on generated tokens and workflow steps; the Flash name does not establish end-to-end latency.
4. DeepSeek Flash — Best for Cached, Input-Heavy Open-Weight Agents
DeepSeek Flash is the route name for DeepSeek V4.1 Flash. Use deepseek-flash in the request rather than treating the version name as a separate API tier. GPT Proto's displayed input/output rates are $0.30 / $1.20 per million tokens.
The model combines text and image input, a context window of up to 1M tokens, tool calls, JSON output, streaming, and thinking or non-thinking operation. That combination suits agents that repeatedly read repository files, instructions, documents, or tool history before generating a comparatively small result.
Caching is the reason to include it in an input-heavy shortlist. Stable instructions and tool definitions may be reused across many calls, but the saving depends on actual cache hits. A long prompt that changes substantially on every turn should be budgeted differently.
State handling also needs attention. In native thinking-mode tool workflows, reasoning state may need to be retained between calls. Verify how the selected GPT Proto endpoint represents that state before migrating a multi-turn loop. A valid first response does not establish that the whole conversation will remain compatible.
Choose DeepSeek Flash when:
repeated instructions or reference material make caching useful;
repository inspection or document analysis dominates input volume;
the workflow benefits from switching between thinking and non-thinking work;
image evidence needs to accompany text in the same task.
Watch for: cache misses, verbose output, and lost tool-call state. Measure the complete loop instead of estimating savings from the cache rate alone.
5. MiniMax M3 — Best for Long Document and Research Agents
MiniMax M3 is worth considering when an agent needs a large body of documents or a long working history. On GPT Proto, the model string is MiniMax-M3, with displayed rates of $0.48 per million input tokens and $0.96 per million output tokens.
The model supports tool use and long-context coding and agent workflows, with a context window of up to roughly 1M tokens. Its role here is document-heavy work: compare policies, review support histories, trace relationships across reference files, or retain intermediate research results.
The price trade-off deserves a clear explanation. MiniMax's current direct rates for prompts up to 512K input tokens are $0.30 input and $1.20 output per million tokens. At those rates, GPT Proto has the lower output price while the direct route has the lower input price. Neither headline rate determines the cheaper bill for every workload.
A large context window also does not replace retrieval or validation. Feeding an agent an entire archive can increase its bill without helping it find the right evidence.
Choose MiniMax M3 when:
a task depends on several documents or an extended working history;
the agent needs to retain intermediate findings across multiple steps;
generated reports or explanations make output cost relevant;
you want to evaluate an open-weight model through hosted access.
Watch for: expensive accumulated input and missed evidence in long documents. Test cross-document reasoning and confirm the selected route's input capabilities.
6. Gemini 3.8 Flash — Best for Audio, Video, and Mixed-Media Agents
Gemini 3.8 Flash earns its place when the task includes audio, video, images, or PDFs as well as text. GPT Proto displays $0.90 per million input tokens and $4.50 per million output tokens for the gemini-3.8-flash route.
The model has a roughly 1M-token input window, adjustable thinking, function calling, and structured output. It is a practical candidate for a workflow that reviews a customer video, reads a supporting document, and prepares the next application action.
Its value comes from the work those inputs can replace. An agent that understands several media types may need fewer separate processing stages. Verify supported file formats and request mapping on the GPT Proto route before assuming the upstream model's full tool ecosystem is available.
It is not the lowest token-price option here. Google's direct introductory rates are $0.75 input and $3.75 output per million tokens through December 31, 2026, below GPT Proto's currently displayed rates. The reason to use this route is access alongside other models through one account and balance.
Choose Gemini 3.8 Flash when:
audio or video is central to the task;
the same workflow must inspect several media types;
a multimodal model can simplify separate preprocessing stages;
adjustable reasoning is useful across routine and difficult requests.
Watch for: output cost and provider-specific tool support. Benchmark the finished workflow rather than relying on a generation-speed figure.
7. Grok 4.7 — Best for Difficult Coding and Multi-Step Escalation
Grok 4.7 is the escalation choice in this shortlist. It is already listed on GPT Proto at $1.20 per million input tokens and $3.60 per million output tokens, matching the displayed rates for Grok 4.6.
The model accepts text and images, supports function calling and structured outputs, and provides a 500K-token context window. Its four reasoning levels—low, medium, high, and xhigh—let developers test how much effort a difficult task needs.
That makes it relevant when an agent must diagnose a failed code change, coordinate several dependent tool results, or reconsider a plan after validation fails. A lower-cost model can handle routine preparation while Grok handles the difficult step.
The limit is economic rather than just technical. Sending every extraction or routing request to an escalation model adds cost before its stronger reasoning is needed. A newer release at the same token rates also does not prove a lower completed-task bill; compare both versions if an existing application already relies on Grok 4.6.
Choose Grok 4.7 when:
a coding or research task needs several dependent decisions;
the lower-cost route repeatedly fails a defined acceptance check;
image evidence and reasoning must be considered together;
successful recovery is worth the additional model expense.
Watch for: expensive retries and excessive reasoning effort. Keep it on a defined escalation path, and stop when the task needs a permission or missing input that another model cannot provide.
Why Cheap Tokens Can Still Produce Expensive Agent Tasks
A low token rate helps with repeated classification or rewriting. It says much less about an agent that must choose tools, interpret their results, and recover from mistakes.
A model may produce cheap responses while repeatedly selecting the wrong function or omitting a required argument. Each repair adds another model call, more conversation history, and potentially another tool operation. The task can become expensive before the agent produces an acceptable result.
Before giving a model control of a workflow, check whether it can:
distinguish between similar tools;
produce arguments that satisfy both the schema and business rules;
continue after a tool result or a recoverable error;
recognize when no available tool is appropriate.
Start with your acceptance threshold, then compare the total cost of the models that pass. A narrow extraction step and a multi-tool controller do not need the same model.
A Practical Low-Cost Model Routing Strategy
You can assign different steps to different models inside one agent. Routine preparation goes to a low-cost route; difficult reasoning goes to an escalation route. The application makes that choice using task type, validation results, and spending limits.
| Agent task |
First model to evaluate |
Escalate or change route when |
| Classification, extraction, and request routing |
GPT-6 Luna |
The output fails validation or the request is ambiguous |
| Repetitive support and Claude coding sub-tasks |
Claude Haiku 5.5 |
Broader planning is needed or repeated attempts fail; review costs if input crosses 100K |
| Visual checks and document-based tool workflows |
GLM-5.3 Flash |
The model cannot resolve conflicting evidence or complete verification |
| Repeated, cache-heavy context |
DeepSeek Flash |
State is lost, tool handling fails, or measured cache savings do not materialize |
| Long document and research sessions |
MiniMax M3 |
Important cross-document relationships are missed |
| Audio, video, and mixed-media input |
Gemini 3.8 Flash |
Extracted evidence requires a separate, harder planning step |
| Difficult coding and multi-step recovery |
Grok 4.7 |
The workflow reaches its time, step, or spending limit |
These are starting points for evaluation. A validation failure can come from the prompt, tool definition, or application as well as the model; inspect the cause before paying for a stronger route.
Keep the agent's cost under control with five rules:
Use a low-cost model only after it passes the task's acceptance checks.
Validate tool arguments before execution.
Cap model calls, output tokens, elapsed time, and spending for each run.
Define a recovery or escalation rule instead of retrying the same request indefinitely.
Stop for approval when an action exceeds the agent's permissions.
GPT Proto supplies access to supported models with one API key and shared balance. The application or framework still manages routing, state, tool execution, and stopping conditions. See the LLM API for AI agents page to compare model access and estimate an existing workflow's costs.
Minimal Tool-Calling Request with GPT Proto
This example uses glm-5.3-flash and defines get_order_status as a tool the application can execute. A model response may request that function; the request itself does not give the model access to your order system.
Open the GLM-5.3 Flash model page and select Try this model for the current Quick Start, then supply your server-side API key to the example.
curl https://gptproto.com/v1/chat/completions \
  -H "Authorization: Bearer $GPTPROTO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "glm-5.3-flash",
    "messages": [
      {
        "role": "user",
        "content": "Where is order A-1042?"
      }
    ],
    "tools": [
      {
        "type": "function",
        "function": {
          "name": "get_order_status",
          "description": "Return the current status of one order.",
          "parameters": {
            "type": "object",
            "properties": {
              "order_id": {
                "type": "string",
                "description": "The order identifier."
              }
            },
            "required": ["order_id"],
            "additionalProperties": false
          }
        }
      }
    ],
    "tool_choice": "auto"
  }'
For an OpenAI-compatible Chat Completions response, inspect choices[0].message.tool_calls. For every returned call:
check that the function is allowed for this user and task;
parse and validate the arguments;
execute the function in your application;
return its result in a tool message with the matching tool_call_id;
request the next model response, keeping any required reasoning state.
Switching the model requires a compatibility check. GPT-6 Luna's upstream Chat Completions tool calling requires reasoning_effort: "none"; reasoning-enabled function calling uses Responses. Other routes may have different state or parameter requirements. Check each model's Quick Start instead of assuming an identical payload works everywhere.
This is the first request in a tool loop. Your application must supply the tool execution and subsequent messages.
How to Test an Affordable LLM API for Your Agent
Use representative tasks from your application. A general benchmark can help build the shortlist, but a model must also work with your tool names, data, and acceptance rules.
Start with four categories:
Tool selection: Offer similar functions and check whether the model chooses the correct one.
Multiple tools: Give a request that needs two independent results. Test parallel calls where the route supports them, or complete both through successive turns.
No-tool requests: Include questions for which none of the available tools should be called.
Recovery: Return a realistic tool error and check whether the model corrects its next step without looping indefinitely.
Keep the instructions, tool definitions, input data, and acceptance criteria consistent. Use supported settings for each route and record its endpoint and reasoning configuration; identical parameter names are not always portable between providers.
Run each category at least five times per model. With seven models, four categories, and five repeats, the initial comparison contains 140 runs. This is a pilot evaluation design, not a claim that those runs have already been completed or that five repeats establish production reliability.
Record:
accepted task completions;
correct tool choices and valid arguments;
unnecessary calls and recovery failures;
model turns and total workflow time;
uncached input, cache reads or writes, and billed output or reasoning tokens;
applicable prompt-length tiers and other billed components;
total API cost, including retries and unsuccessful attempts.
Calculate:
Cost per accepted task = Total API spend across the evaluation / Number of accepted completions
Report failures separately, especially if a model accepts no tasks. Compare costs only after checking the quality threshold; then expand the evaluation around the failure cases that matter in production.
What Agent Builders Say About Latency
Community reports add context that pricing pages cannot provide. In one AI Agents community discussion, a simple retrieval system reportedly answered in under one second, while a more agentic version took almost three seconds. For customer support, that difference was described as a dealbreaker.
Other participants disagreed with the universal conclusion. They noted that research and internal analytics users may accept much longer waits when tool use materially improves the answer. The useful lesson is not that three seconds is always too slow. It is that the same model can be affordable for one agent and unsuitable for another because latency, quality, and failure costs have different values.
Treat community comments as experience reports, not benchmark results. Use them to identify failure cases for your own evaluation.
For your own agent, measure time to first useful answer and time to completed task alongside generation speed. A model can start quickly but take several additional turns to finish. Interactive support and background research may therefore need different latency targets, even when they use the same API route.
Final Recommendation
For frequent, bounded steps, start with GPT-6 Luna. It has the lowest listed base input and output rates in this shortlist and fits requests that your application can validate.
Choose Claude Haiku 5.5 for repetitive support and Claude coding sub-tasks, while keeping the 100K input pricing threshold visible. Use GLM-5.3 Flash when screenshots, documents, or other visual evidence guide the next tool action.
Evaluate DeepSeek Flash for repeated, cache-heavy input and MiniMax M3 for long document sessions. Choose Gemini 3.8 Flash when audio or video understanding reduces the number of separate processing stages. Reserve Grok 4.7 for difficult coding and multi-step recovery.
The final choice should be the model that reaches your acceptance target at the lowest measured workflow cost. Use token rates to build the shortlist, then include failed runs, reasoning, tools, and retries in the decision.
Ready to connect your shortlist? Explore GPT Proto's LLM API for AI agents for supported models, workload estimates, and access through one key and shared balance. Use each model page's Try this model panel for its Quick Start and review GPT Proto pricing before scaling.