The Best Chinese LLM Models at a Glance
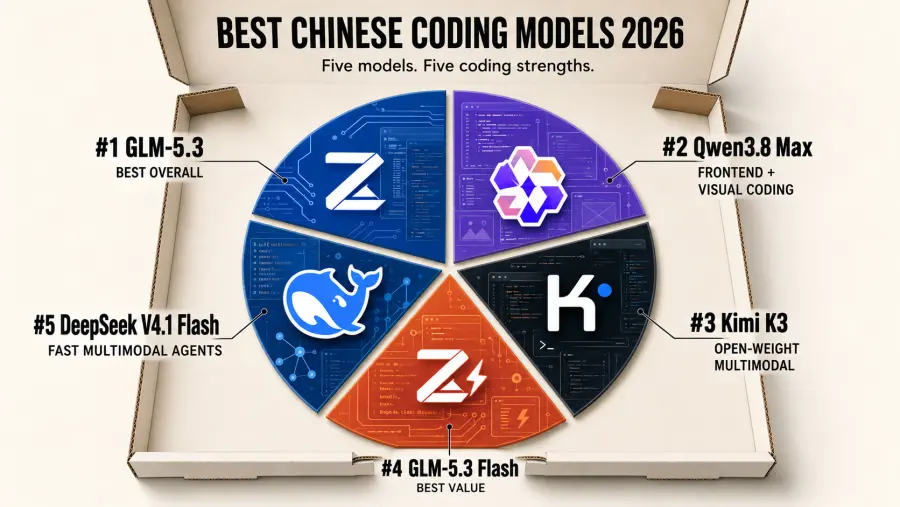
| Rank |
Model |
Best for |
Artificial Analysis Intelligence Index |
Measured output speed |
Context |
GPT Proto input |
Weight status |
GPT Proto price per 1M tokens |
| 1 |
GLM-5.3 |
Text-only coding agents, terminal work, long-horizon engineering |
45 |
60.5 tok/s |
1M |
Text |
Open weights, custom GLM-5.3 License |
$1.26 input / $3.96 output |
| 2 |
Qwen3.8-Max-0902 |
Frontend coding, screenshot analysis, visual agents |
45 |
35.7 tok/s |
1M |
Text, image, video, document |
Hosted snapshot; no separately labeled 0902 checkpoint confirmed |
$1.80 / $5.40 |
| 3 |
Kimi K3 |
Difficult multimodal coding and open-weight deployment |
44 |
41.1 tok/s |
1M |
Text, image, document |
Open weights, custom Kimi K3 License |
$2.70 / $13.50 |
| 4 |
GLM-5.3 Flash |
Cost-efficient visual coding, agents, and high-volume production |
42 |
57.5 tok/s |
1M |
Text, image, video, document |
Open weights, MIT |
$0.15 / $0.50 |
| 5 |
DeepSeek V4.1 Flash |
Fast multimodal agents, terminal work, long documents |
39 |
217.4 tok/s |
1M |
Text, image |
Open weights, MIT |
$0.30 / $1.20 |
The intelligence scores use Artificial Analysis Intelligence Index v4.3.2 and were checked on October 10, 2026. This is a new evaluation version, so its scores should not be compared directly with the 60-point figures shown in the previous version of this article.
The speed measurements come from each model creator’s API as measured by Artificial Analysis. They are useful snapshots, not latency guarantees for GPT Proto. Provider load, prompt length, reasoning effort, cache behavior, and output length can all change production performance.
The modality column describes the routes exposed by GPT Proto. A downloadable checkpoint and a hosted API with a similar name may not expose identical features.
How We Ranked the Chinese Coding Models
A large parameter count or a one-million-token context window does not tell you whether a model can finish a repository task. All five models in this ranking sit in roughly the same long-context class. Their practical differences appear elsewhere.
We considered six questions:
How does the model perform in independent evaluations rather than only its developer’s benchmark charts?
Can it sustain multi-file coding, terminal work, tool calls, and plan–execute–verify loops?
Can it inspect screenshots, diagrams, documents, or recorded product flows when the evidence is not text-only?
What does a realistic API task cost after output tokens, reasoning, and likely retries are included?
Are the model weights actually downloadable, and what license governs commercial deployment?
Is there a live GPT Proto route that readers can test through the same account and API format?
The final ranking is coding-focused rather than a direct copy of the Intelligence Index. GLM-5.3 and Qwen3.8-Max-0902 currently tie at 45, but they solve different problems. GLM is the stronger default for difficult text-only agent loops because it is cheaper and faster in the current measurements. Qwen is the better choice when screenshots, video, or visual documents change the answer.
GLM-5.3 Flash ranks above DeepSeek V4.1 Flash despite DeepSeek’s large speed advantage. GLM scores higher in the current independent evaluation and costs less per token. DeepSeek counters with much higher measured throughput and continuously adjustable reasoning effort.
1. GLM-5.3: Best Chinese Coding Model Overall
A one-million-token context window or a large parameter count does not prove that a model can finish a repository task. All five models in this ranking support long-context work. Their practical differences appear in agent behavior, visual input, output speed, licensing, and the cost of repeated tool loops.
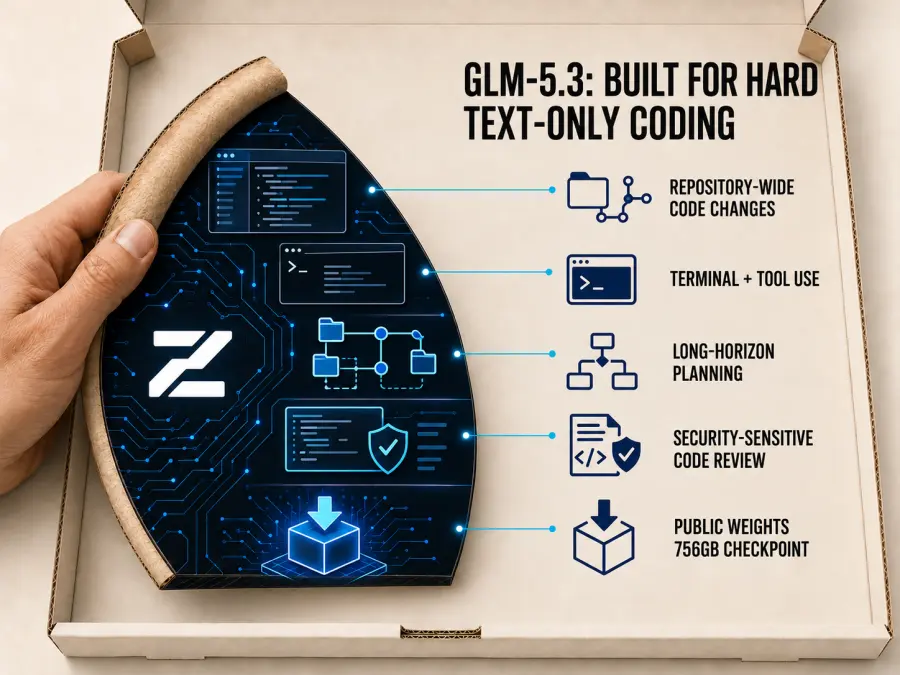
Z.ai did not build a larger base model for this release. GLM-5.3 uses the same base as GLM-5.2 and gets its gains from expanded post-training for software engineering, terminal work, long-horizon agents, and defensive code review. That is useful context: the upgrade targets how the model works through a task, not how much raw context it can hold.
The independent signal is strong. Artificial Analysis currently scores GLM-5.3 at 60, tied with Kimi K3 and ahead of Qwen3.8 Max and DeepSeek V4 Pro 0813. It also measures about 90 output tokens per second through Z.ai's API.
Z.ai's own coding results are more specific, although they remain vendor-reported. The company reports that GLM-5.3 improved from 4.6 to 28.3 on Terminal-Bench 3.0 and from 46.2 to 66.9 on DeepSWE v1.1. On its private Z.ai Code Bench, GLM-5.3 reached 34.5% at max effort while using about 75,000 output tokens per task, compared with GLM-5.2's 23.4% at roughly 96,000 tokens. The official GLM-5.3 documentation publishes the full comparison.
That combination fits work such as:
Repository-wide refactoring
Multi-file debugging and dependency migration
Terminal and CI troubleshooting
Agents that must run commands, inspect results, revise a plan, and continue
Defensive review of authentication, validation, and dependency changes
Long technical reports generated from text-based specifications and logs
On GPT Proto, GLM-5.3 costs $1.26 per million input tokens and $3.96 per million output tokens. It supports a one-million-token combined context window and up to 128K output tokens. Reasoning is always enabled, with low, high, and max effort levels.
There are three trade-offs.
First, the GPT Proto route discussed here is text-only. It cannot directly inspect a broken layout screenshot, design file, or recorded product flow. Route that step to Qwen3.8-Max-0902, GLM-5.3 Flash, Kimi K3, or DeepSeek V4.1 Flash.
Second, open weights do not make GLM-5.3 a casual self-hosting choice. The checkpoint is roughly 756GB, and the custom license deserves review before large commercial deployment or Model-as-a-Service use.
Third, maximum reasoning can generate a large amount of output. Use lower effort for routine classification, extraction, and formatting, then reserve maximum effort for repository-wide changes, difficult terminal work, and security-sensitive review.
Verdict: Choose GLM-5.3 as the default for difficult text-only coding agents. Keep a multimodal model available for visual steps, and do not treat public weights as evidence that local deployment will be cheap or simple.
2. Qwen3.8-Max-0902: Best for Frontend and Visual Coding
Qwen3.8-Max-0902 is Alibaba’s September 2 revision of Qwen3.8 Max. It retains the family’s 2.4-trillion-parameter Mixture-of-Experts architecture and adds further post-training for coding, cowork, scientific research, and multi-stage professional tasks.
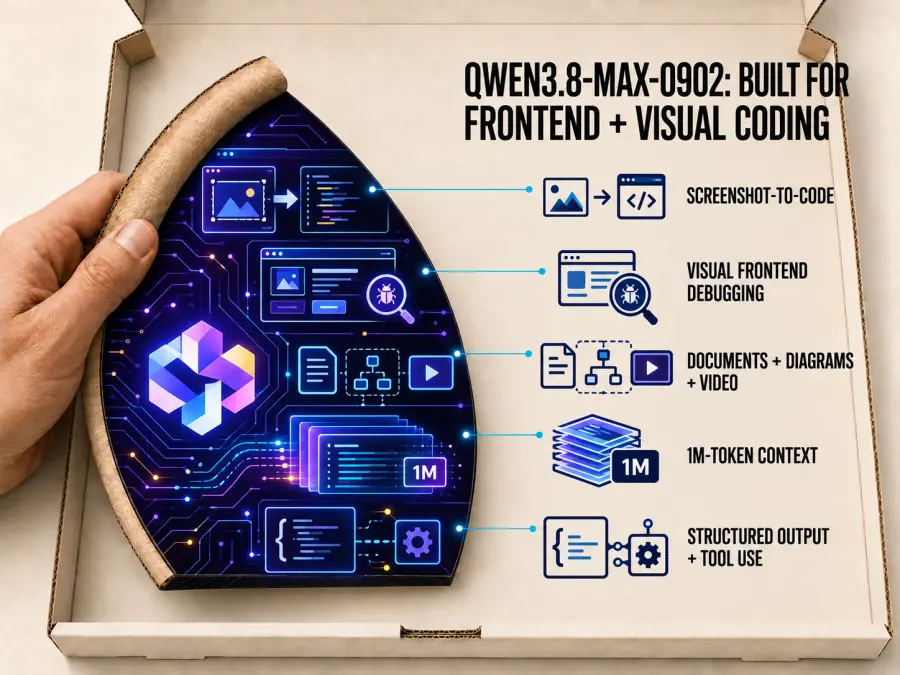
The 0902 revision matters. Artificial Analysis scores it at 45 on the current Intelligence Index, compared with 40 for the earlier Qwen3.8 Max snapshot. That moves Qwen into a tie with GLM-5.3 on the broad independent index.
The visual input is the main reason to choose it over GLM-5.3. Qwen can combine code with screenshots, diagrams, documents, and video, then return structured text or JSON. That fits work such as:
Comparing a rendered frontend with a reference screenshot
Rebuilding an interface from a visual design
Inspecting layout failures that are difficult to describe in text
Reading architecture diagrams beside source code
Extracting requirements from documents and recorded product flows
Returning schema-constrained output for a downstream agent
The model supports a nominal one-million-token context window, up to 131,072 output tokens, function calling, structured output, context caching, and thinking or non-thinking operation. On GPT Proto, Qwen3.8-Max-0902 costs $1.80 per million input tokens and $5.40 per million output tokens.
Speed is the trade-off. Artificial Analysis measures about 35.7 output tokens per second through Alibaba’s API, well below GLM-5.3 and far below DeepSeek V4.1 Flash. A visual coding agent may therefore produce a better answer while taking longer to finish it.
The hosted 0902 snapshot should not be confused with a downloadable checkpoint that happens to carry a related Qwen3.8 name. Alibaba has not identified a separately labeled 0902 weight release with the same hosted capabilities. Do not promise hosted features such as video input or optional reasoning for a self-hosted artifact unless that exact checkpoint documents them.
Verdict: Choose Qwen3.8-Max-0902 for frontend generation, screenshot-to-code, visual debugging, video understanding, or multimodal agent workflows. Choose GLM-5.3 when the task is text-only and cost or output speed matters more.
3. Kimi K3: Best for Difficult Multimodal Work and Large Open Weights
Kimi K3 remains one of the most capable Chinese open-weight models, but it is no longer the automatic winner for every coding workflow. Its current Artificial Analysis Intelligence Index score is 44, one point behind GLM-5.3 and Qwen3.8-Max-0902. The practical decision comes down to capability ceiling, multimodal evidence, API cost, and the infrastructure required to run its enormous checkpoint.
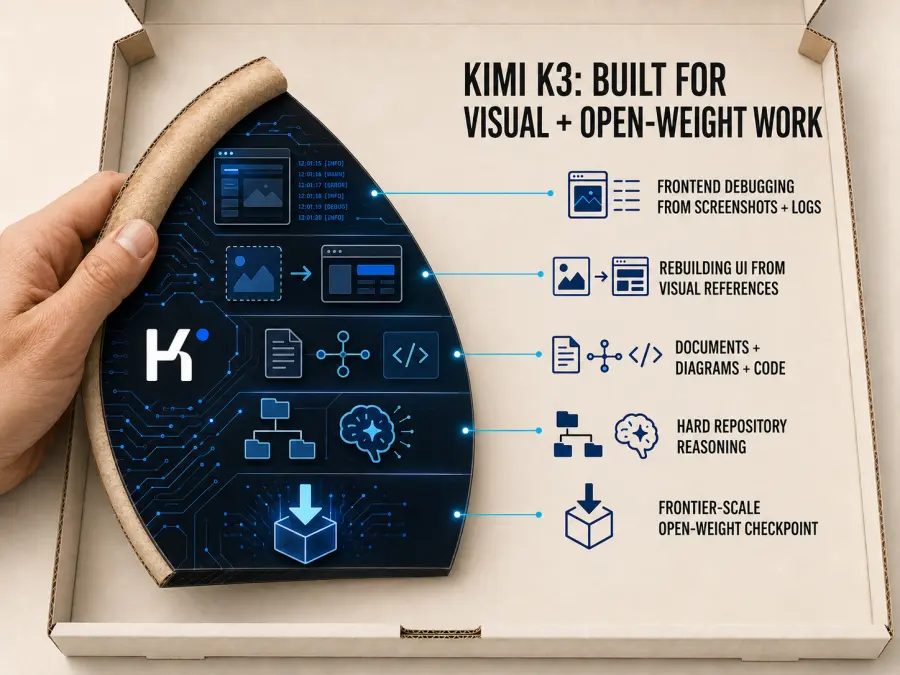
Moonshot AI built K3 for long-horizon coding, reasoning, knowledge work, and repeated tool use. Its architecture contains 2.8 trillion total parameters and activates 16 of 896 experts for each token. The model provides a one-million-token context window and can combine code with visual or document evidence through the hosted service.
Artificial Analysis scores Kimi K3 at 60, tying GLM-5.3 for the highest result in this list. The separation comes from cost, speed, modalities, and deployment.
Kimi K3 is relevant for:
Debugging a frontend from screenshots and runtime logs
Rebuilding an interface from a visual reference
Combining technical documents, diagrams, and code
Difficult repository tasks where general reasoning is the bottleneck
Teams that need access to a frontier-scale open-weight checkpoint
The cost is substantial. On GPT Proto, Kimi K3 is $2.70 per million input tokens and $13.50 per million output tokens. Artificial Analysis measures about 35.5 output tokens per second. A long agent that repeatedly plans, edits, reads tool results, and retries can therefore be both slower and much more expensive than GLM-5.3.
Self-hosting is not a casual alternative. The published checkpoint is about 1.56 TB, and Moonshot recommends a supernode deployment with 64 or more accelerators. Kimi K3 also uses a custom license rather than MIT, so large commercial deployments and Model-as-a-Service products need license review.
Verdict: Choose Kimi K3 when difficult reasoning, visual evidence, or access to its large open-weight checkpoint justifies the API and infrastructure cost. For routine production traffic, GLM-5.3 Flash or DeepSeek V4.1 Flash will usually be more economical.
4. GLM-5.3 Flash: Best Price-to-Performance Coding API
GLM-5.3 Flash is not simply a cheaper reasoning setting for GLM-5.3. Z.ai trained it from a different multimodal base and released it as the first GLM-5 model with native image, video, and document input.
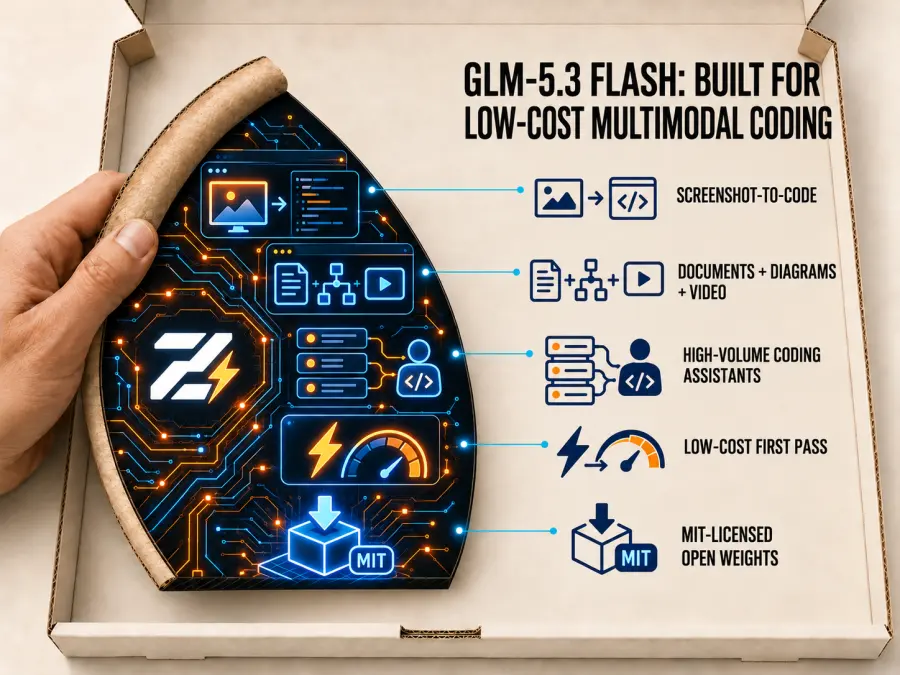
That distinction matters in a coding workflow. GLM-5.3 handles difficult text-only engineering tasks well, but Flash can also inspect a broken interface, compare a rendered page with a reference, read a diagram, or use a visual document as evidence before proposing a change.
Artificial Analysis currently scores GLM-5.3 Flash at 42. That is below GLM-5.3, Qwen3.8-Max-0902, and Kimi K3, but ahead of DeepSeek V4.1 Flash and MiniMax M3 in the same current Index version.
The price is the stronger argument. GPT Proto lists GLM-5.3 Flash at $0.15 per million input tokens and $0.50 per million output tokens. A request using 100,000 uncached input tokens and 20,000 output tokens costs about $0.025 before retries. That is roughly one eighth of the equivalent GLM-5.3 first pass.
GLM-5.3 Flash fits:
High-volume coding assistants and issue triage
Screenshot-to-code and visual regression analysis
Repository work that includes diagrams or product documents
Agents that repeatedly read tool output and revise a plan
Lower-cost first passes before escalation to GLM-5.3 or Kimi K3
Self-hosted deployments that prefer MIT-licensed weights
The trade-off is capability ceiling. A cheaper request is not a saving when a difficult migration, security review, or ambiguous repository change needs several retries. Use Flash as the production default, then escalate the hardest tasks when acceptance tests show that a larger model improves the result.
Verdict: Choose GLM-5.3 Flash when production cost, multimodal input, and open MIT weights matter more than winning the last few points of a broad intelligence benchmark.
5. DeepSeek V4.1 Flash: Best for Fast Multimodal Coding Agents
DeepSeek V4.1 Flash is the current model behind the deepseek-flash API string. Released on September 10, 2026, it replaces the retired V4 Flash and V4 Flash Vision experimental models behind their legacy aliases.
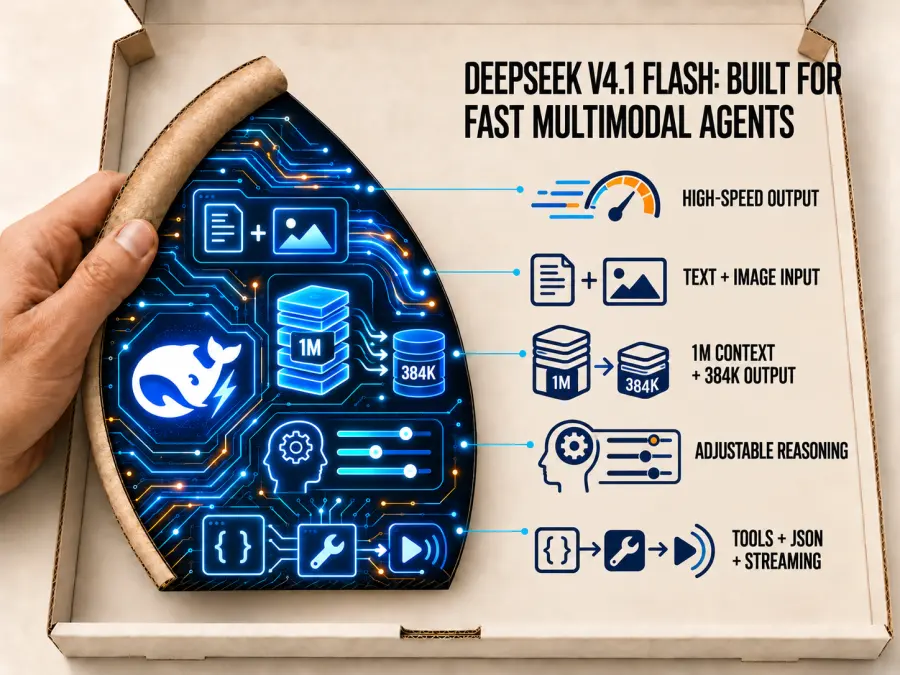
The architecture is designed for input-heavy agents. Its 552-billion-parameter backbone activates 8 billion parameters during input processing and 16 billion during generation. DeepSeek reports that the redesigned KV cache uses about one quarter of the memory required by V4 Flash, which matters when an agent repeatedly processes long repositories, documents, screenshots, and tool histories.
The coding results are strong enough to make the model more than a cheap worker. DeepSeek reports 90.6 on Terminal-Bench 2.1, 31.2 on Terminal-Bench 4.0, and 74.2 on DeepSWE v1.1. These are vendor-reported results, so they should be validated on the same repositories, tools, and time budget used for the other candidates.
The independent signal is more conservative but still competitive. Artificial Analysis scores the maximum-reasoning version at 39 and measures about 217.4 output tokens per second through DeepSeek’s API. That makes it the fastest model in this Top 5 by a wide margin.
DeepSeek V4.1 Flash supports:
Text and image input with text output
A one-million-token context window
Up to 384K output tokens
Thinking and non-thinking operation
Continuously adjustable reasoning effort
Tool calls, JSON output, streaming, and the Responses API
Open MIT-licensed weights
On GPT Proto, the model costs $0.30 per million input tokens and $1.20 per million output tokens. It is more expensive than GLM-5.3 Flash per token, but its measured throughput is much higher.
Verdict: Choose DeepSeek V4.1 Flash when speed, native image understanding, long output, or adjustable reasoning matters. Choose GLM-5.3 Flash when the primary goal is the lowest token cost with a slightly higher current independent score.
Honorable Mentions
DeepSeek V4 Pro 0813
DeepSeek V4 Pro remains available and may still suit teams with an existing validated integration or a requirement to pin the August 13 model. It supports text-only coding, selectable reasoning, a one-million-token context window, and up to 384K output tokens.
It no longer earns a Top 5 position here. DeepSeek V4.1 Flash scores higher in the current independent Index, adds native vision, generates output much faster, and costs substantially less. GPT Proto’s current V4 Pro rate is $1.12 per million input tokens and $3.37 per million output tokens.
MiniMax M3
MiniMax M3 remains useful for high-volume classification, code triage, document analysis, and other bounded subtasks. Its one-million-token context and multimodal input still make it a practical worker model.
It is no longer the best budget recommendation in this comparison. GPT Proto lists MiniMax M3 at $0.48 input and $0.96 output per million tokens, while GLM-5.3 Flash costs $0.15/$0.50 and scores materially higher in the current Artificial Analysis Index. MiniMax still deserves testing where its speed, existing prompts, or MiniMax-specific tooling improves the completed-task rate.
Models to Watch
Step 5 Preview and Xiaomi’s MiMo-V2.6 family are relevant new Chinese models, but they are not included in the main ranking because GPT Proto did not have confirmed live routes for them at the time of this update. Add them to the ranked list only after the exact model page, API string, price, and supported request fields are live and tested.
One Real Coding Task, Five Different Choices
Consider a TypeScript SaaS application that starts failing intermittently during its OAuth callback after an authentication-library upgrade. The coding agent must inspect the repository, trace the callback and session flow, reproduce the regression, change the implementation, run the test suite, and prepare a pull-request summary.
A useful instruction could be:
Investigate the OAuth callback regression in this repository.

Before editing:


1. Map the callback, session, and token-refresh paths.


2. Identify the library upgrade that changed the behavior.


3. Reproduce the failure with a test.


4. Propose the smallest safe patch.

After editing:


1. Run the relevant unit and integration tests.


2. Report every file changed.


3. Explain remaining risks.


4. Do not claim success unless the tests pass.
The best model changes with the evidence and environment:
| Stage or requirement |
Recommended model |
Why |
| Maintain a long text-only repository and terminal loop |
GLM-5.3 |
Strong current coding-agent results, 1M context, and lower cost than the other flagship models |
| Rebuild or debug a frontend from screenshots or video |
Qwen3.8-Max-0902 |
Multimodal input, structured output, and additional post-training for coding and cowork tasks |
| Handle the hardest mixed reasoning and visual evidence |
Kimi K3 |
High capability ceiling, multimodal input, and open-weight access |
| Run cost-sensitive visual coding and repeated agent subtasks |
GLM-5.3 Flash |
Best price-to-performance balance in the current GPT Proto lineup |
| Process long inputs and tool loops at high throughput |
DeepSeek V4.1 Flash |
Highest measured output speed in this Top 5, native vision, and adjustable reasoning |
A production agent does not need to send every stage to the same model. GLM-5.3 Flash can handle routine implementation and triage, Qwen can inspect visual evidence, DeepSeek can process long tool loops quickly, and GLM-5.3 or Kimi K3 can take the hardest escalated tasks.
What Would the Same Coding Task Cost?
Suppose the OAuth task consumes:
Using the GPT Proto prices listed on October 10, 2026, the first-pass token cost would be:
| Model |
Calculation |
Approximate cost |
| GLM-5.3 |
(0.1 × $1.26) + (0.02 × $3.96) |
$0.21 |
| Qwen3.8-Max-0902 |
(0.1 × $1.80) + (0.02 × $5.40) |
$0.29 |
| Kimi K3 |
(0.1 × $2.70) + (0.02 × $13.50) |
$0.54 |
| GLM-5.3 Flash |
(0.1 × $0.15) + (0.02 × $0.50) |
$0.03 |
| DeepSeek V4.1 Flash |
(0.1 × $0.30) + (0.02 × $1.20) |
$0.05 |
These figures do not claim that GLM-5.3 Flash will solve the task for three cents or that Kimi K3 will finish it in one attempt. They are first-pass token arithmetic. Reasoning tokens, cache hits, retries, tool output, and the number of agent turns change the final bill.
The metric that matters is cost per accepted fix, not price per million tokens.
Why the Benchmark Winner May Not Be the Best Coding Agent
A language model does not inspect files, execute commands, or merge a patch by itself. The surrounding agent decides:
Which repository files enter the context
How search results and terminal output are presented
Whether edits use exact patches or complete file rewrites
When tests run
What happens after a failed command
Whether the model sees the test result before claiming success
How much context survives between turns
Put the same model inside two different agent systems and the completion rate can change substantially.
The shared one-million-token context window creates another trap. Capacity is not a recommendation to paste an entire repository into every request. Generated files, dependency code, old logs, and unrelated documentation increase latency and can distract the model from the relevant execution path.
A better coding agent retrieves likely files first, keeps stable instructions near the beginning, stores checkpoints, summarizes old tool output, and expands context only when the investigation requires it.
The October ranking makes this especially visible. GLM-5.3 and Qwen3.8-Max-0902 tie on the current broad Intelligence Index, but one is a cheaper text-only default and the other accepts visual evidence. DeepSeek V4.1 Flash scores below both, yet its much higher output speed may finish a long tool loop sooner. The “best” model changes when the surrounding agent, evidence type, latency budget, and acceptance test change.
One-sentence version: choose the model and the agent together.
Which Chinese Coding Model Should You Use?
Choose GLM-5.3 if you are building a difficult text-only coding agent that must stay on task across repository searches, command execution, tests, and repeated correction. It is the strongest hosted default in this ranking, but its large checkpoint and custom license make self-hosting a separate infrastructure decision.
Choose Qwen3.8-Max-0902 if frontend quality, screenshot-to-code, visual debugging, video understanding, or structured multimodal output changes the result. Expect slower output than GLM-5.3 and DeepSeek V4.1 Flash.
Choose Kimi K3 if the task is difficult, includes visual evidence, and justifies the highest API bill in the list. It is also relevant when your infrastructure team can support its enormous open-weight checkpoint and custom license.
Choose GLM-5.3 Flash if you need one cost-efficient default for coding, vision, long context, and repeated agent calls. Escalate only the tasks that fail acceptance tests or require a higher reasoning ceiling.
Choose DeepSeek V4.1 Flash if throughput, native image input, long output, or adjustable reasoning effort matters. It is particularly attractive for input-heavy agents that repeatedly process repositories, documents, screenshots, and tool histories.
There is no permanent winner. A safer production architecture keeps model selection behind a routing layer so the preferred model can change without forcing an application rewrite.
How to Call These Chinese LLM Models Through One API
GPT Proto exposes these models through the same OpenAI-compatible chat endpoint. The following cURL request uses GLM-5.3:
curl --request POST 'https://gptproto.com/v1/chat/completions' \
  --header "Authorization: Bearer $GPTPROTO_API_KEY" \
  --header 'Content-Type: application/json' \
  --data '{
    "model": "glm-5.3",
    "messages": [
      {
        "role": "system",
        "content": "You are a senior software engineer. Separate confirmed evidence from hypotheses and never claim a test passed unless you saw its output."
      },
      {
        "role": "user",
        "content": "An OAuth callback began failing after an authentication-library upgrade. Return a JSON object with diagnosis_questions, files_to_inspect, likely_failure_modes, and test_plan."
      }
    ],
    "stream": false
  }'
To test another model, change the model value:
| Model |
GPT Proto model string |
| GLM-5.3 |
glm-5.3 |
| Qwen3.8-Max-0902 |
qwen3.8-max-0902 |
| Kimi K3 |
kimi-k3 |
| GLM-5.3 Flash |
glm-5.3-flash |
| DeepSeek V4.1 Flash |
deepseek-flash |
Review the live model page before adding provider-specific reasoning or multimodal fields. The shared endpoint does not mean that every model accepts identical parameters, modalities, or reasoning controls. Test tool calls, streaming, structured output, timeouts, and error handling with the exact route used in production.
Compare all GPT Proto models before assigning production traffic. One API key and shared balance can be used to evaluate different supported models without maintaining a separate integration and prepaid account for every provider.